Local AI
A live ranking of open-weight models for English writing, with quantization filters and practical memory guidance.
Data-led investigations into how models, generation settings and evaluation protocols affect writing quality.
A live ranking of open-weight models for English writing, with quantization filters and practical memory guidance.
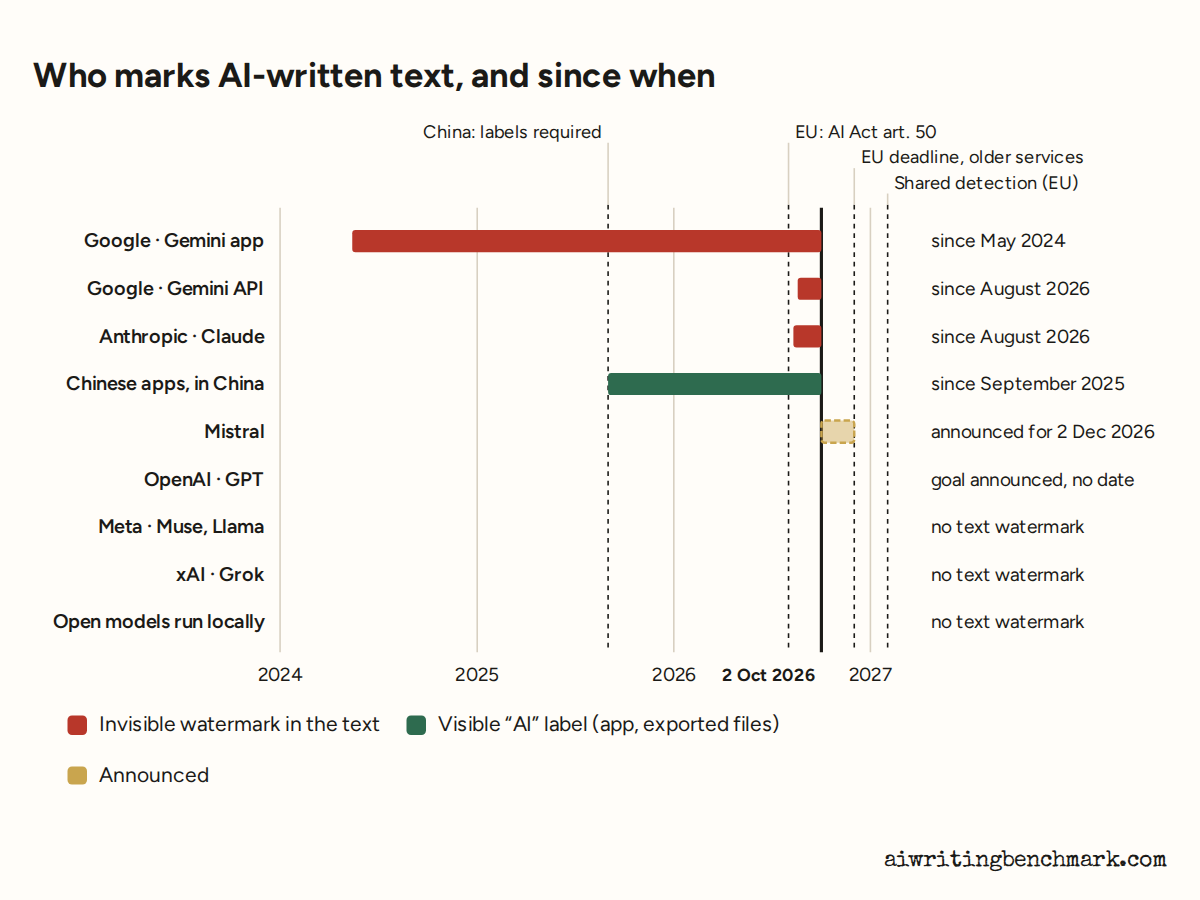
Since this summer, text from Claude and Gemini carries an invisible mark; since 5 October, so does text from ChatGPT and Codex in Europe, and OpenAI's API can be asked to add the mark. Text from Grok, Mistral, Meta AI and models run at home carries none, and Chinese services settle for a visible label. Yet outside the companies involved, nobody can check a text today.
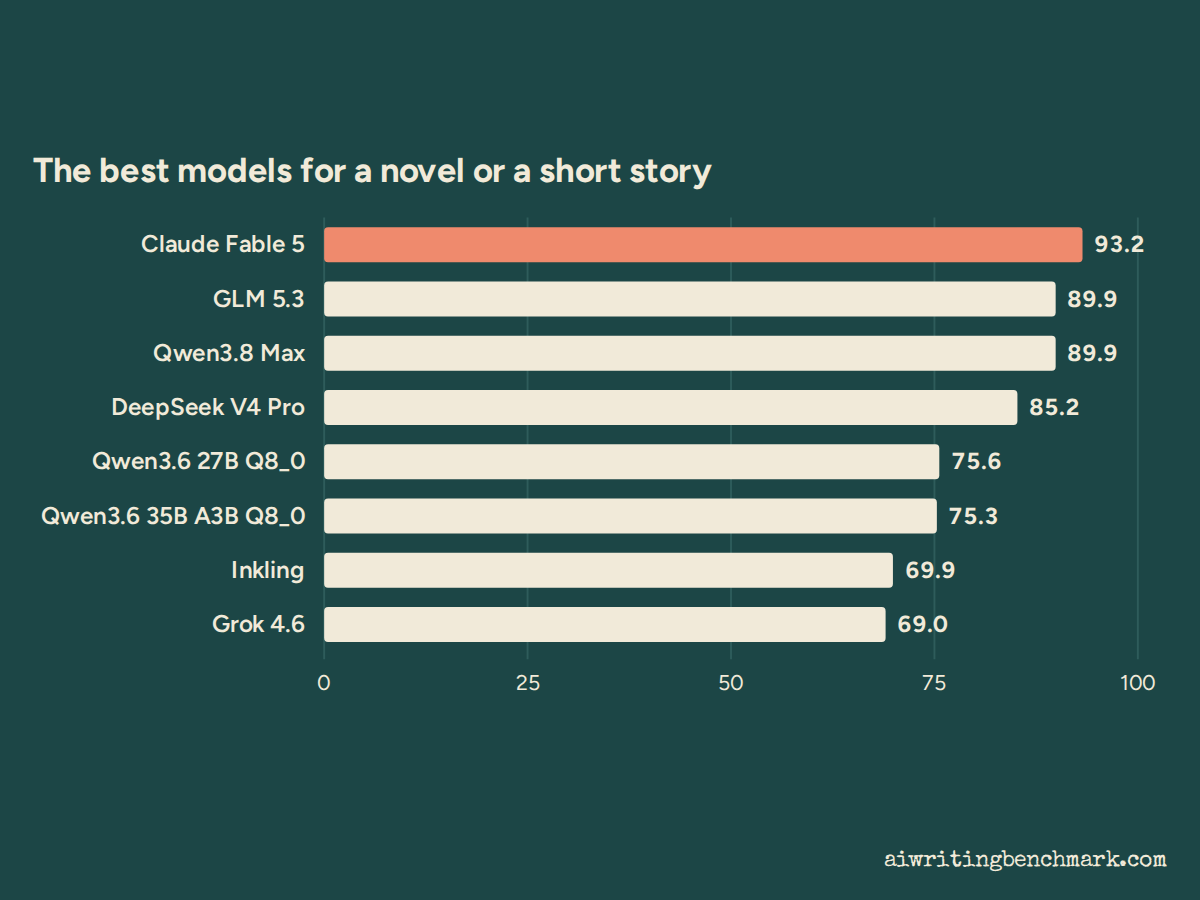
The leaderboard has one winner; your writing does not. On the duels of one kind of text alone, GPT-5.6 Sol takes fiction, Claude Opus 5 personal letters, Kimi K3 formal correspondence, and a local file you can run at home is second for cover letters. A plain guide, task by task.
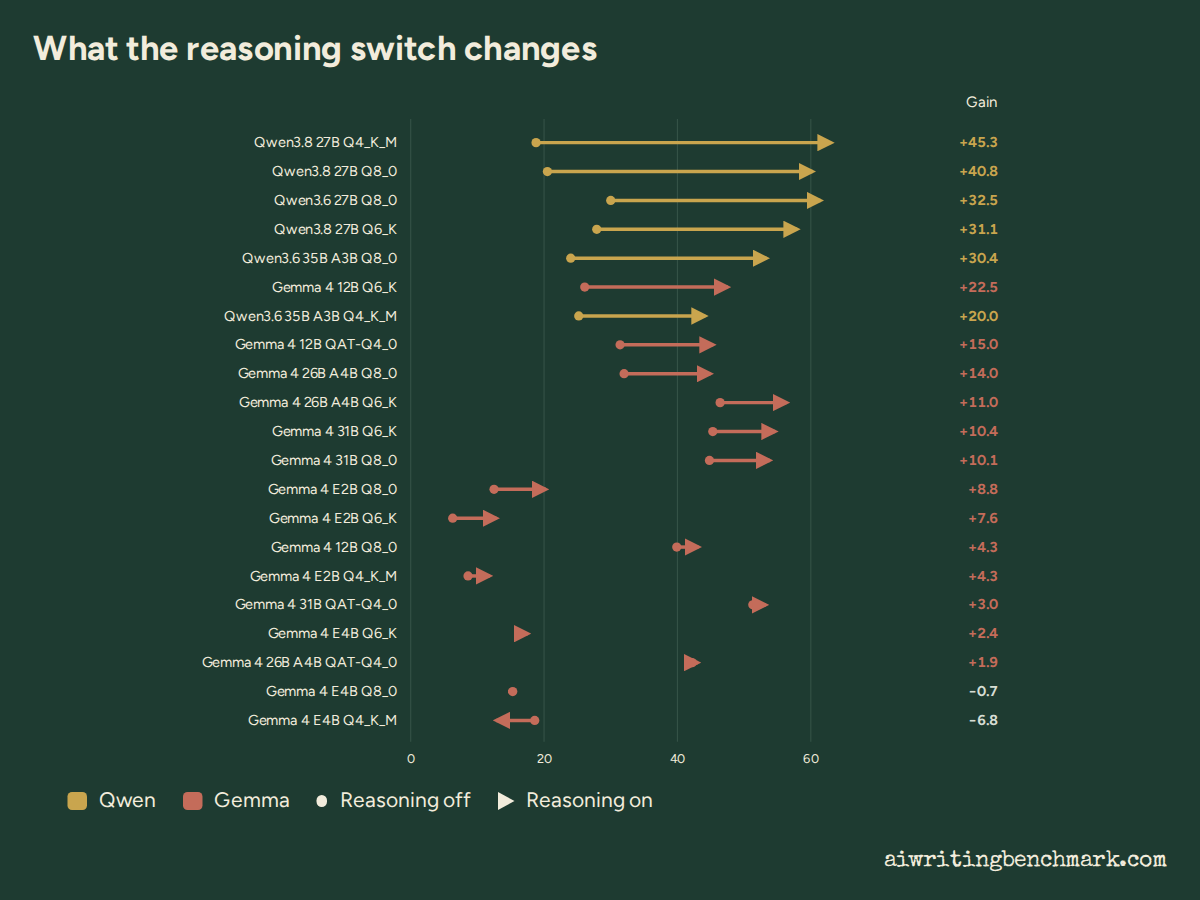
Same file, same prompts, one switch. Across 21 local builds, turning reasoning on adds 33 points on average for the Qwen family and 10 for Gemma 4 models of 12B and above; the small Gemma E2B and E4B builds gain almost nothing and sometimes lose. Qwen3.8 27B Q4_K_M gains 45 points, more than any other model.
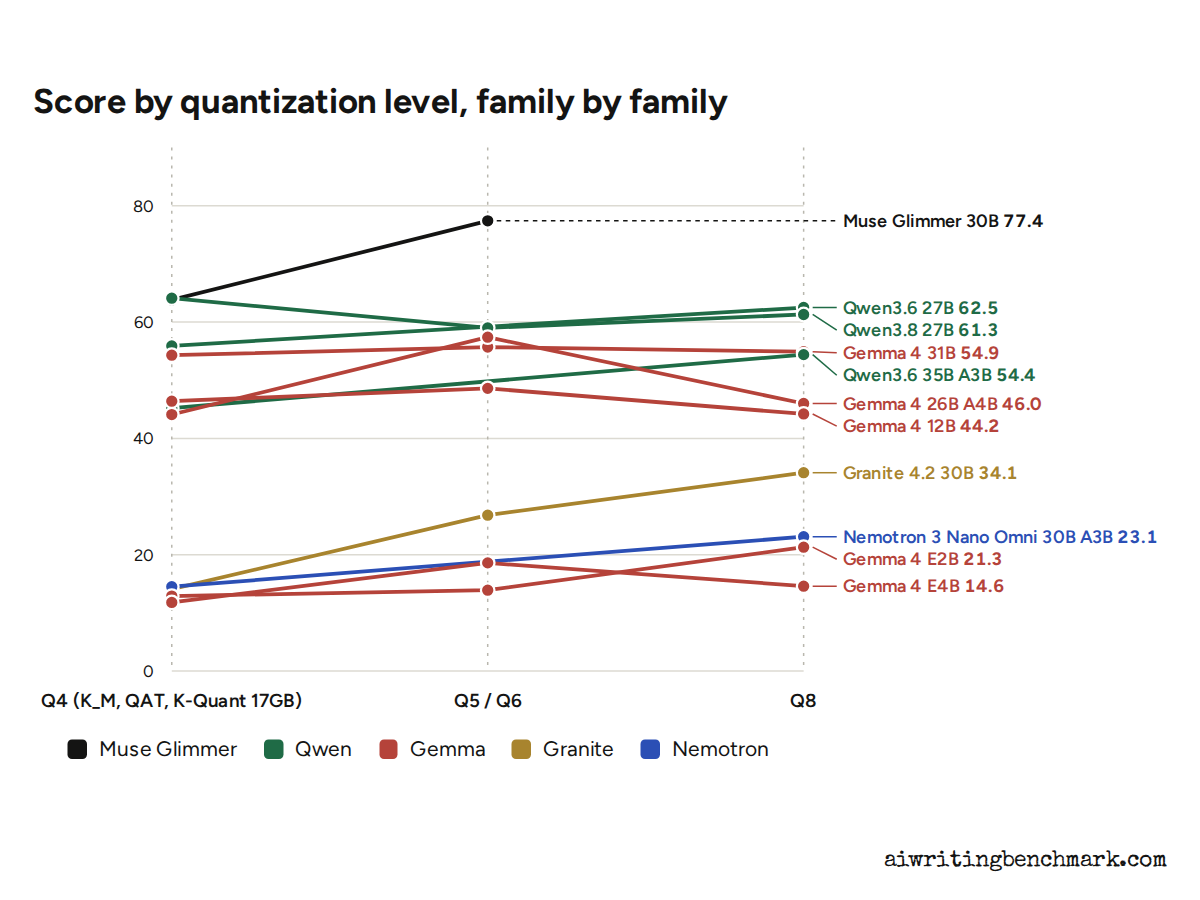
Same model, three files, three scores. Qwen3.8 27B writes English as well at Q4_K_M as at Q8_0 with a file half the size, Gemma 4 31B does not care which of its three builds you run, and Granite 4.2 30B loses twenty points between Q8 and Q4. There is no rule of thumb, only measurements.
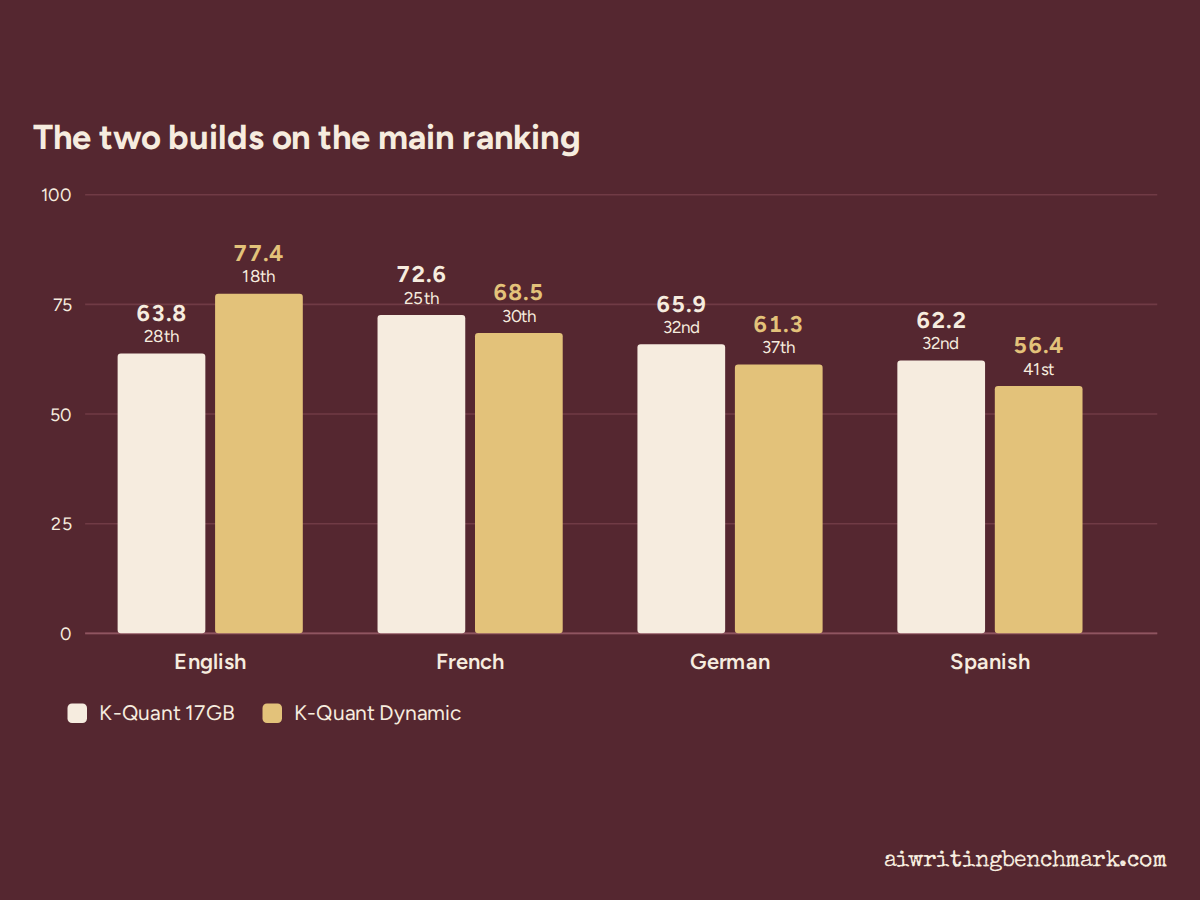
Meta's open model is the top local model for English writing at 77.4 points, ahead of every Qwen and Gemma build we run. The catch: only the K-Quant Dynamic build gets there. The smaller 17GB build scores 63.8, wins the direct duels in French, German and Spanish, and is the one to download everywhere except in English.
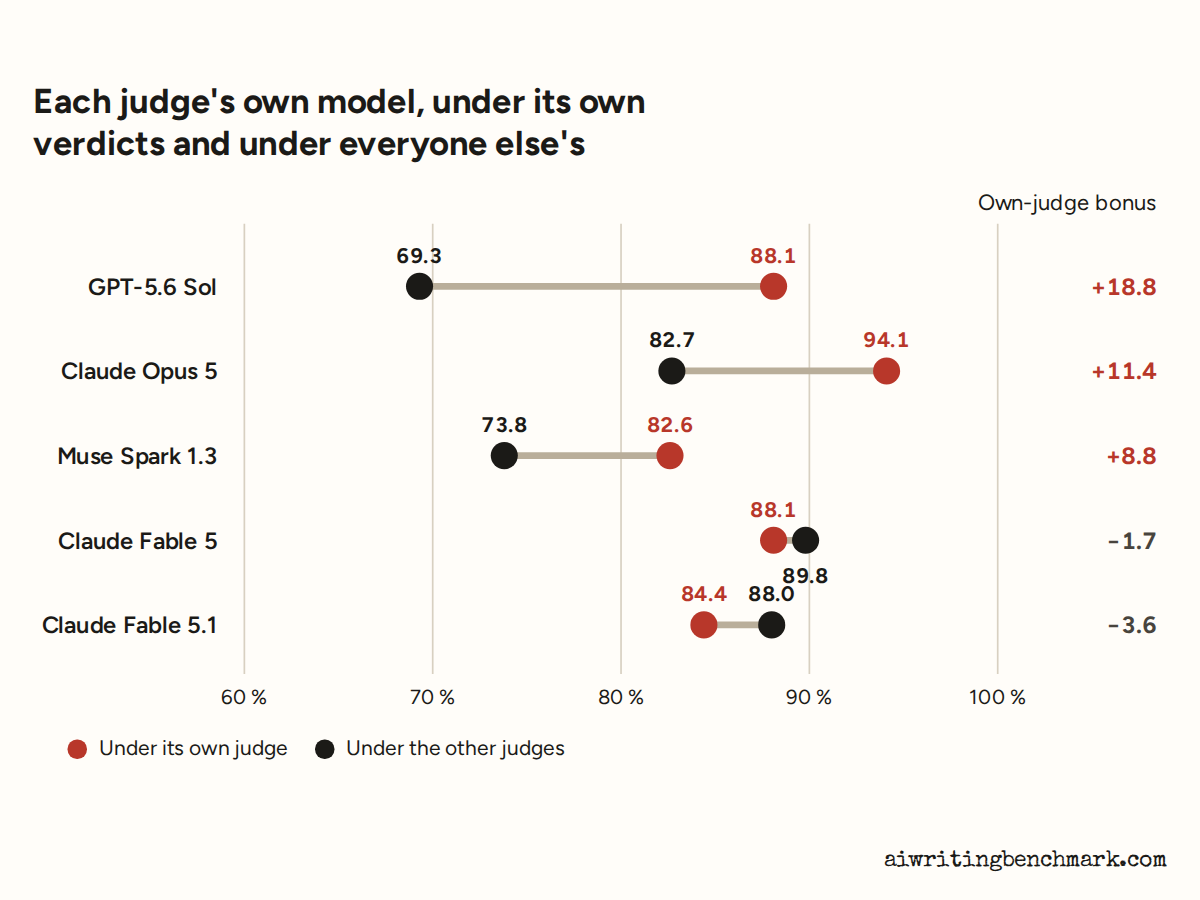
When GPT-5.6 Sol judges a duel involving GPT-5.6 Sol, its own texts collect 88% of the points; under the other judges they collect 69%. Claude Opus 5 shows the same lean, smaller. The two Claude Fable judges do the opposite and mark their own model down.
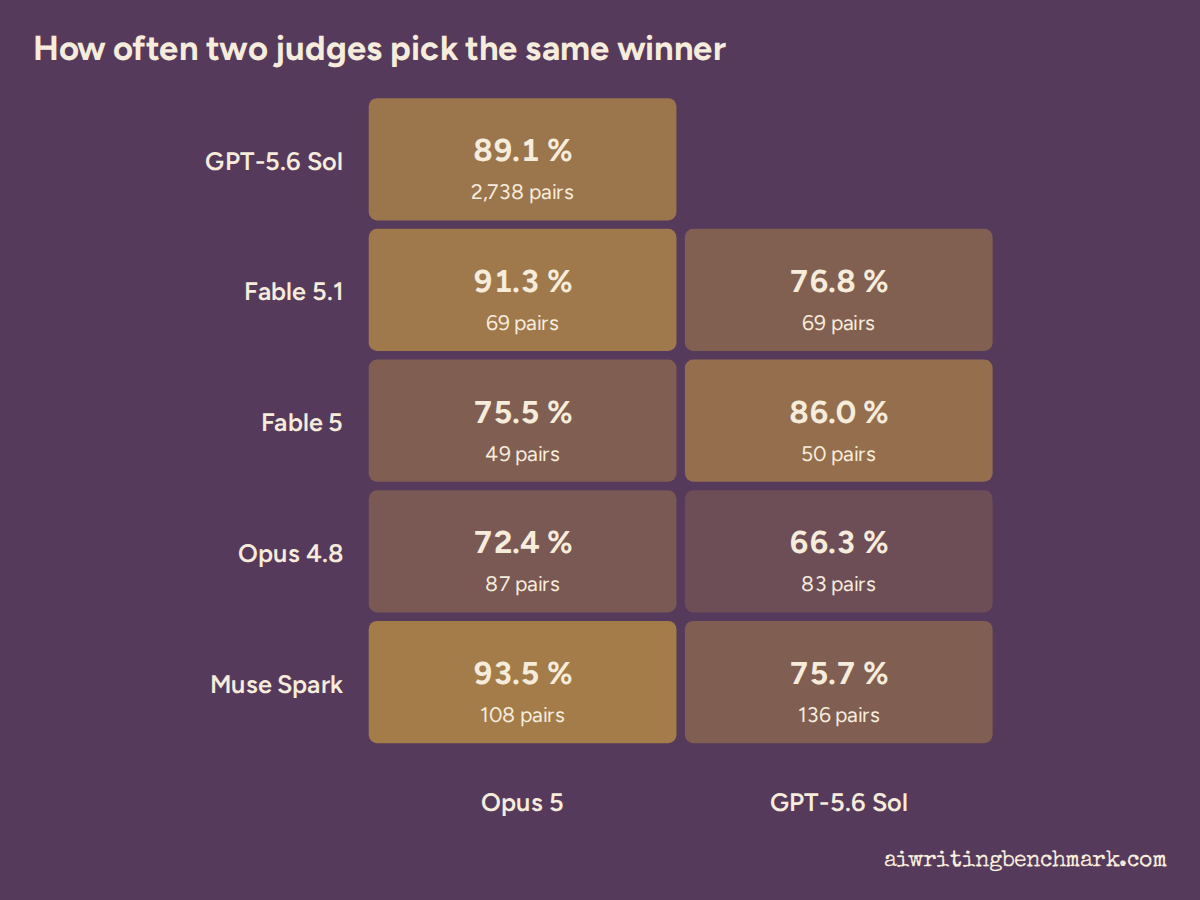
Claude Opus 5 and GPT-5.6 Sol, who supply 85% of the verdicts, side with the same model on 89% of the 2,700 model pairs they have both judged. Claude Opus 4.8 agrees with them only two times in three, and the judges do not agree at all on when to call a tie: GPT-5.6 Sol does it for one duel in 200, Claude Fable 5.1 for one in six.
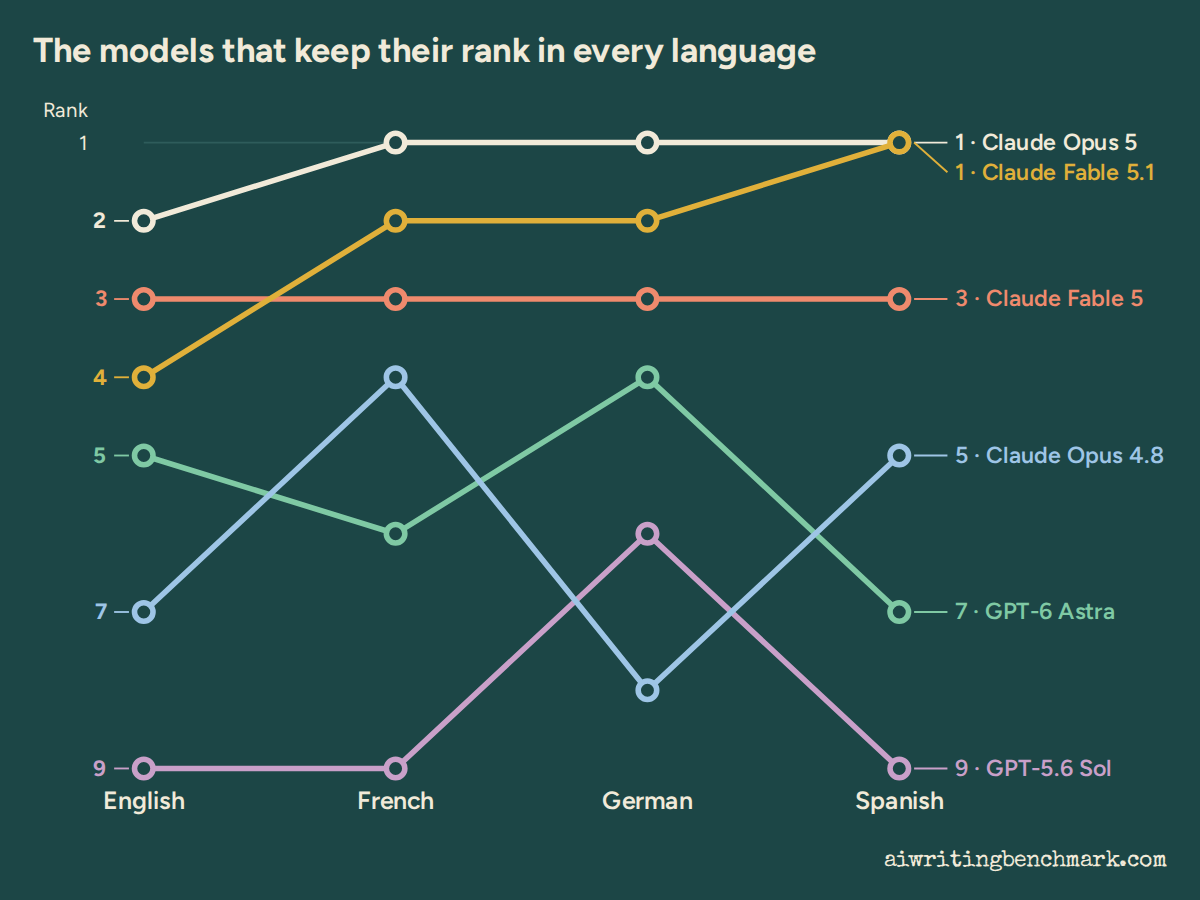
Ninety-one models are ranked in English, French, German and Spanish on the same protocol. Claude Fable 5 is third in all four; Claude Opus 5 first or second. Below the top, GLM 5.3 Flash is 10th in English and 54th in German, Grok 4.6 25th in English and 60th in French, and the best local model is a different model in every language.
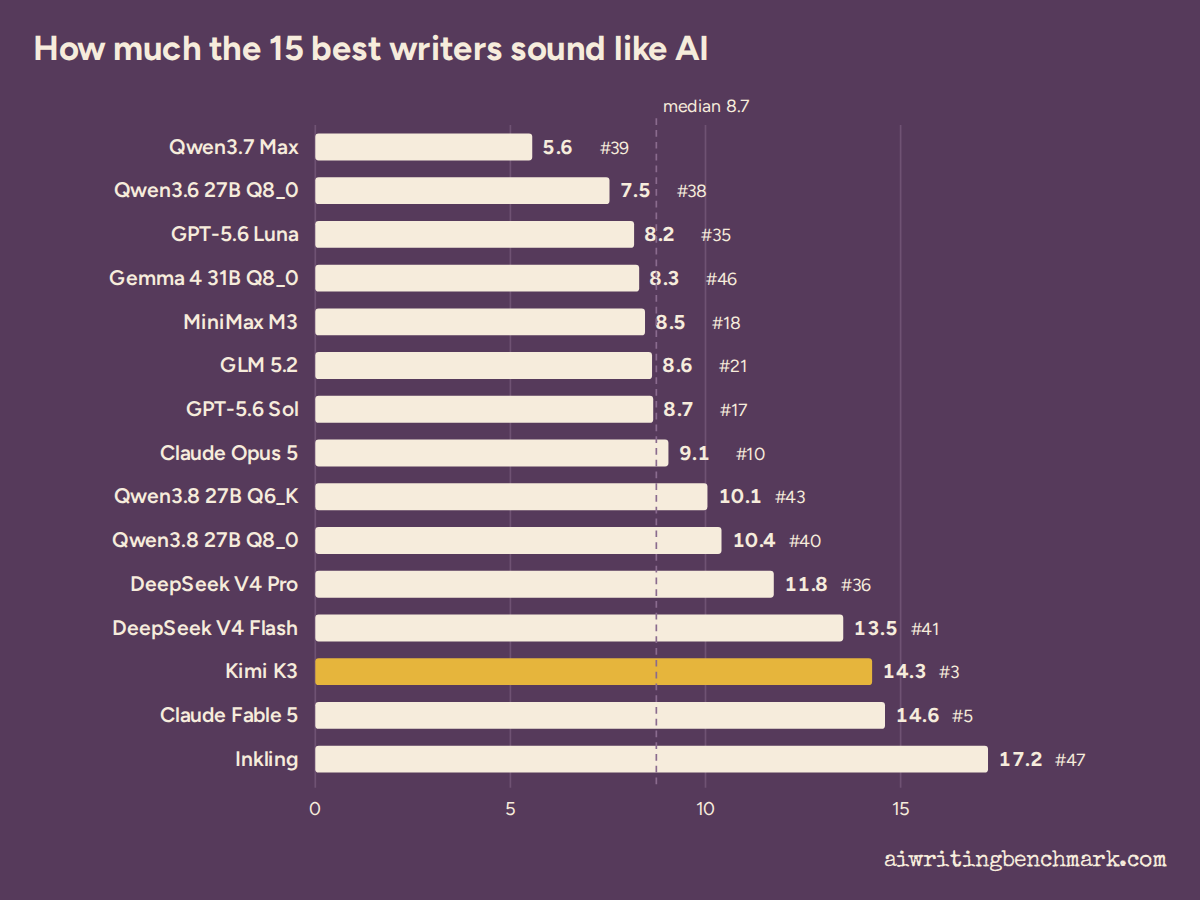
We counted the marks readers call 'AI writing' in 3,350 ranked English texts: em dashes, stock phrases, 'not X but Y', lists of three. Kimi K3 and Claude Fable 5, the two best writers on 20 September, put an em dash every 80 words. The models with the fewest tells sit in the middle of the ranking, and the word 'delve' has all but vanished.