Which AI for a novel, an email, a cover letter or an essay? The best model changes with the task
The leaderboard has one winner; your writing does not. On the duels of one kind of text alone, GPT-5.6 Sol takes fiction, Claude Opus 5 personal letters, Kimi K3 formal correspondence, and a local file you can run at home is second for cover letters. A plain guide, task by task.
The leaderboard answers one question: which model writes best in English, across every kind of text we test. That is the right question for a site and the wrong one for a writer, who is never writing “every kind of text”. You are writing a chapter, or a message to a friend, or the letter that goes with a job application. So this guide recomputes the ranking on the duels of one kind of text at a time and asks, for four common tasks, who actually wins. The figures and ranks in the text date from 20 September 2026; the charts are recomputed at each update and may differ.
For a novel or a short story: GPT-5.6 Sol and Claude Fable 5, level
The best models for a novel or a short story
Score on the duels of the category “Fiction and narrative” alone.
View as a data table
| Rank | Score | |
|---|---|---|
| 1 | Grok 4.7 💡 high | 98.1 |
| 2 | Claude Sonnet 5.5 💡 adaptive high | 97.4 |
| 3 | Claude Fable 5.1 💡 adaptive high | 97.2 |
| 4 | DeepSeek V4.1 Flash 💡 high | 95.9 |
| 4 | GLM 5.3 💡 max | 95.9 |
| 6 | GPT-6.1 Sol 💡 high | 95.7 |
| 7 | Claude Haiku 5.5 💡 adaptive high | 95.1 |
| 7 | GPT-6 Astra 💡 high | 95.1 |
On fiction alone, two models stand apart: GPT-5.6 Sol at 90.9 and Claude Fable 5 at 90.8, a tie by any honest reading. GLM 5.3 and Qwen3.8 Max follow at 89.9, then a gap of eight points to DeepSeek V4 Pro. Kimi K3, then first on the overall leaderboard, is not in the top five for fiction. If you write stories, the general ranking is misleading; this one is not.
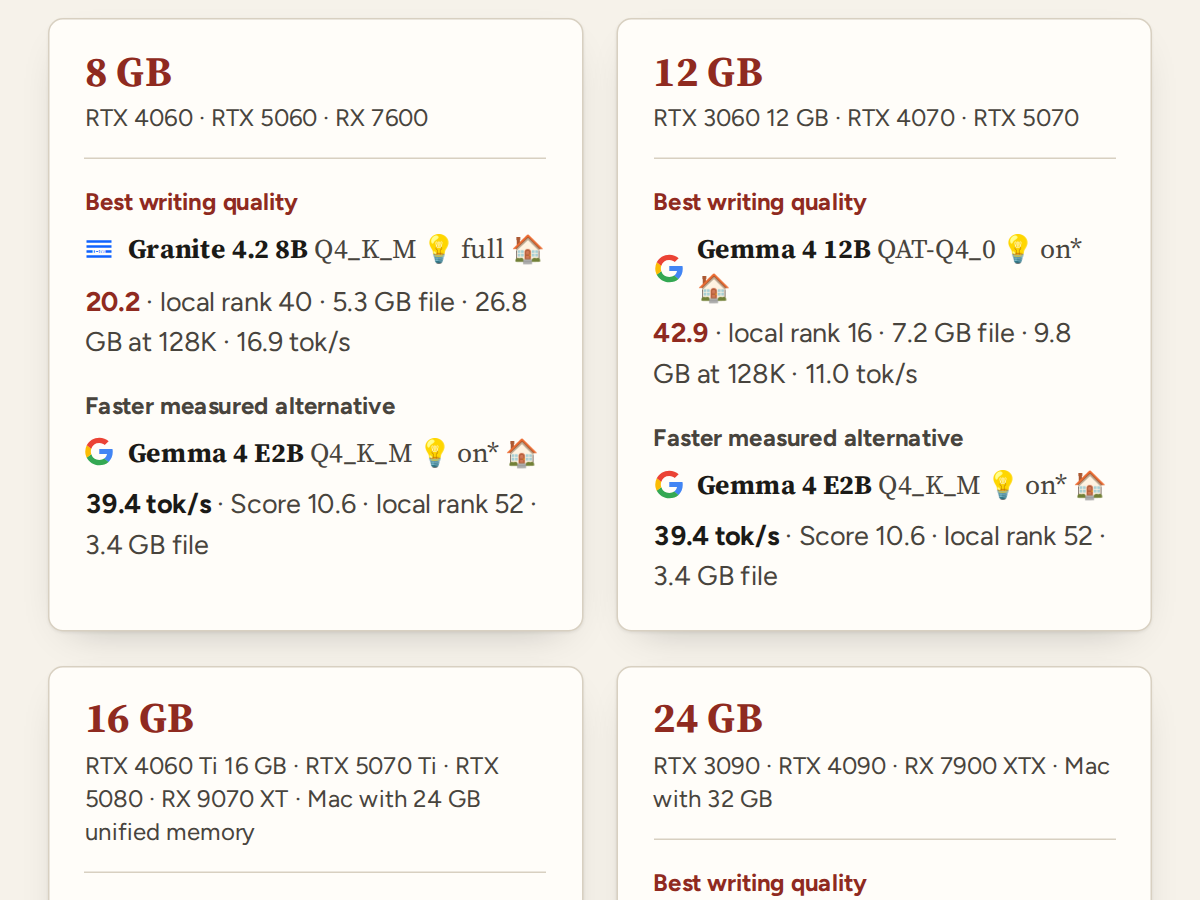
The best file you can run on your own computer is Qwen3.6 35B A3B in its Q8_0 build, at 69.6, eighth on fiction alone. That is a real gap to the cloud models, and the reason we do not pretend otherwise on the Local AI page.
For a personal email or a letter to a friend: Claude, any Claude
The best models for a personal email or letter
Score on the duels of the category “Personal communication” alone.
View as a data table
| Rank | Score | |
|---|---|---|
| 1 | Claude Opus 5.5 💡 adaptive high | 98.6 |
| 2 | GPT-6.1 Sol 💡 high | 97.5 |
| 3 | GPT-6 Astra 💡 high | 96.3 |
| 4 | Claude Fable 5 💡 adaptive high | 94.6 |
| 5 | Claude Opus 4.8 💡 adaptive high | 93.3 |
| 5 | Kimi K3 💡 enabled | 93.3 |
| 7 | Claude Opus 5 💡 adaptive high | 93.2 |
| 8 | Ling 3.1 Flash 💡 high | 92.4 |
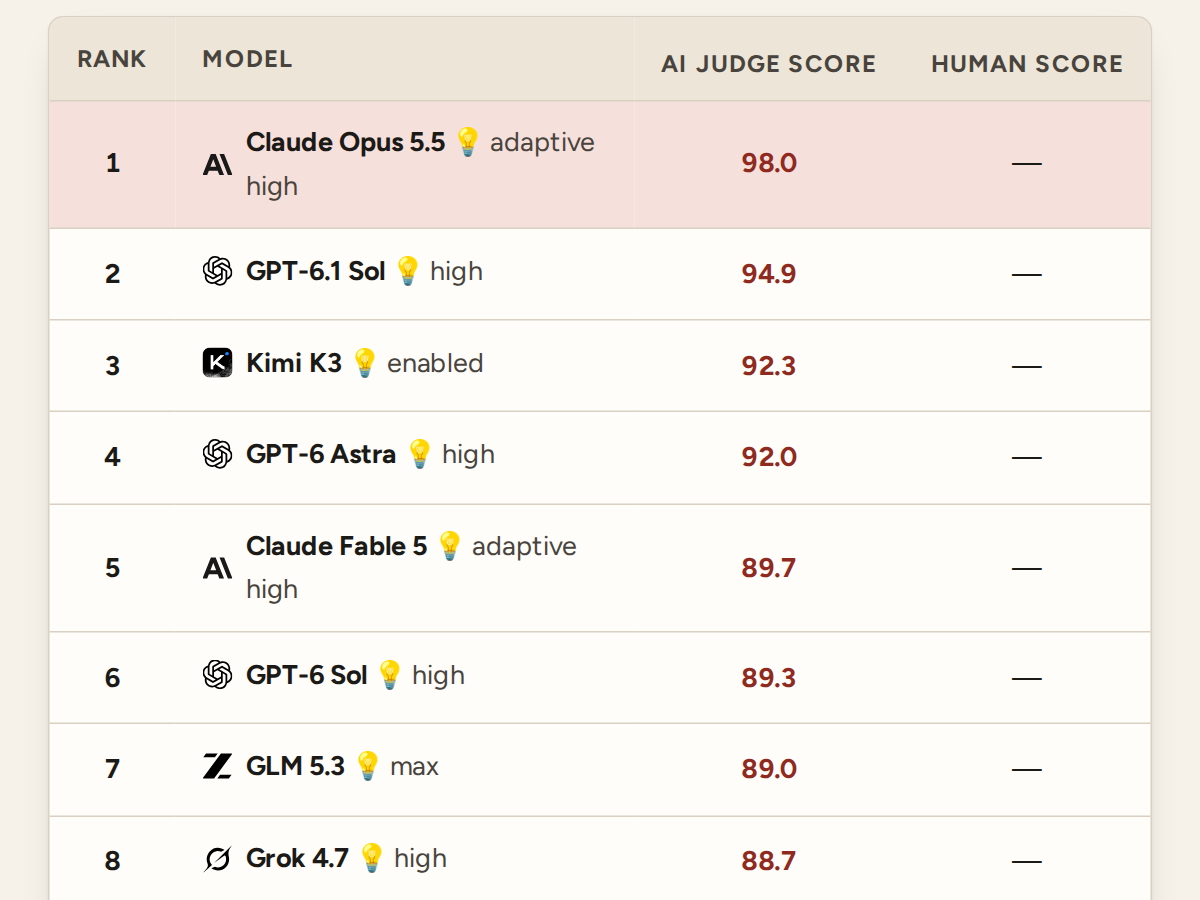
Personal writing is where the ranking is most lopsided. Claude Opus 5 leads at 97.6, Claude Fable 5 is at 96.9, and three of the top five are Anthropic models; GPT-6 Astra and Kimi K3 fill the other two places. The differences between the leaders are within a point or two, so the choice among them can rest on price or habit.
Locally, Muse Glimmer 30B in its K-Quant Dynamic build is the best file for personal writing, at 74.1, and needs about 23 GB with a full 128K context. The K-Quant 17GB build is the choice for 24 GB machines.
For a cover letter or any formal letter: Kimi K3, then a local surprise
The best models for a cover letter or a formal letter
Score on the duels of the category “Professional and administrative” alone.
View as a data table
| Rank | Score | |
|---|---|---|
| 1 | Claude Sonnet 5.5 💡 adaptive high | 93.4 |
| 2 | Kimi K3 💡 enabled | 91.1 |
| 3 | Muse Glimmer 30B K-Quant Dynamic 💡 high 🏠 | 88.1 |
| 4 | Grok 4.7 💡 high | 87.5 |
| 5 | GPT-6.1 Sol 💡 high | 85.3 |
| 6 | GLM 5.3 💡 max | 84.7 |
| 7 | Claude Fable 5 💡 adaptive high | 83.5 |
| 8 | GPT-6 Astra 💡 high | 82.0 |
Formal and administrative writing has a different winner. Kimi K3 leads at 91.2, ahead of Claude Fable 5 at 87.5, GPT-5.6 Sol at 86.6 and GLM 5.3 at 86.1. Second place goes to a file you can run at home: Muse Glimmer 30B K-Quant Dynamic, at 89.4. For cover letters, complaint letters and letters to the administration, the local option is not a compromise.
For an essay or an explanation: Claude Fable 5 or Kimi K3
The best models for an essay or an explanation
Score on the duels of the category “Explanation and popularization” alone.
View as a data table
| Rank | Score | |
|---|---|---|
| 1 | Kimi K3 💡 enabled | 95.0 |
| 2 | Claude Fable 5 💡 adaptive high | 93.1 |
| 3 | DeepSeek V4.1 Flash 💡 high | 93.0 |
| 4 | Claude Fable 5.1 💡 adaptive high | 91.6 |
| 5 | Muse Spark 1.3 💡 high | 88.8 |
| 6 | GLM 5.3 💡 max | 88.1 |
| 7 | Hy3 💡 high | 87.8 |
| 8 | Gemini 3.7 Flash 💡 medium | 85.3 |
For explaining something clearly, the kind of writing a student essay or a blog explainer needs, Claude Fable 5 leads at 95.4 and Kimi K3 at 95.0 is level with it; DeepSeek V4.1 Flash and Claude Fable 5.1 follow at 92. Structured documents and reports, a neighbouring task, have their own ranking where GLM 5.3 leads and two local files, Gemma 4 12B Q6_K and Qwen3.8 27B Q6_K, are second and third at 87. If your essay has headings and a table, look at that category on the leaderboard as well.
Why the winner changes, and how to use this
A single score averages every kind of text, and the models are not equally good at everything: on 20 September, Claude Fable 5 led six of the ten categories yet was only third overall, and Kimi K3 led the overall ranking while leading a single category. The general ranking rewards consistency; your task rewards the specialist.
Two habits make this guide useful. First, on the leaderboard, filter by the kind of writing you do before you read the ranks. Second, when two models are within a couple of points, read their texts side by side in the compare tool: the score says who wins more often, the texts say why.
Conclusion
Pick the model for the text, not the other way round. For fiction, GPT-5.6 Sol and Claude Fable 5 are level and well ahead of everyone else. For a personal email or letter, any current Claude; Claude Opus 5 leads. For a cover letter or any formal letter, Kimi K3, with Claude Fable 5 close behind. For an essay or an explanation, Claude Fable 5 or Kimi K3. If you would rather keep your drafts on your own machine, Muse Glimmer 30B is the file to download for letters and explanations, and Qwen3.6 for fiction.