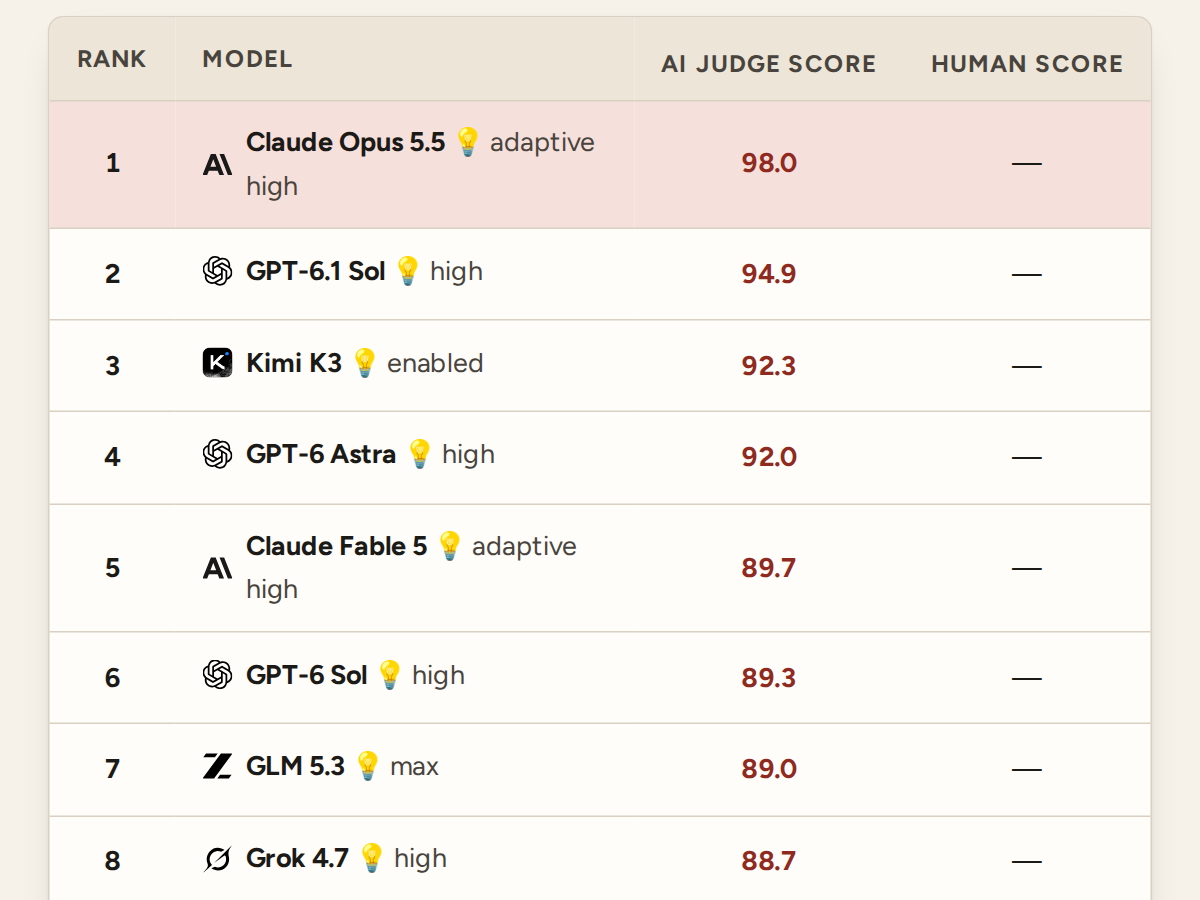
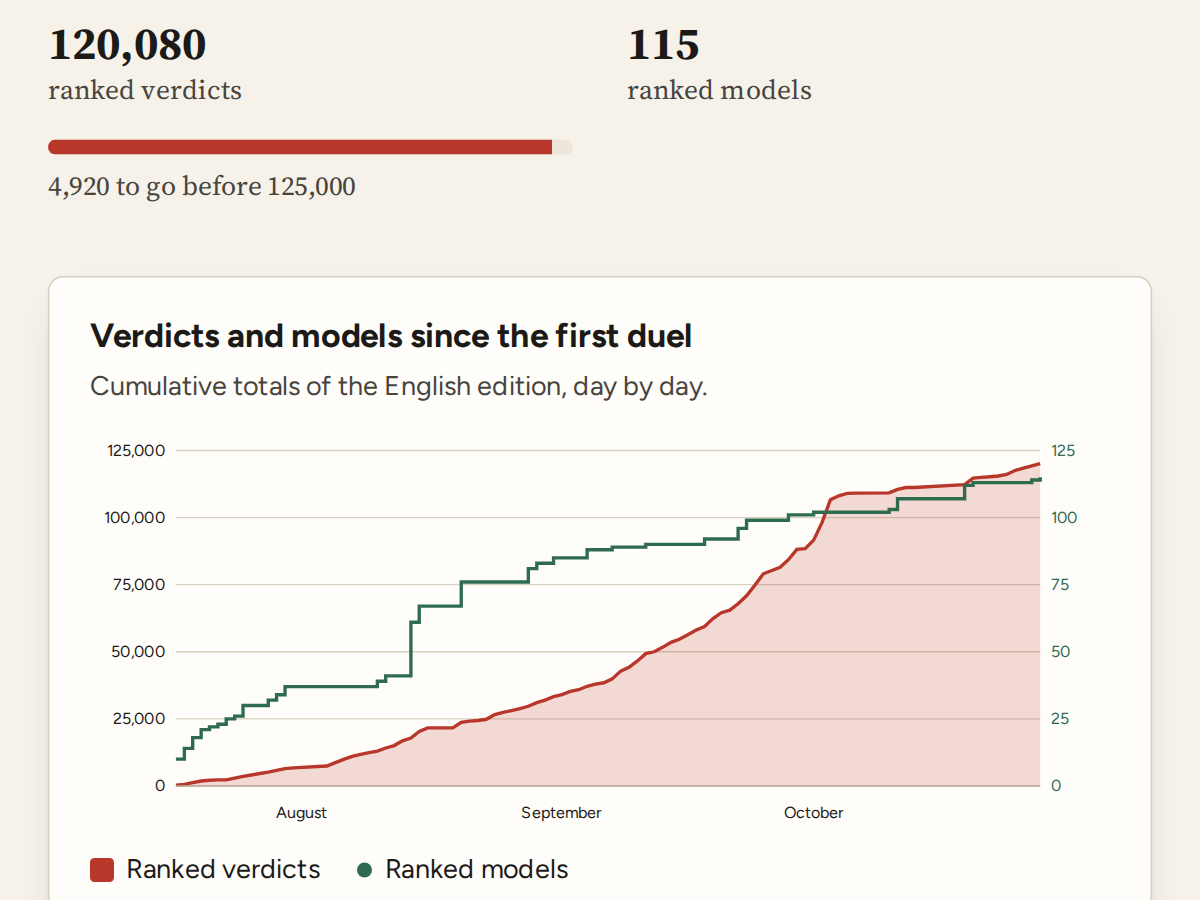
My name is Johannes Eva, and I have been building websites for 27 years. The AI Writing Benchmark began with a gap: no existing leaderboard measured what interested me, the writing quality of AI models in English and other languages.
Public benchmarks mainly focus on code, mathematics and reasoning. The small part devoted to writing is usually evaluated only in English. Here, only the quality of the generated texts counts. The prompts are written directly in each language, and the answers are compared blindly.
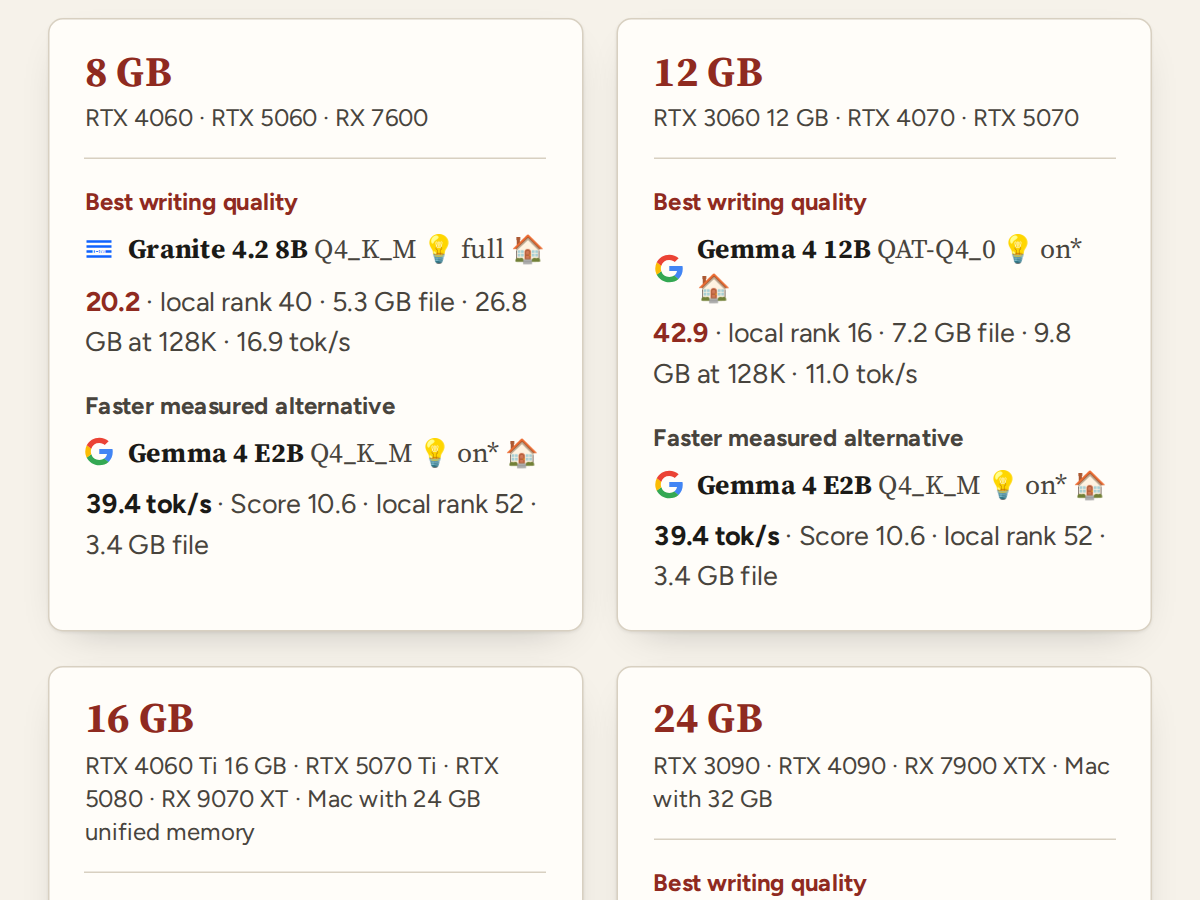
Models that can run at home have a special place here. Gemma 4, Qwen 3.6 and 3.8, Ling 3.0 Flash, Muse Glimmer and Granite 4.2, among others, are marked with 🏠. They were run locally, in several quantizations, with reasoning on and off. Local generation has been suspended since 22 September 2026; the responses already generated keep being judged, so their scores still move.
This site is a personal project. No model provider pays me, and I have no reason to favour one model over another.
The machines used for local models
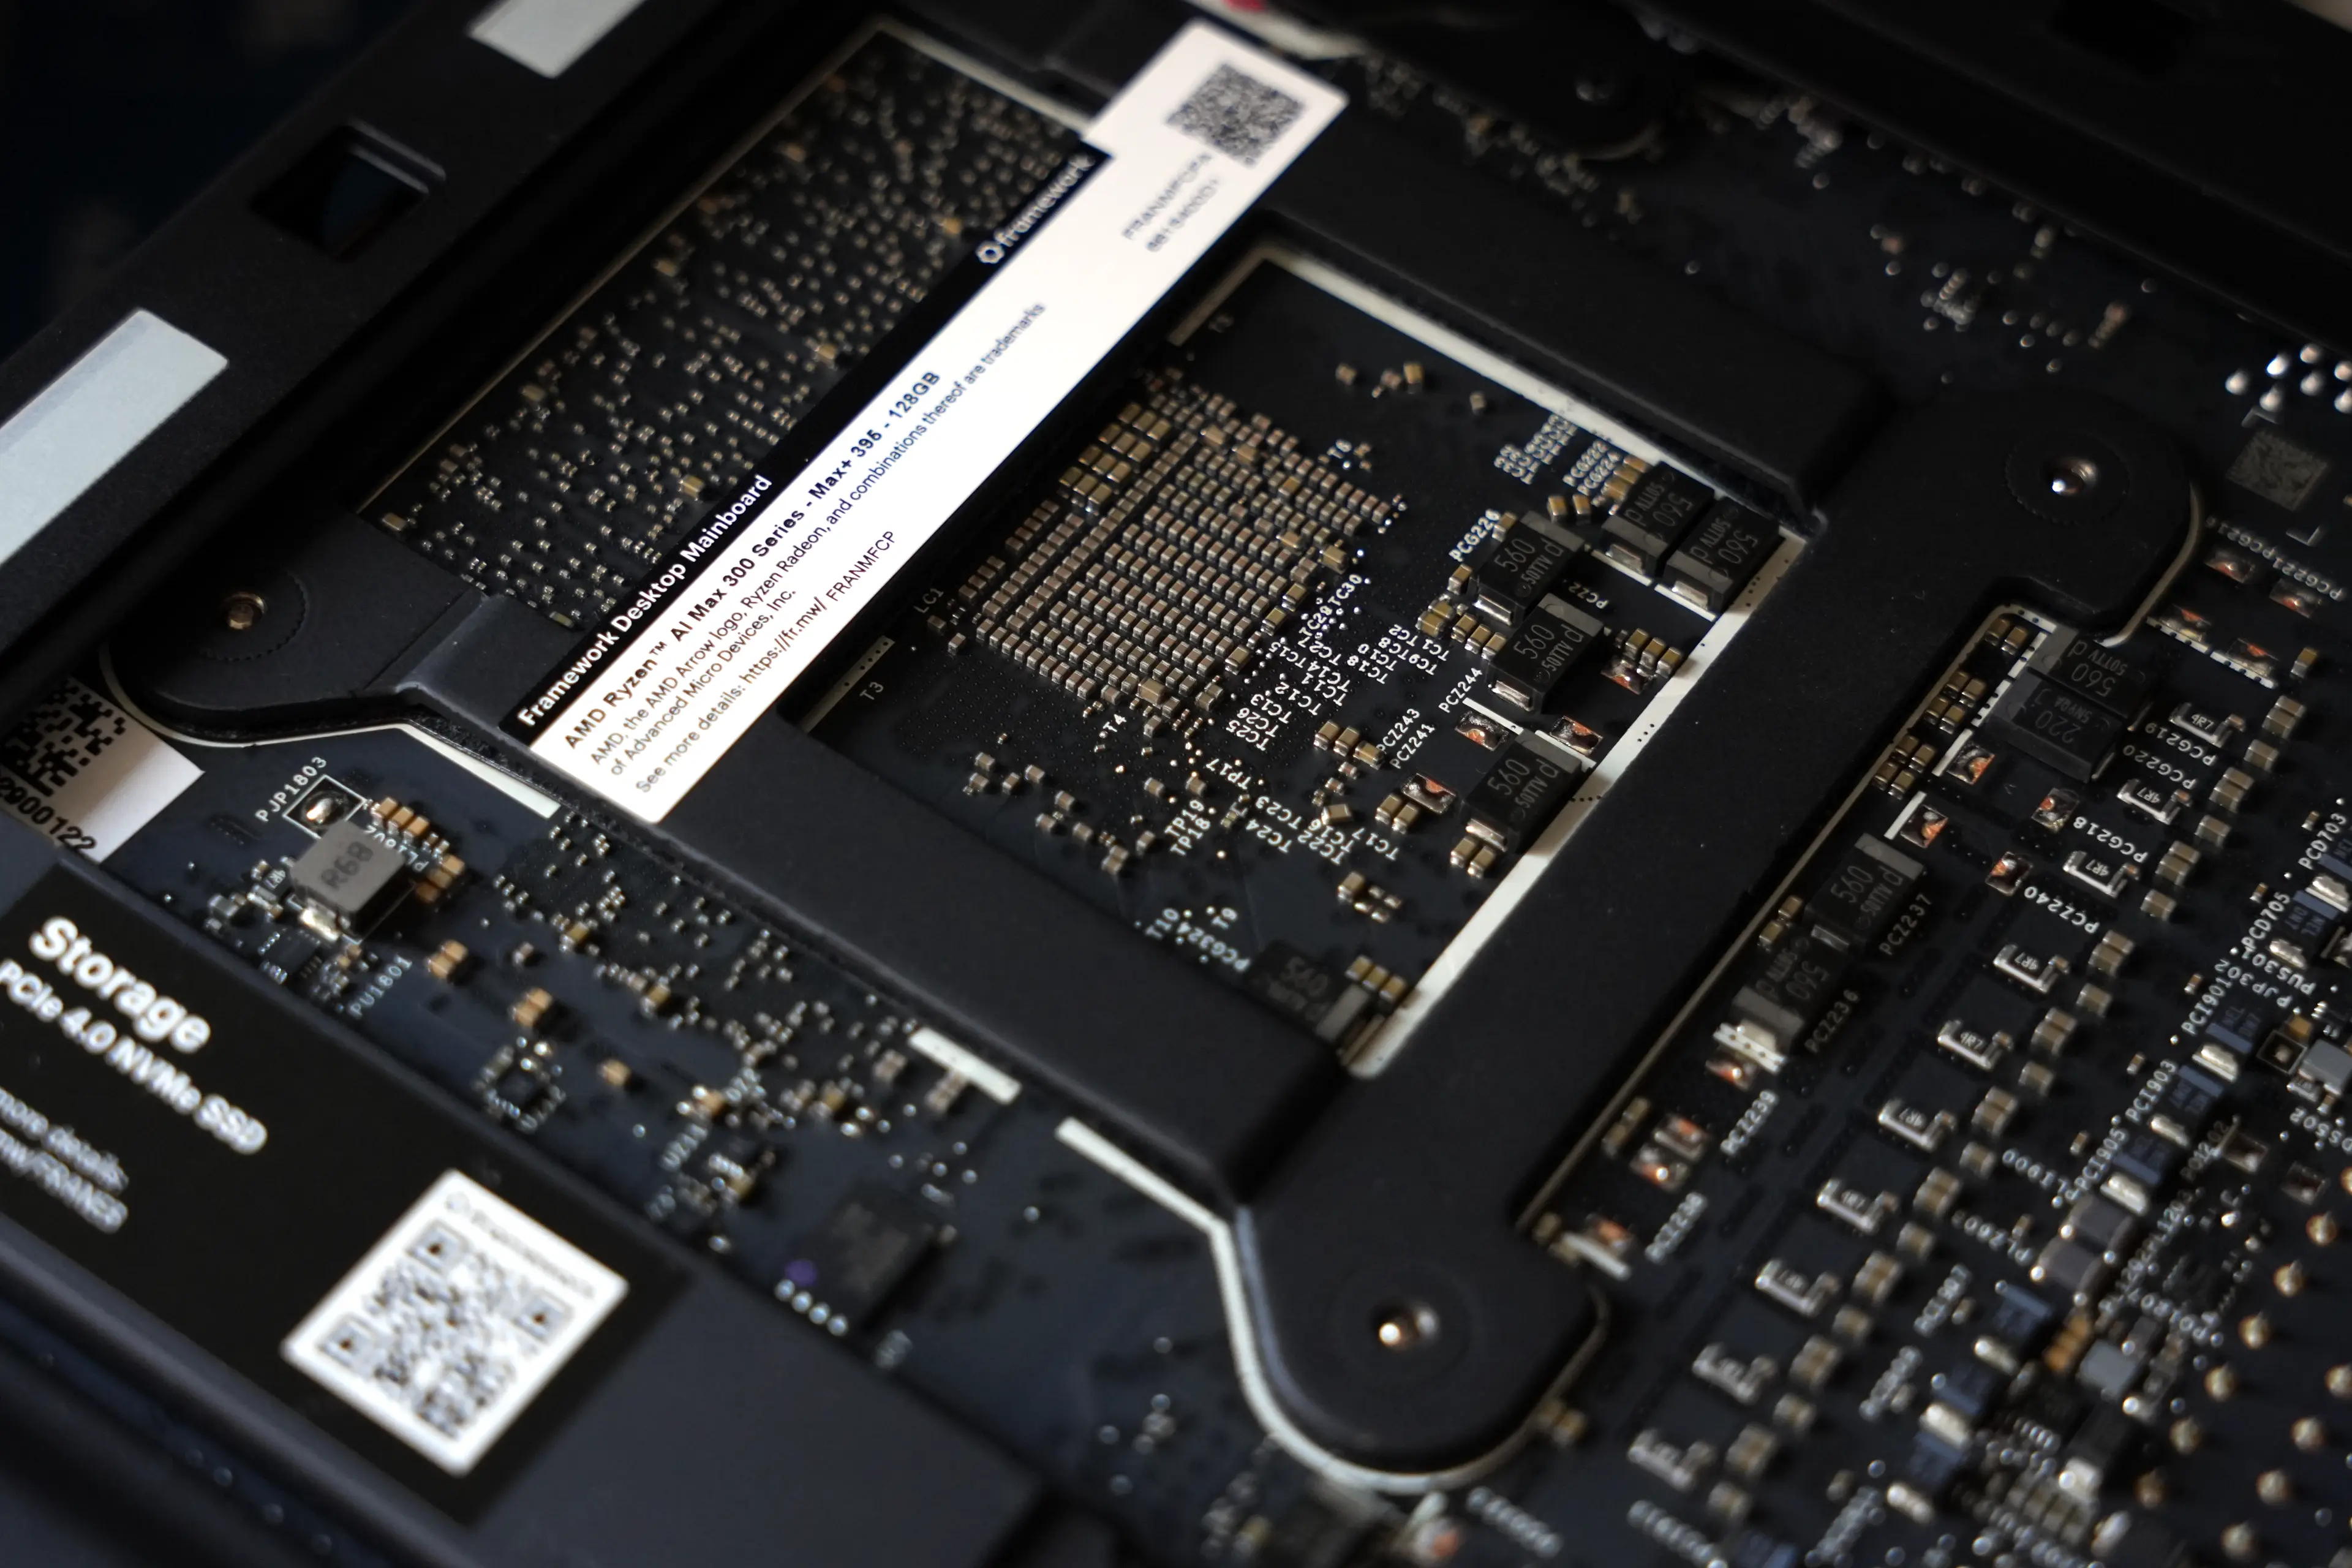
- Computer
- Framework Desktop, AMD Ryzen AI Max 300 Series, revision A6
- Processor
- AMD Ryzen AI Max+ 395, 16 cores and 32 threads, up to 5.19 GHz
- Graphics
- AMD Radeon 8060S integrated graphics
- Memory
- 128 GB of unified memory, shared by the processor and graphics unit
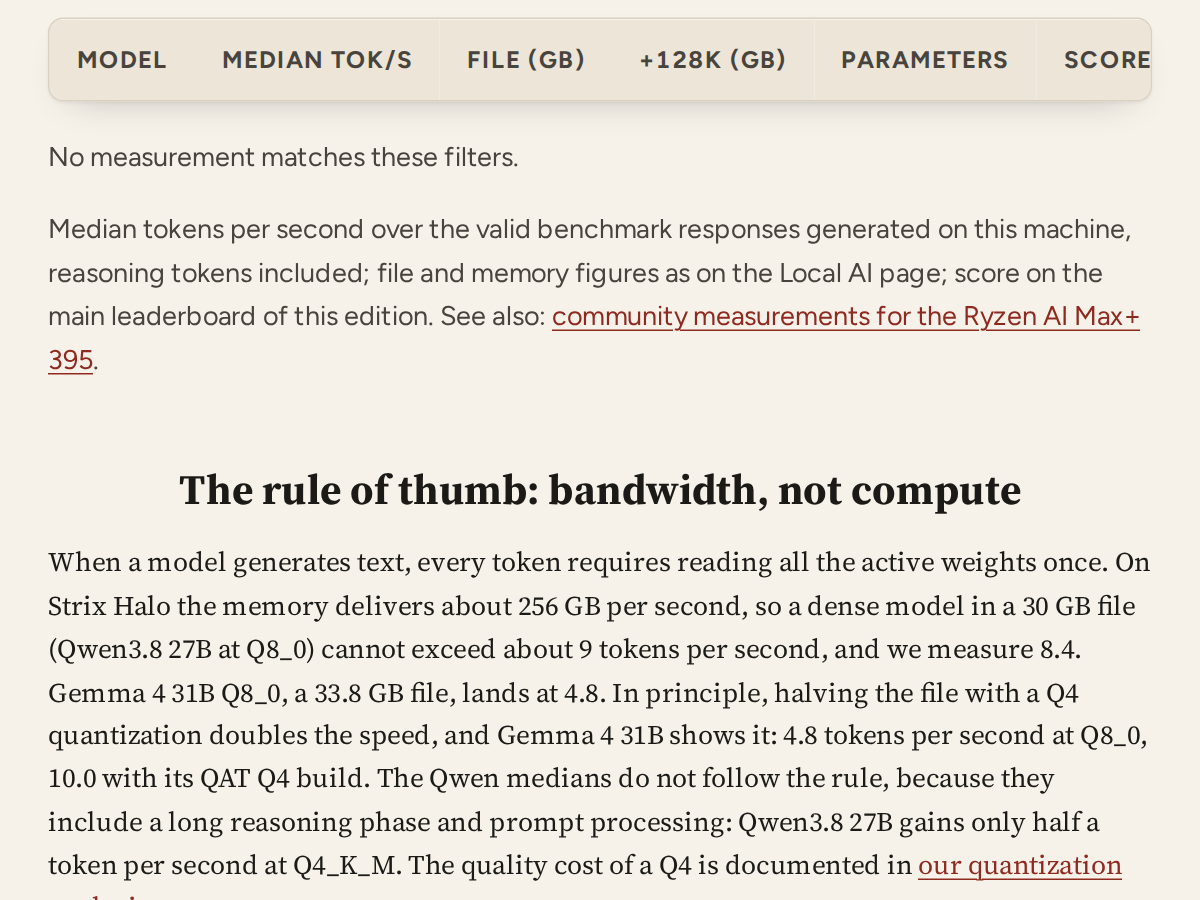
Local models ran on a Framework Desktop with an AMD Ryzen AI Max+ 395 and 128 GB of unified memory available to both the processor and graphics unit. This made it possible to load models larger than most consumer graphics cards can hold. A second machine with an NVIDIA GeForce RTX 5070 Ti generated some of the lighter models.
Generation speeds measured on this machine, model by model and quantization by quantization, are on the Strix Halo speed page.