Same model, four languages: the top barely moves, the middle swings by forty places
Ninety-one models are ranked in English, French, German and Spanish on the same protocol. Claude Fable 5 is third in all four; Claude Opus 5 first or second. Below the top, GLM 5.3 Flash is 10th in English and 54th in German, Grok 4.6 25th in English and 60th in French, and the best local model is a different model in every language.
The four editions of this benchmark share the same models, the same judges and the same protocol. Only the prompts change: 240 per language, written natively. So when a model ranks 10th in English and 54th in German, the difference is not the method. It is the model.
Ninety-one model variants have a published score in all four languages (data as of 19 September 2026). Here is how far they travel. The figures and ranks in the text date from that export; the charts are recomputed at each update and may differ.
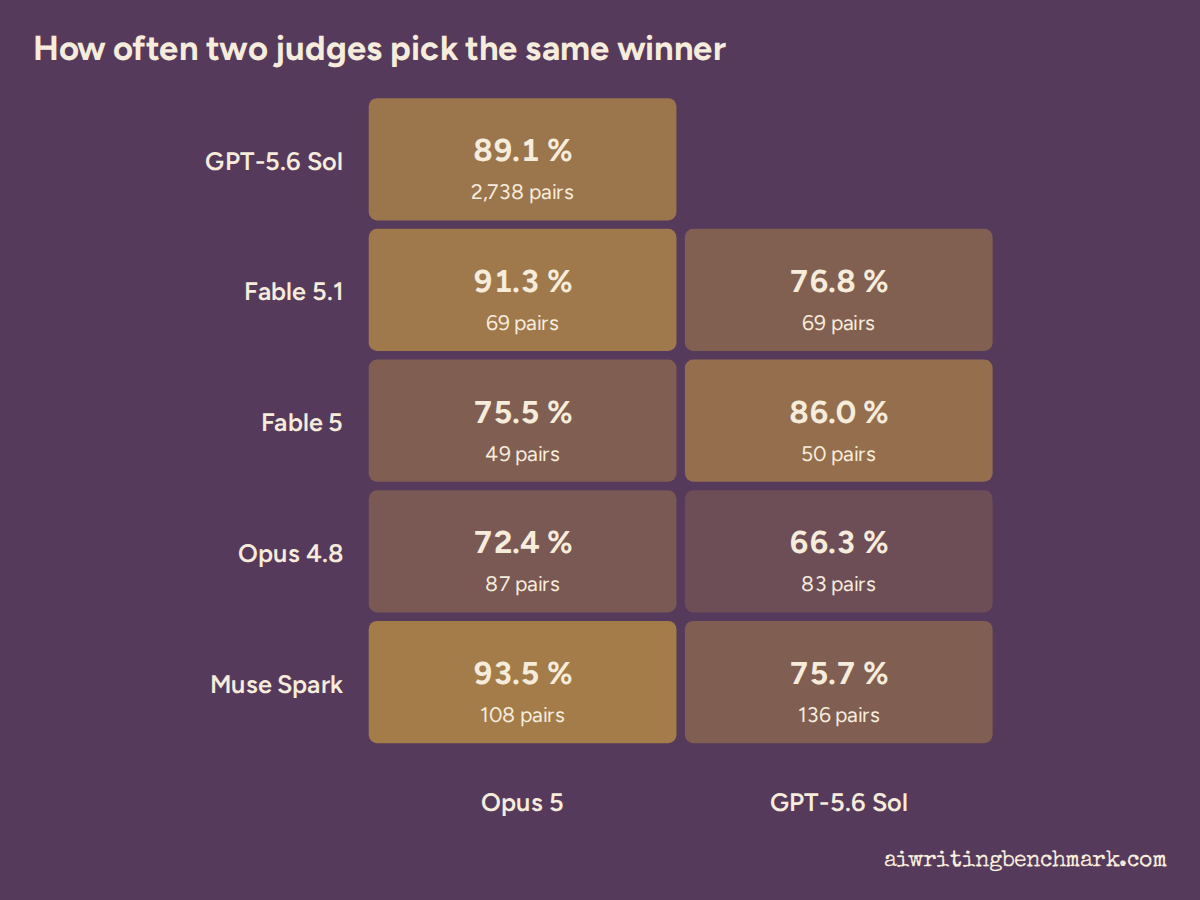
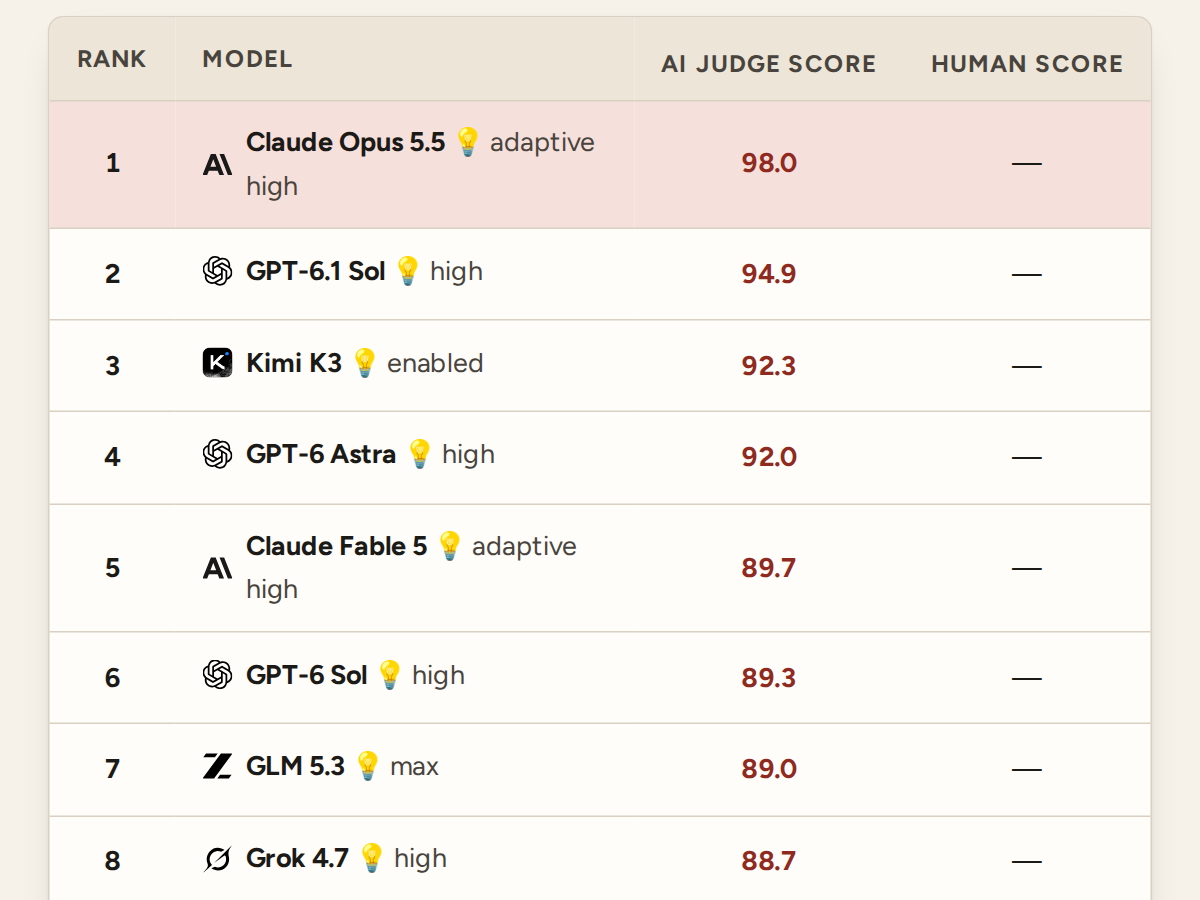
The six steadiest models: Claude Fable 5 is third everywhere, Claude Opus 5 first or second
The models that keep their rank in every language
Rank in each edition of the six models whose rank moves least across the four languages. Rank 1 is at the top.
View as a data table
| Model | English | French | German | Spanish |
|---|---|---|---|---|
| Claude Fable 5 | 3 | 3 | 3 | 3 |
| Claude Opus 5 | 2 | 1 | 1 | 1 |
| Claude Fable 5.1 | 4 | 2 | 2 | 1 |
| GPT-5.6 Sol | 9 | 9 | 6 | 9 |
| GPT-6 Astra | 5 | 6 | 4 | 7 |
| Claude Opus 4.8 | 7 | 4 | 8 | 5 |
The six models whose rank moved least were Claude Fable 5, Claude Opus 5, Claude Fable 5.1, GPT-5.6 Sol, GPT-6 Astra and Claude Opus 4.8. None moved by more than four places and none left the top nine in any language. GPT-5.6 Sol was ninth in three languages and sixth in German. Kimi K3 also moved four places, as many as Claude Opus 4.8, and just misses the chart: first in English, fourth or fifth elsewhere. It was the only open-weight model near the top in all four languages.
The scores tell the same story with a nuance: Claude Opus 5 scores 93.7 in English and 99.5 in French, meaning the French field is easier for it to dominate, not that it writes better French than English. Scores are only comparable within a language.
Below the top, the same model can be 10th in one language and 54th in another
Same model, four ranks
Rank in each edition of the six models with the widest spread, among the 91 models ranked in all four languages. Rank 1 is at the top.
View as a data table
| Model | English | French | German | Spanish |
|---|---|---|---|---|
| GLM 5.3 Flash | 10 | 27 | 54 | 44 |
| Qwen3.8 27B Q4_K_M | 27 | 17 | 58 | 54 |
| Ling 3.0 Flash Q4_K_M | 66 | 35 | 76 | 65 |
| Grok 4.6 | 25 | 60 | 52 | 21 |
| Hy3 | 15 | 43 | 25 | 51 |
| Seed 2.1 Turbo ↯ | 57 | 28 | 61 | 43 |
GLM 5.3 Flash is a top-ten model in English and a bottom-half model in German. Grok 4.6 is strong in English and Spanish, weak in French and German. Hy3 is good in English, mediocre everywhere else. These are not sampling accidents: each model has between 1,000 and 1,800 ranked duels per language, and the confidence intervals are a few points wide.
Local models show the same pattern with an extra twist. Qwen3.8 27B at Q4_K_M is the best local model in French, 17th overall, and one of the weakest in German, 58th. The same file, on the same machine, with the same reasoning setting. Whatever Qwen learned about French, it did not learn about German.
The best local model is a different model in every language, and the gap to the cloud is widest in German and Spanish
Best model versus best local model
Score of the leader of each edition and of its best locally run model. Scores are only comparable within a language.
- Best model
- Best local model
View as a data table
| Best model | Best local model | |
|---|---|---|
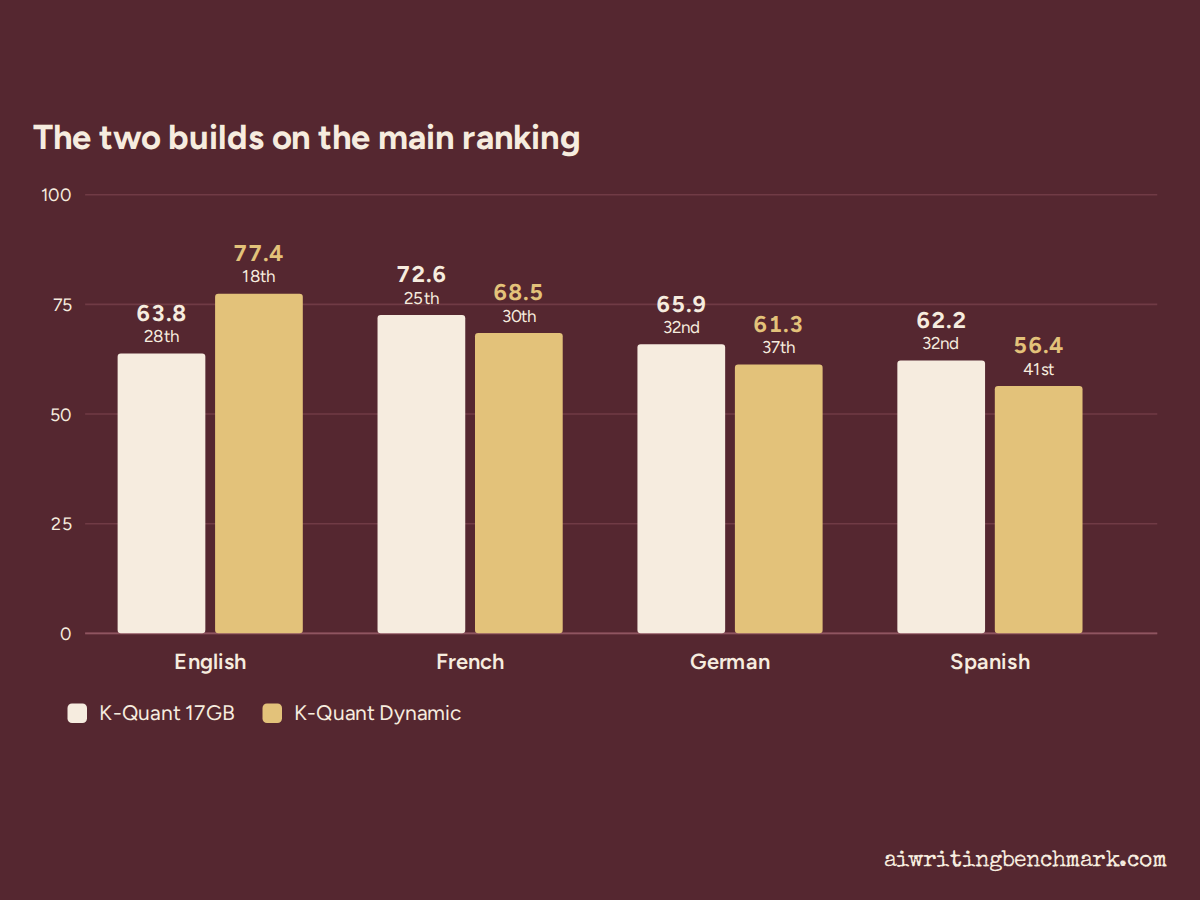
| English | Kimi K3, 93.8 | Muse Glimmer 30B K-Quant Dynamic, 77.4 (18th) |
| French | Claude Opus 5, 99.5 | Qwen3.8 27B Q4_K_M, 76.6 (17th) |
| German | Claude Opus 5, 98.0 | Gemma 4 31B Q8_0, 72.1 (24th) |
| Spanish | Claude Fable 5.1, 98.3 | Qwen3.8 27B Q8_0, 70.4 (23rd) |
Muse Glimmer 30B wins the local field in English, Qwen3.8 27B in French and Spanish, Gemma 4 31B in German. Nobody who reads only one leaderboard would guess that. The distance to the best cloud model is 16 points in English, 23 in French and 26 to 28 in German and Spanish: the further from English, the more a local setup gives up.
What to take from it
Reading an English leaderboard to choose a model for German is a mistake for about a third of the field. The frontier closed models are safe in every language we test. Below them, check the edition in your language, and if you run models locally, check the specific quantization: the file that wins in one language can lose in the next.
Conclusion
The frontier models are frontier in every language, and the open-weight field is not. If you write in French, German or Spanish, an English-only leaderboard will mislead you about a third of the models; read the edition for your language, and if you run models locally, check the specific quantization there too.