Q4, Q6 or Q8: quantization costs nothing on some models and twenty points on others
Same model, three files, three scores. Qwen3.8 27B writes English as well at Q4_K_M as at Q8_0 with a file half the size, Gemma 4 31B does not care which of its three builds you run, and Granite 4.2 30B loses twenty points between Q8 and Q4. There is no rule of thumb, only measurements.
Quantization shrinks a model by storing its weights with fewer bits. A 27-billion-parameter model is 29 GB at Q8_0 and 17 GB at Q4_K_M, which is the difference between fitting a 32 GB card or not. Every guide says the smaller file writes a little worse. We measured how much, on English writing, with the same blind duels that build the main ranking, about 1,000 to 1,800 per build. Scores are the English leaderboard scale: 50 means an even chance of beating the average model.
Same model, three files, three scores: the lines are not parallel
Score by quantization level, family by family
Score of each build with reasoning enabled. Lines connect the builds of one family; 4-bit files on the left, 8-bit on the right.
- Muse Glimmer
- Qwen
- Gemma
- Granite
- Nemotron
View as a data table
| Family | Q4 (K_M, QAT, K-Quant 17GB) | Q5 / Q6 | Q8 |
|---|---|---|---|
| Muse Glimmer 30B | 63.8 | 77.4 | — |
| Qwen3.6 27B | 55.9 | — | 62.5 |
| Qwen3.8 27B | 64.1 | 59.0 | 61.3 |
| Gemma 4 31B | 54.3 | 55.7 | 54.9 |
| Qwen3.6 35B A3B | 45.2 | — | 54.4 |
| Gemma 4 26B A4B | 44.1 | 57.4 | 46.0 |
| Gemma 4 12B | 46.4 | 48.6 | 44.2 |
| Granite 4.2 30B | 14.1 | 26.8 | 34.1 |
| Nemotron 3 Nano Omni 30B A3B | 14.5 | — | 23.1 |
| Gemma 4 E2B | 12.9 | 13.9 | 21.3 |
| Gemma 4 E4B | 11.8 | 18.6 | 14.6 |
If quantization were a fixed tax, every line would slope up from left to right by the same amount. They do not. Some are flat, one goes down, and two collapse. That is the whole finding; the rest of this article walks the lines.
Where quantization is free: Qwen3.8 27B and Gemma 4 31B lose nothing at 4 bits
Gemma 4 31B is the model that does not care. QAT-Q4_0, Q6_K and Q8_0 land within 1.4 points of each other, and the 17 GB file runs twice as fast as the 33 GB one. Google trained the QAT build specifically to survive 4-bit storage, and here it shows.
Qwen3.8 27B goes further: its Q4_K_M build is the best of the three in English, 64.1 against 61.3 for Q8_0, on more than 1,100 duels each. The 17 GB file is the one to download. Gemma 4 12B tells the same story at a smaller scale: its three builds sit within 4.4 points.
Where it is expensive: Granite 4.2 30B loses twenty points, Qwen3.6 35B ten
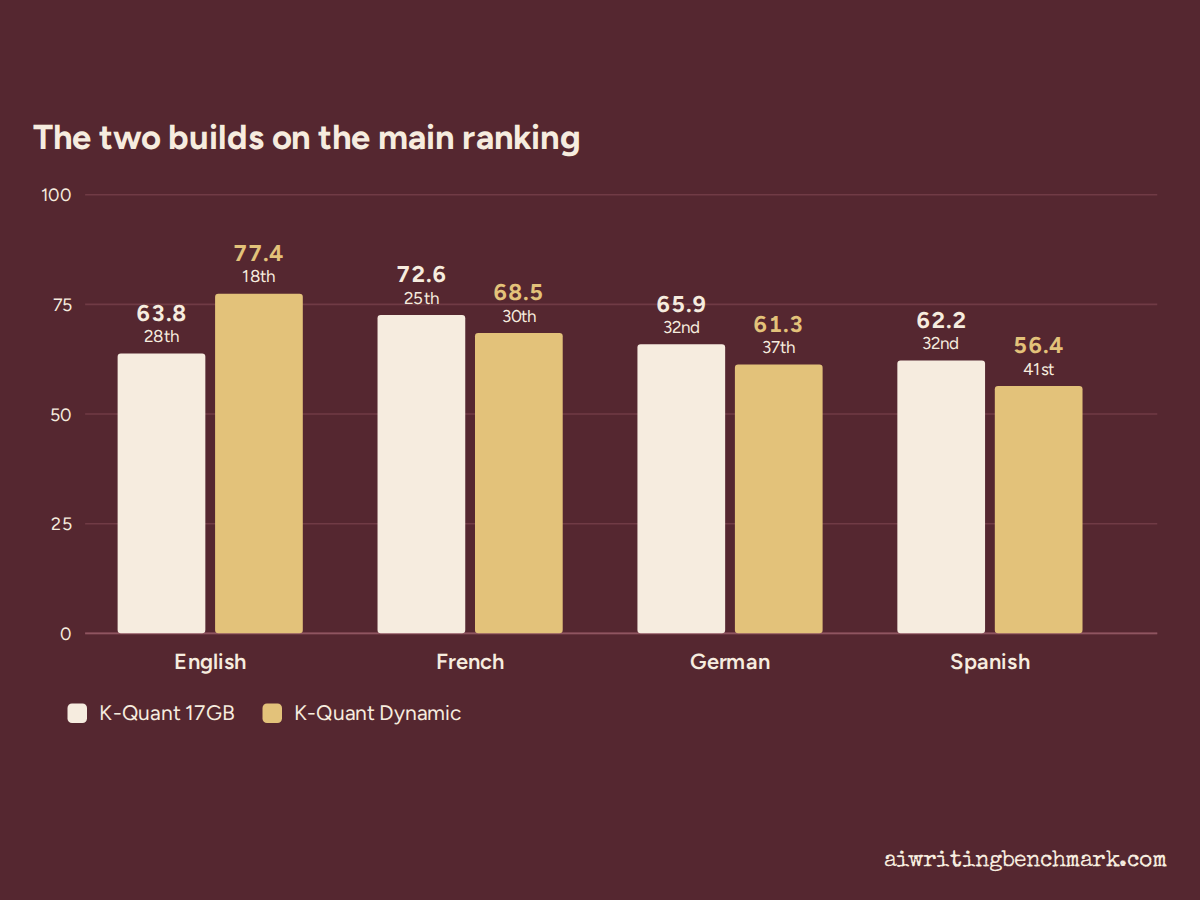
Granite 4.2 30B falls from 34.1 at Q8_0 to 26.8 at Q6_K and 14.1 at Q4_K_M. Its Q4 build is one of the weakest models in the ranking; its Q8 build is a mid-table one. Qwen3.6 35B A3B, a mixture-of-experts model, loses 9 points between Q8 and Q4, and Nemotron 3 Nano loses 8.6 on a low base. Muse Glimmer 30B is a special case: the larger K-Quant Dynamic build, about Q5, beats the 17GB build by 13.6 points and is the best local model in English.
Q6 wins for Gemma 4 and loses for Qwen3.8
Seven of the eleven families in the chart have a Q6_K build. In four of them, all Gemma 4 (26B A4B, 12B, E4B and 31B, the last by less than a point), Q6_K is the best build of its family. In Qwen3.8 27B it is the worst of the three, and in Granite 4.2 30B and Gemma 4 E2B it sits between Q4 and Q8. So there is no blind rule: for Gemma 4, Q6_K is a sound choice when it fits; for Qwen3.8 27B, take Q4_K_M; for Granite, Q8_0.
What fits in 16 and 24 GB, and what it costs in points
File size against score
Every build of the table: GGUF file size and score. The dashed lines mark 16 GB and 24 GB of memory.
- Muse Glimmer
- Qwen
- Gemma
- Granite
- Nemotron
View as a data table
| Model | File size (GB) | Score |
|---|---|---|
| Muse Glimmer 30B K-Quant Dynamic | 19.7 | 77.4 |
| Qwen3.8 27B Q4_K_M | 16.8 | 64.1 |
| Muse Glimmer 30B K-Quant 17GB | 16.8 | 63.8 |
| Qwen3.6 27B Q8_0 | 28.6 | 62.5 |
| Qwen3.8 27B Q8_0 | 29.0 | 61.3 |
| Qwen3.8 27B Q6_K | 22.4 | 59.0 |
| Gemma 4 26B A4B Q6_K | 22.6 | 57.4 |
| Qwen3.6 27B Q4_K_M | 16.5 | 55.9 |
| Gemma 4 31B Q6_K | 25.2 | 55.7 |
| Gemma 4 31B Q8_0 | 32.6 | 54.9 |
| Qwen3.6 35B A3B Q8_0 | 36.9 | 54.4 |
| Gemma 4 31B QAT-Q4_0 | 17.7 | 54.3 |
| Gemma 4 12B Q6_K | 9.8 | 48.6 |
| Gemma 4 12B QAT-Q4_0 | 7.0 | 46.4 |
| Gemma 4 26B A4B Q8_0 | 26.9 | 46.0 |
| Qwen3.6 35B A3B Q4_K_M | 21.2 | 45.2 |
| Gemma 4 12B Q8_0 | 12.7 | 44.2 |
| Gemma 4 26B A4B QAT-Q4_0 | 14.4 | 44.1 |
| Granite 4.2 30B Q8_0 | 31.1 | 34.1 |
| Granite 4.2 30B Q6_K | 24.0 | 26.8 |
| Nemotron 3 Nano Omni 30B A3B Q8_0 | 33.6 | 23.1 |
| Gemma 4 E2B Q8_0 | 5.0 | 21.3 |
| Gemma 4 E4B Q6_K | 6.2 | 18.6 |
| Gemma 4 E4B Q8_0 | 8.0 | 14.6 |
| Nemotron 3 Nano Omni 30B A3B Q4_K_M | 24.5 | 14.5 |
| Granite 4.2 30B Q4_K_M | 17.7 | 14.1 |
| Gemma 4 E2B Q6_K | 3.8 | 13.9 |
| Gemma 4 E2B Q4_K_M | 3.4 | 12.9 |
| Gemma 4 E4B Q4_K_M | 5.3 | 11.8 |
The dashed lines mark the two common memory ceilings. Below 16 GB, the best writer is Gemma 4 12B Q6_K at 48.6, a 9.8 GB file; Qwen3.8 27B Q4_K_M (64.1) and Muse Glimmer 17GB (63.8) miss that line with 16.8 GB files. Below 24 GB the best is Muse Glimmer Dynamic at 77.4, a 19.7 GB file, ahead of every larger file in the chart. The Q8 builds of the large families on the right cost 27 to 37 GB and buy anywhere from nothing to twenty points, depending on the family. Memory beyond 24 GB is better spent on a bigger model than on a bigger quantization of the same one.
The same measurement in French, German and Spanish gives different answers
None of this transfers. In German, Qwen3.8 27B loses 21 points between Q8 and Q4; in Spanish, 27. In French, Gemma 4 12B Q6_K collapses to 27.5 while its QAT build scores 52.2. Each edition of this article is written from its own language’s duels; if you write in one of them, read that one.
Conclusion
Quantization is not a fixed tax. On English writing, Qwen3.8 27B and Gemma 4 31B lose nothing at 4 bits; Granite 4.2 30B and Qwen3.6 35B lose ten to twenty points. Q6 is the best build in four Gemma families and the worst in Qwen3.8 27B. Check the specific file in this table before trusting a general percentage or a rule of thumb.