The models that write best in English

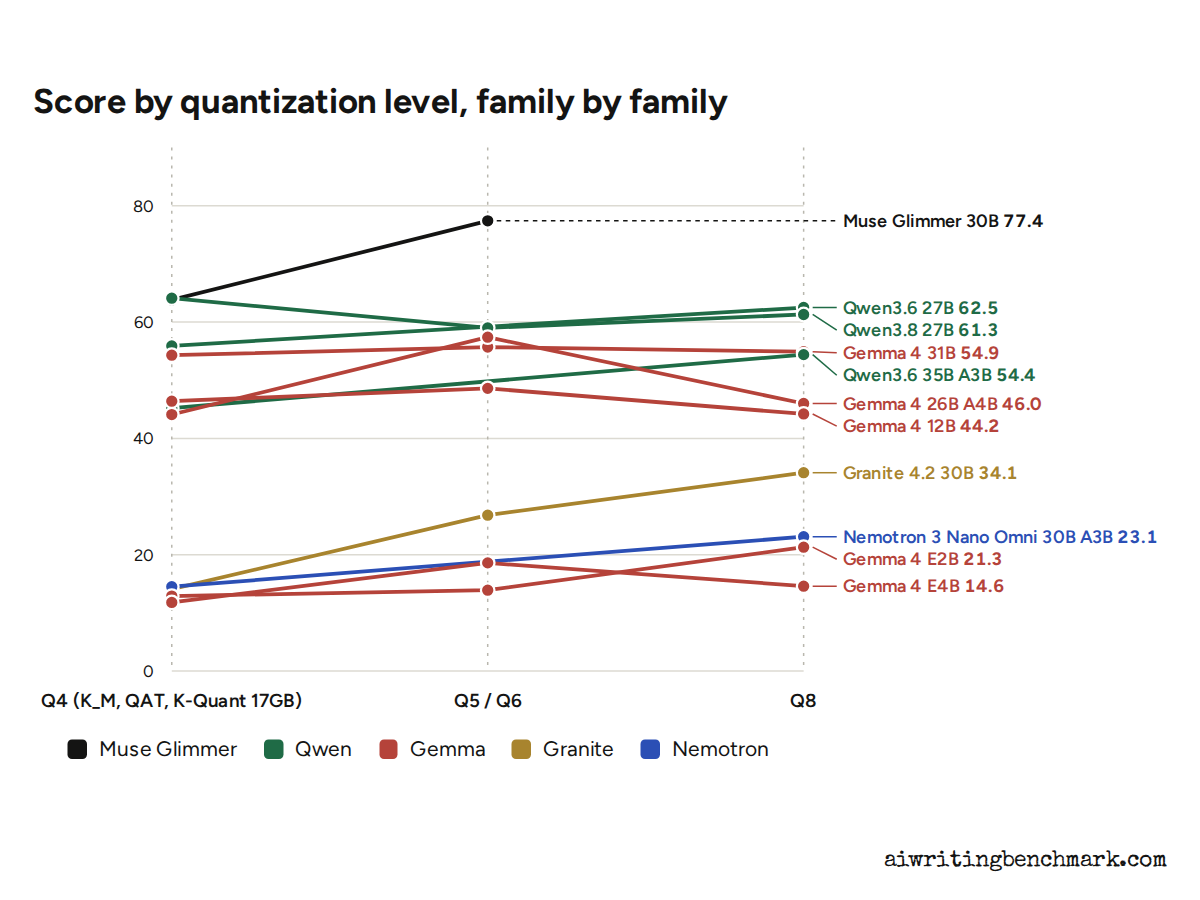
GPT-6.1 Sol by OpenAI (thinking high) writes the best English today, with a score of 95.7. Among the models you can run on your own machine, Muse Glimmer 30B by Meta (K-Quant Dynamic, thinking high) leads with 72.4.

The AI Writing Benchmark measures how well leading AI models write in English. Responses to a shared corpus of English writing prompts are compared blind, without model names, and the verdicts are combined into a ranking for English.

107 models compared on 115,682 blind verdicts, updated 16 October 2026.

The 10 best models

The ten best models for writing in English
#ModelScore
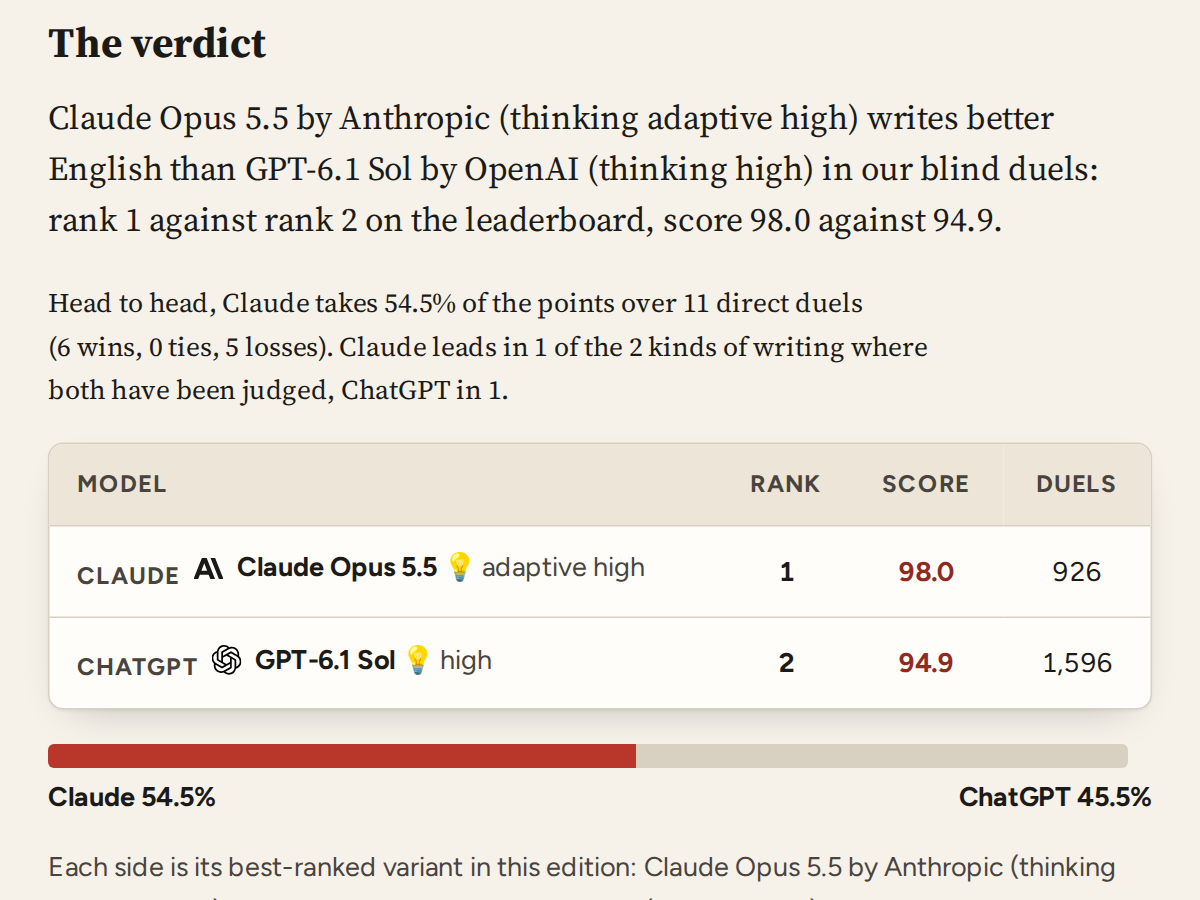
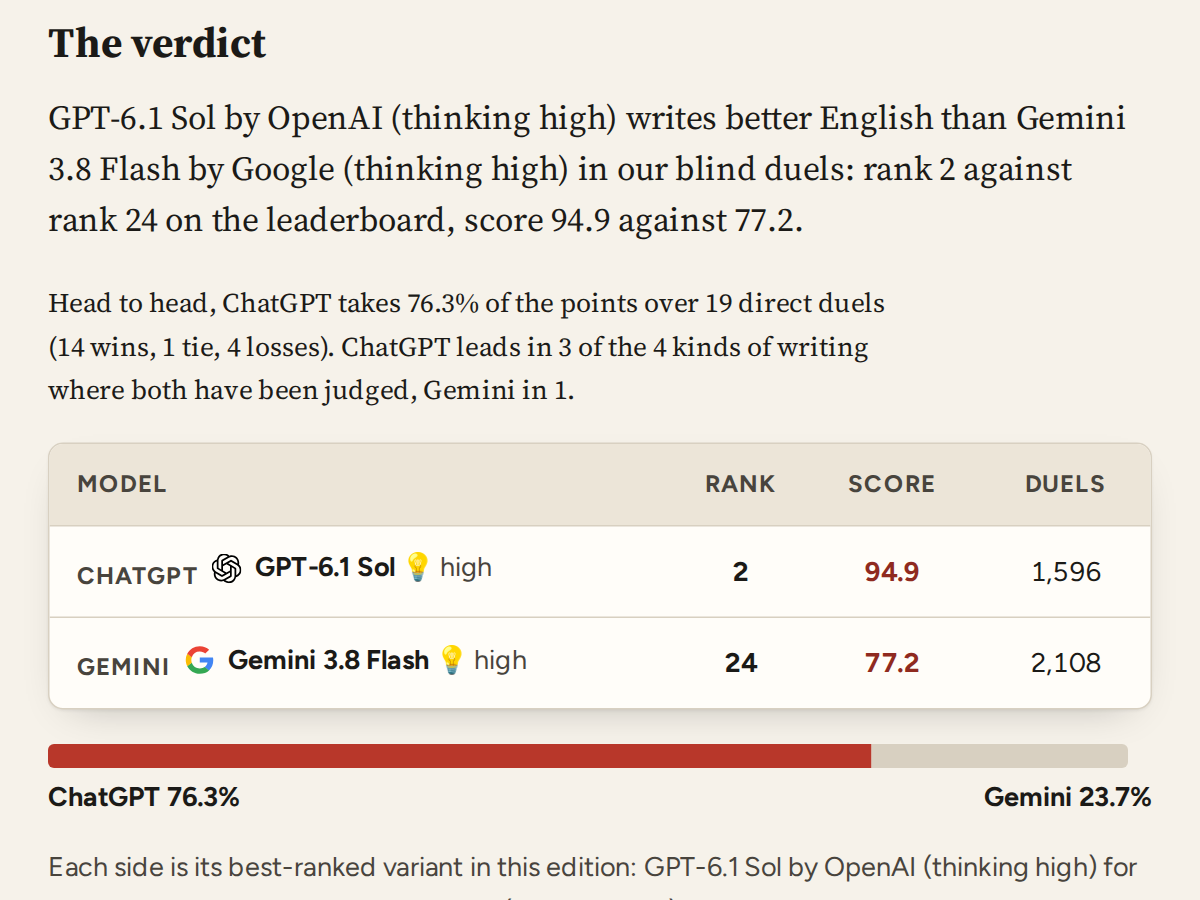
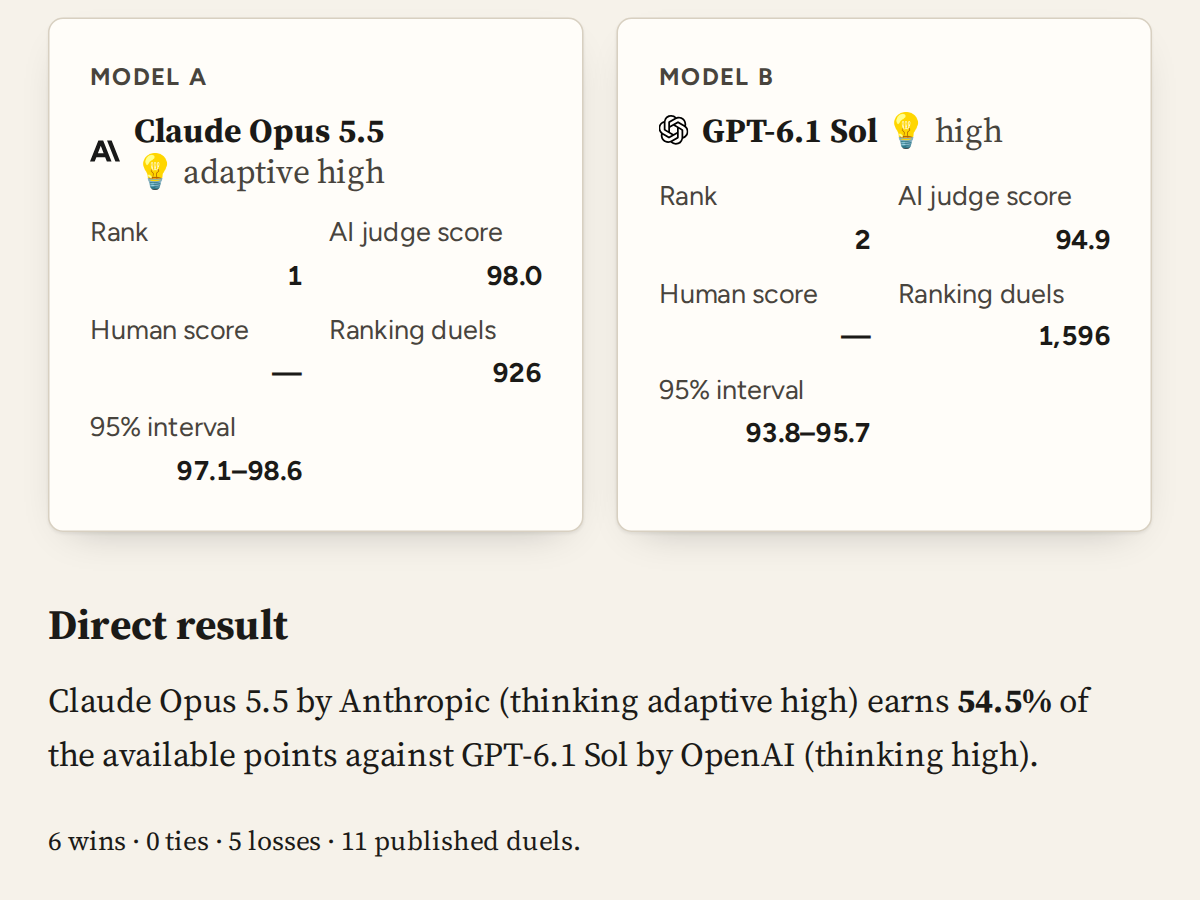
1GPT-6.1 Sol 💡 high95.7
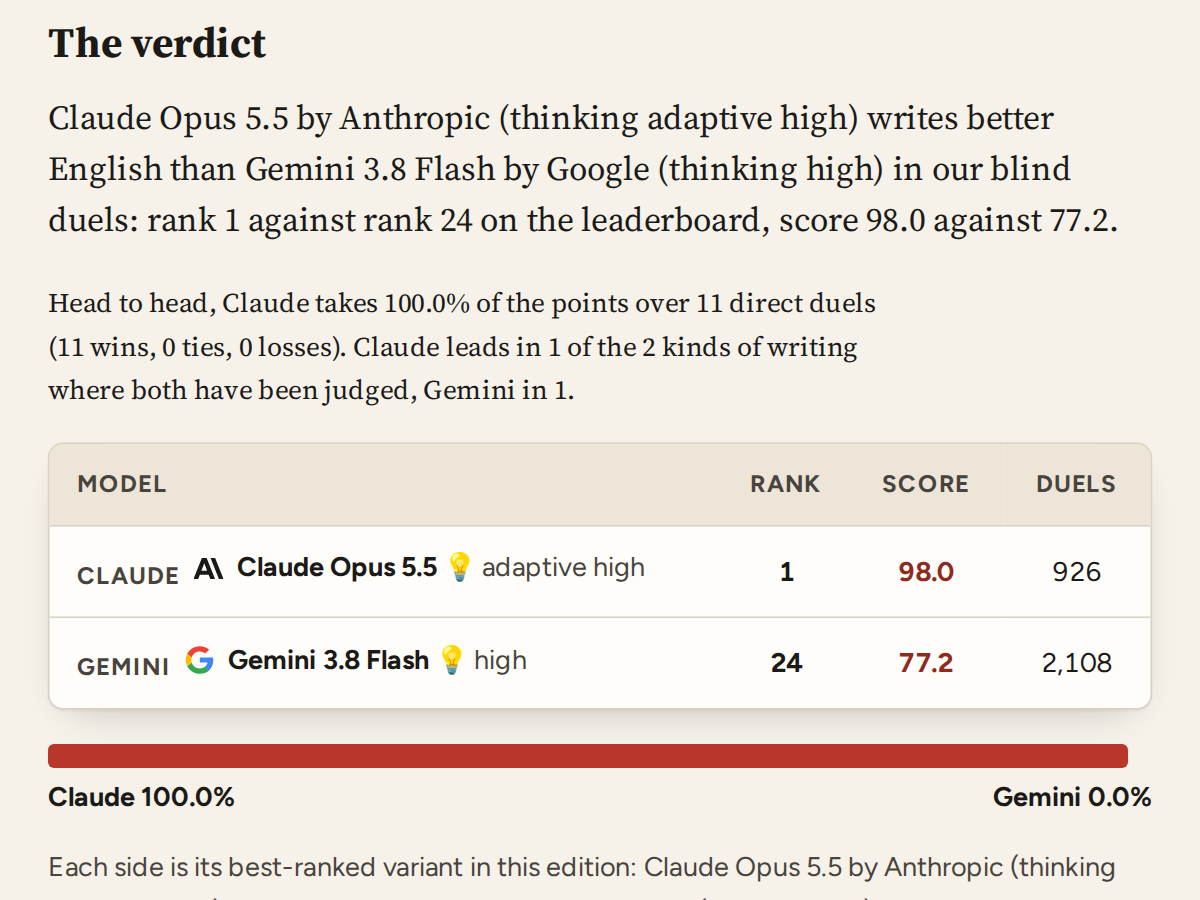
2Claude Opus 5.5 💡 adaptive high94.8
3Kimi K3 💡 enabled92.2
4GPT-6 Astra 💡 high91.9
5Claude Fable 5 💡 adaptive high89.6
6Claude Fable 5.1 💡 adaptive high89.4
7Claude Sonnet 5.5 💡 adaptive high89.1
7GPT-6 Sol 💡 high89.1
9GLM 5.3 💡 max88.7
10Claude Opus 5 💡 adaptive high88.1

This score is not a percentage grade: 50 means an estimated one-in-two chance of beating the average model in English.

Last updated: See the full leaderboard

The best model for each kind of writing

Ranks recomputed on the duels of one category alone. A model that tops the general ranking does not always top the emails or the fiction. Which model for a novel, an email, a cover letter or an essay: the guide.

The best model for each kind of writing
Kind of writingModelScore
Articles, blogs and editorialGPT-6.1 Sol 💡 high97.4
Dialogue and screenplayGPT-6.1 Sol 💡 high98.3
Explanation and popularizationKimi K3 💡 enabled95.1
Fiction and narrativeGrok 4.7 💡 high98.1
Marketing and salesClaude Sonnet 5.5 💡 adaptive high97.3
Personal communicationClaude Opus 5.5 💡 adaptive high98.6
Professional and administrativeClaude Sonnet 5.5 💡 adaptive high93.3
Social media and short formatsGPT-6.1 Sol 💡 high96.8
Speech and public speakingGPT-6.1 Sol 💡 high98.2
Structured documents and reportsGPT-6.1 Sol 💡 high97.3

The 10 best local variants

The ten best exact variants run locally
#ModelScoreFile+128K+256K
1Muse Glimmer 30B K-Quant Dynamic 💡 high 🏠72.421.1 GB22.9 GB22.9 GB
2Muse Glimmer 30B K-Quant 17GB 💡 high 🏠61.418.2 GB20.0 GB20.0 GB
3Qwen3.8 27B Q4_K_M 💡 xhigh** 🏠58.717.7 GB26.5 GB35.1 GB
4Qwen3.6 27B Q8_0 💡 on* 🏠58.528.6 GB37.3 GB45.9 GB
5Qwen3.8 27B Q8_0 💡 xhigh** 🏠57.430.0 GB38.7 GB47.3 GB
6Qwen3.8 27B Q6_K 💡 xhigh** 🏠56.423.4 GB32.1 GB40.7 GB
7Gemma 4 31B Q6_K 💡 on* 🏠53.926.4 GB38.4 GB49.1 GB
8Gemma 4 31B Q8_0 💡 on* 🏠53.533.8 GB45.8 GB56.6 GB
9Qwen3.6 27B Q4_K_M 💡 on* 🏠51.616.5 GB25.3 GB33.9 GB
10Gemma 4 31B QAT-Q4_0 💡 on* 🏠51.517.7 GB29.6 GB40.4 GB

Size of the GGUF file we tested (GB, decimal, as LM Studio shows it) · +128K: File + context cache at 131,072 tokens (128K), F16 cache, Flash Attention on (GB) · +256K: The same at 262,144 tokens (256K), capped at the native context window (GB)

The best local writer for your memory

Best-writing variant that fits the memory of the graphics card or unified memory, short context. Details, speeds and alternatives on the Local AI page.

The best local writer for your memory
MemoryModelScore
8 GBGranite 4.2 8B Q4_K_M 💡 full 🏠17.9
12 GBGemma 4 12B QAT-Q4_0 💡 on* 🏠41.7
16 GBGemma 4 12B Q6_K 💡 on* 🏠42.2
24 GBMuse Glimmer 30B K-Quant 17GB 💡 high 🏠61.4
32–128 GBMuse Glimmer 30B K-Quant Dynamic 💡 high 🏠72.4

See the local AI ranking

All analyses →

All head-to-heads and the free comparison →

The ranking evaluates writing quality alone. Prompts are written directly in the language being tested, and model names remain hidden until the verdict so reputation cannot influence the evaluation. This site is a personal project. No model provider pays me, and I have no reason to favour one model over another.