The full leaderboard
Every model ranked on English writing, with filters by kind of writing, publisher, size, reasoning mode and quantization, and the duel matrices.
New models as they enter the ranking, where they land against their predecessor, the new analyses and the milestones of the benchmark.
111,333 ranked verdicts
108 ranked models
13,667 to go before 125,000
Cumulative totals of the English edition, day by day.
Ranks and scores are today’s: they are recomputed with every new verdict, not frozen when a model arrives.

MiniMax M3.1 Flash. Now No. 56 of 108, with a score of 47.4.

Ling 3.1 Flash. Now No. 27 of 108, with a score of 73.4.

Mistral Large 4. Now No. 35 of 108, with a score of 66.5.
Nemotron 3 Ultra. Now No. 69 of 108, with a score of 38.5.
Nemotron 3.5 Lightning. Now No. 76 of 108, with a score of 30.8.

Claude Haiku 5.5. Now No. 26 of 108, with a score of 74.1.
100,000
Reached 78 days after the first duel, 8 days after the 75,000 mark.
Until now, most duels compared personal messages. New duels are spread across the ten categories (letters, articles, fiction, speeches, reports…), starting with the least covered, so the ranking gradually reflects every kind of text.
Muse Spark 1.3, which kept sliding down the ranking, no longer judges; its past verdicts stay published. Claude Opus 5.5 takes over its share, so the duels arrive at the same pace.
In the Duel and on the head-to-head pages, responses now show their bold text, headings and lists instead of raw asterisks and hashes, so you judge the text the way a reader would see it.
About one verdict in twenty came from a judge facing its own model, and it tended to favour itself: up to five points for some models. Those verdicts stay published on the judges’ page but no longer enter the ranking, and judges are no longer given their own model.

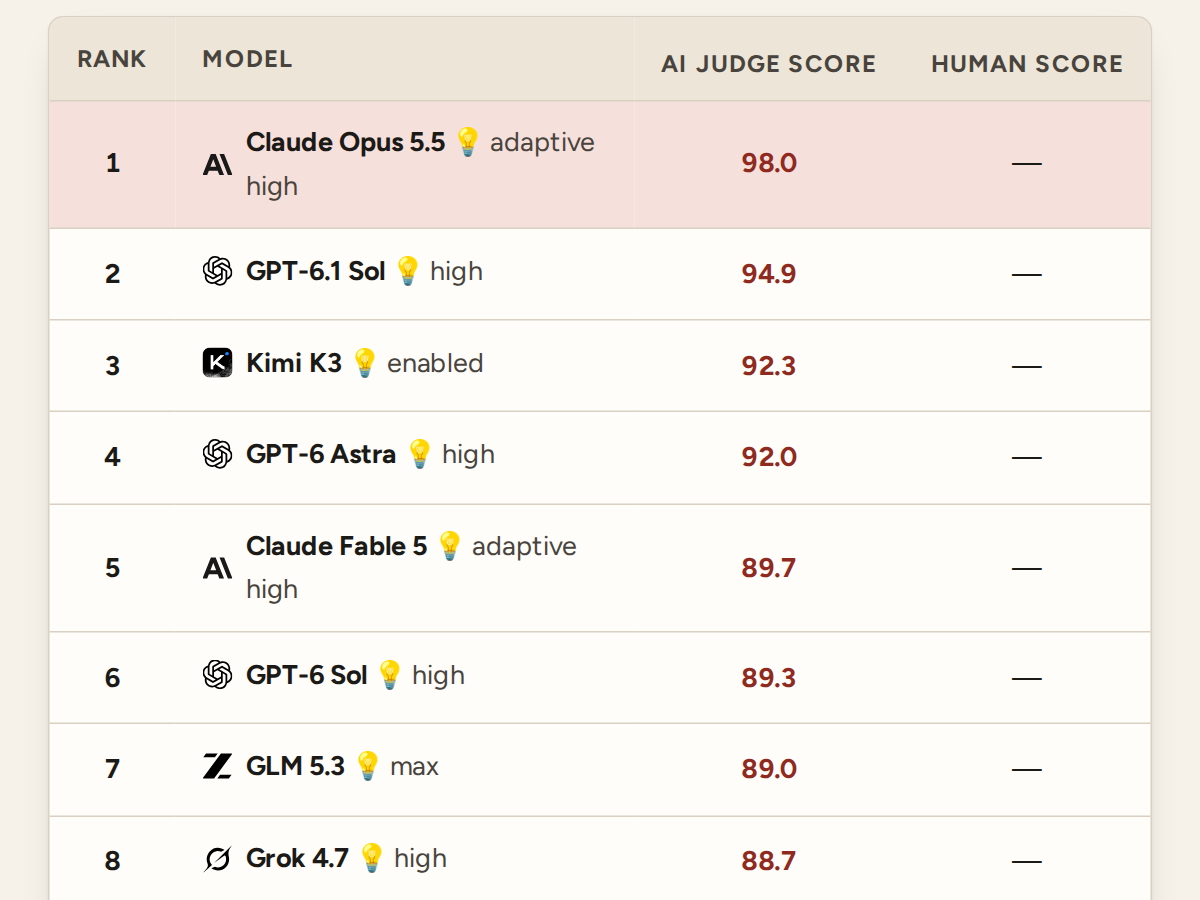
GPT-6.1 Sol. Now No. 1 of 108, with a score of 95.7. That is 6.6 points above its predecessor, GPT-6 Sol (No. 7, 89.1). Direct duels won against it: 14 of 18 (78%).
100
With Claude Sonnet 5.5, 73 days after the first duel.

Aion 3.5. Now No. 14 of 108, with a score of 84.0. That is 14.4 points above its predecessor, Aion 3.0 (No. 32, 69.6).
Claude Sonnet 5.5. Now No. 7 of 108, with a score of 89.1. That is 4.1 points above its predecessor, Claude Sonnet 5 (No. 13, 85.0).
The Local AI ranking shows the memory each model needs as a file and with a 128K or 256K context, in GGUF or MLX and with an F16 or Q8 cache. Buttons above every ranking switch between the latest models, the previous generation and older ones.
75,000
Reached 70 days after the first duel, 12 days after the 50,000 mark.
Claude Opus 5.5. Now No. 2 of 108, with a score of 94.8. That is 6.7 points above its predecessor, Claude Opus 5 (No. 10, 88.1).
GPT-6 Luna. Now No. 19 of 108, with a score of 79.4. That is 19.4 points above its predecessor, GPT-5.6 Luna (No. 38, 60.0).
GPT-6 Sol. Now No. 7 of 108, with a score of 89.1. That is 8.6 points above its predecessor, GPT-5.6 Sol (No. 16, 80.5).
The newest Anthropic and OpenAI models take over as judges, alongside Muse Spark 1.3. Each verdict still compares two anonymous texts written for the same prompt.

Agnes 3.0 Flash. Now No. 77 of 108, with a score of 29.9.

Grok 4.7. Now No. 12 of 108, with a score of 87.6. That is 18.6 points above its predecessor, Grok 4.6 (No. 34, 69.0). Direct duels won against it: 4 of 10 (40%).

MiMo V2.6 Flash. Now No. 54 of 108, with a score of 50.1.
MiMo V2.6 Pro. Now No. 17 of 108, with a score of 79.7. That is 34.4 points above its predecessor, MiMo V2.5 Pro (No. 58, 45.3). Direct duels won against it: 27 of 34 (79%).
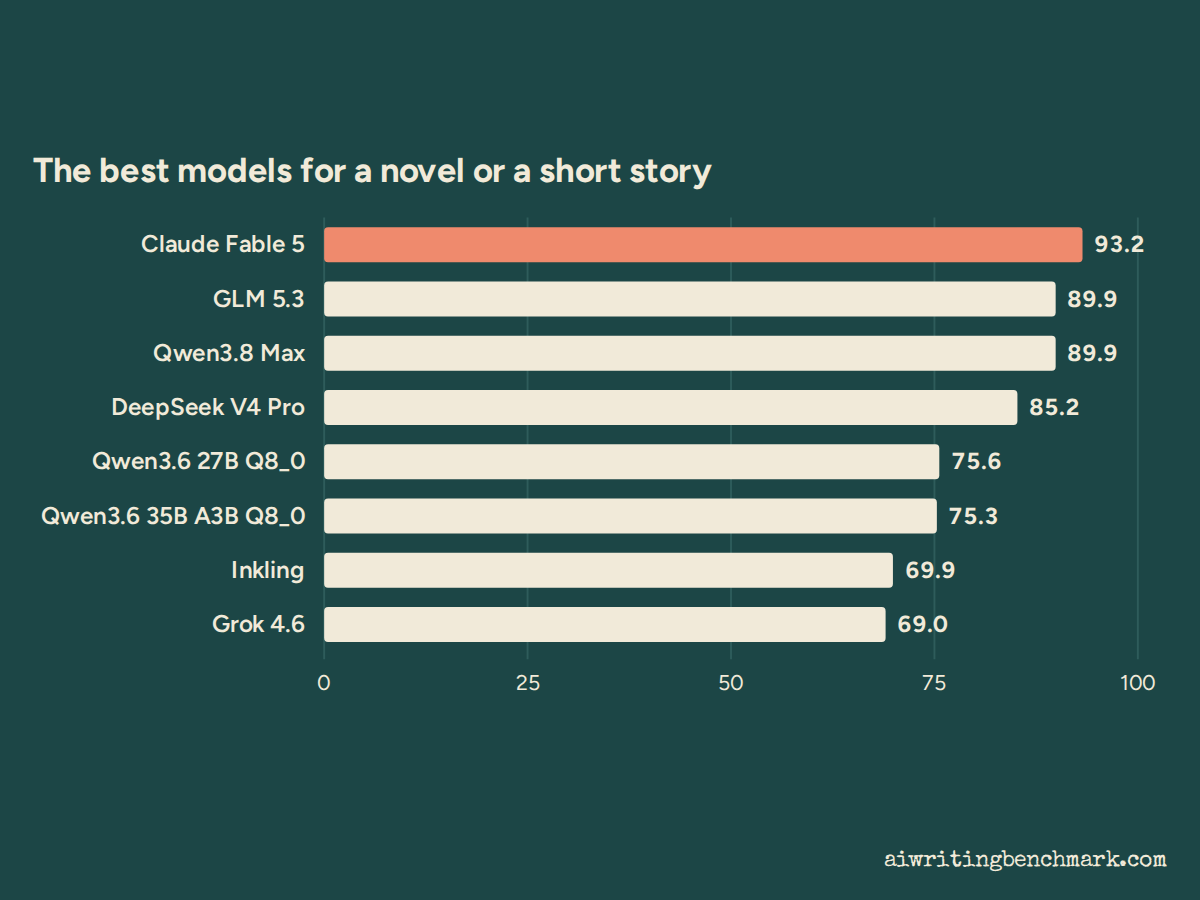 Which AI for a novel, an email, a cover letter or an essay? The best model changes with the task
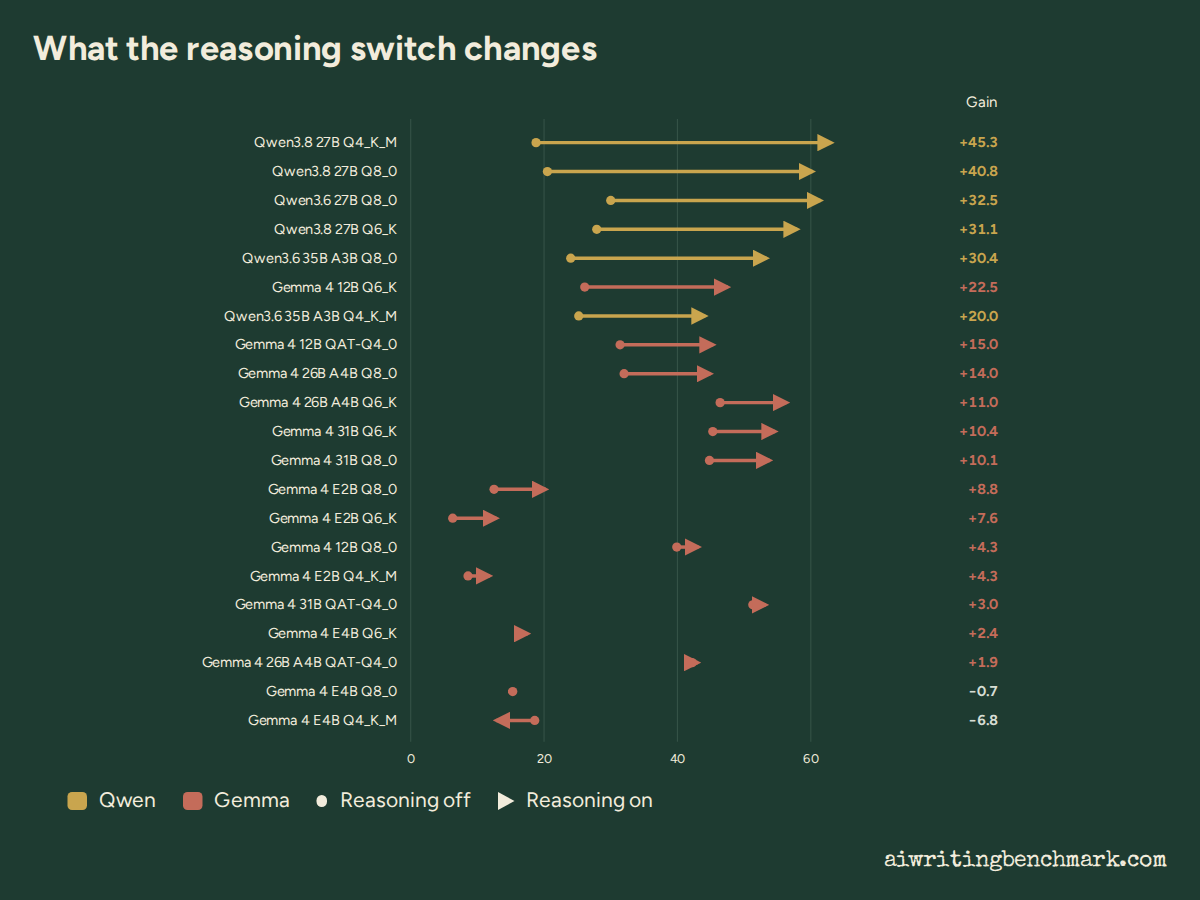
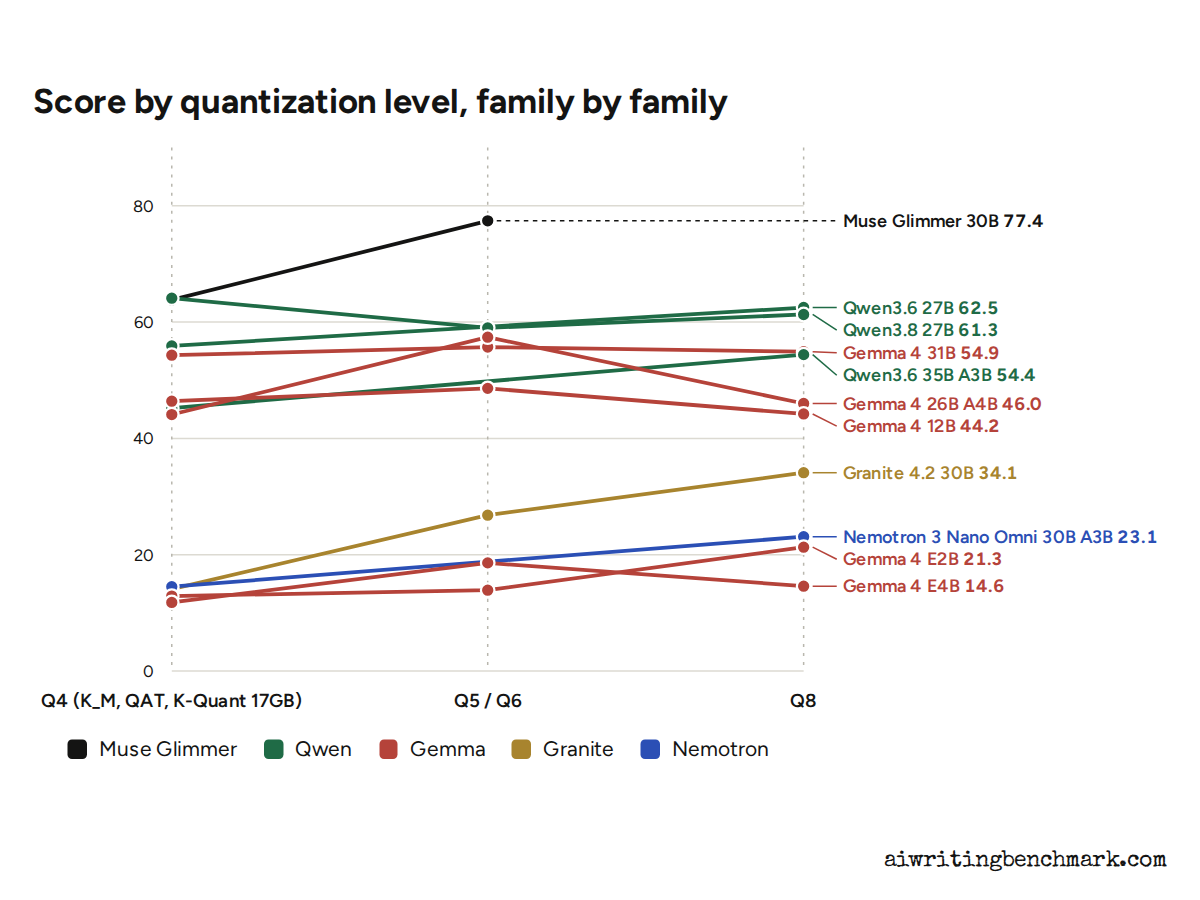 Q4, Q6 or Q8: quantization costs nothing on some models and twenty points on others
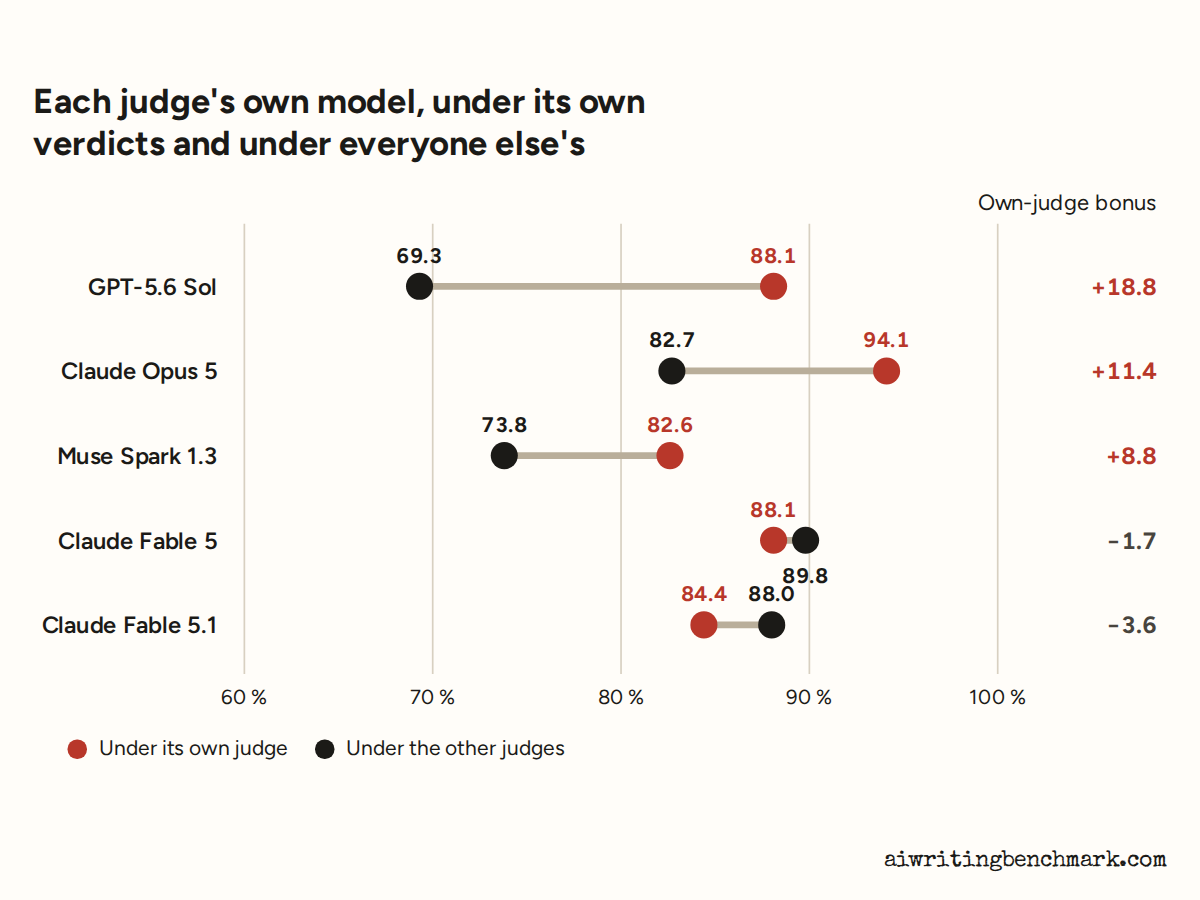 Do AI judges favour their own model? Two of five do, by up to 19 points
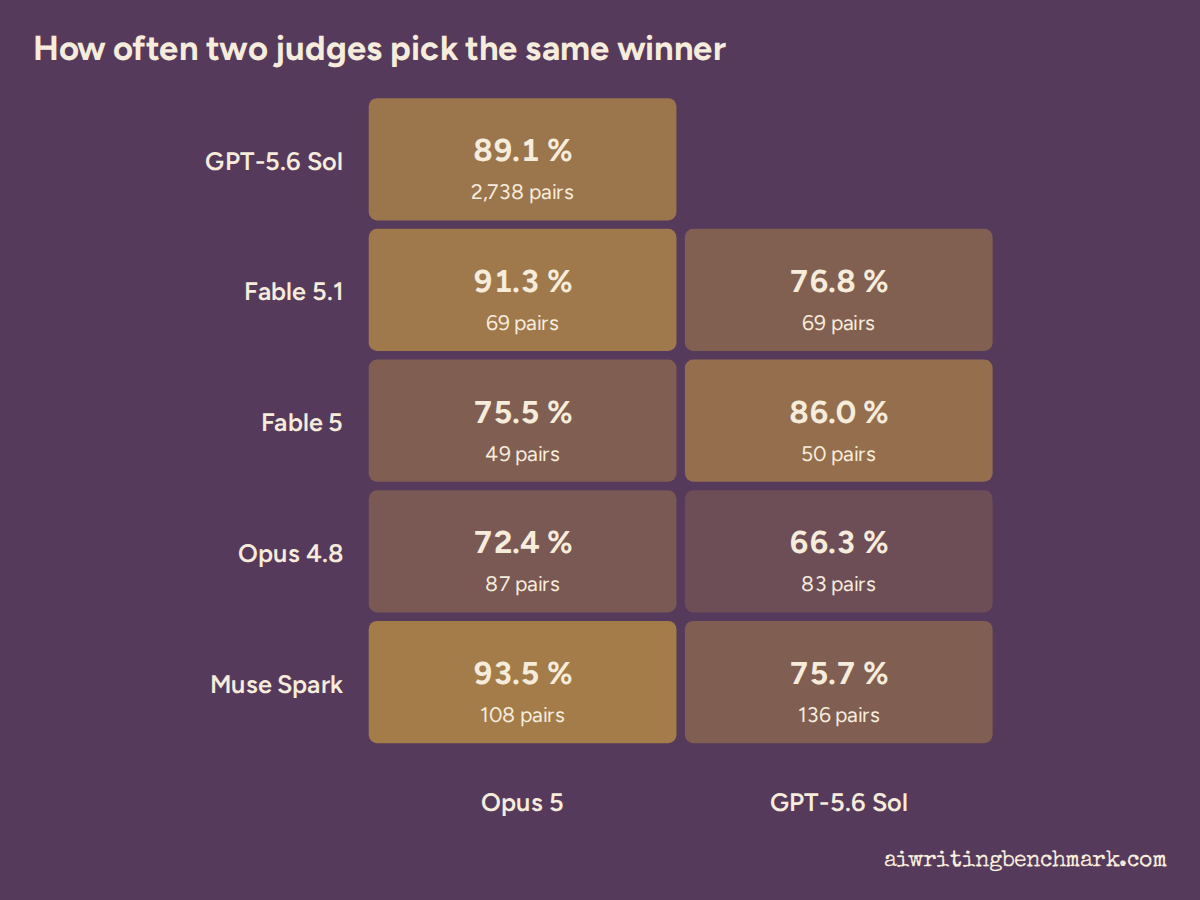 The two main AI judges pick the same winner nine times out of ten. The disagreements are elsewhere
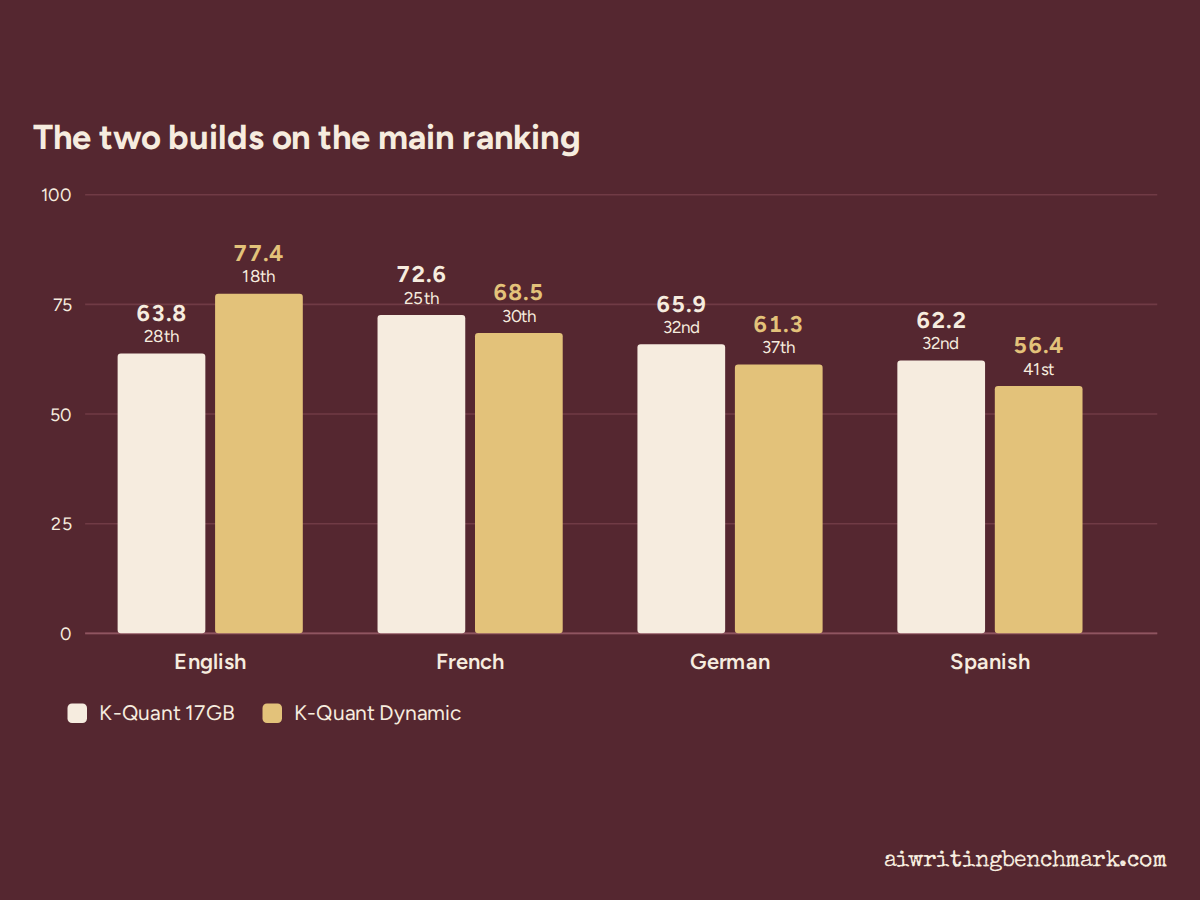
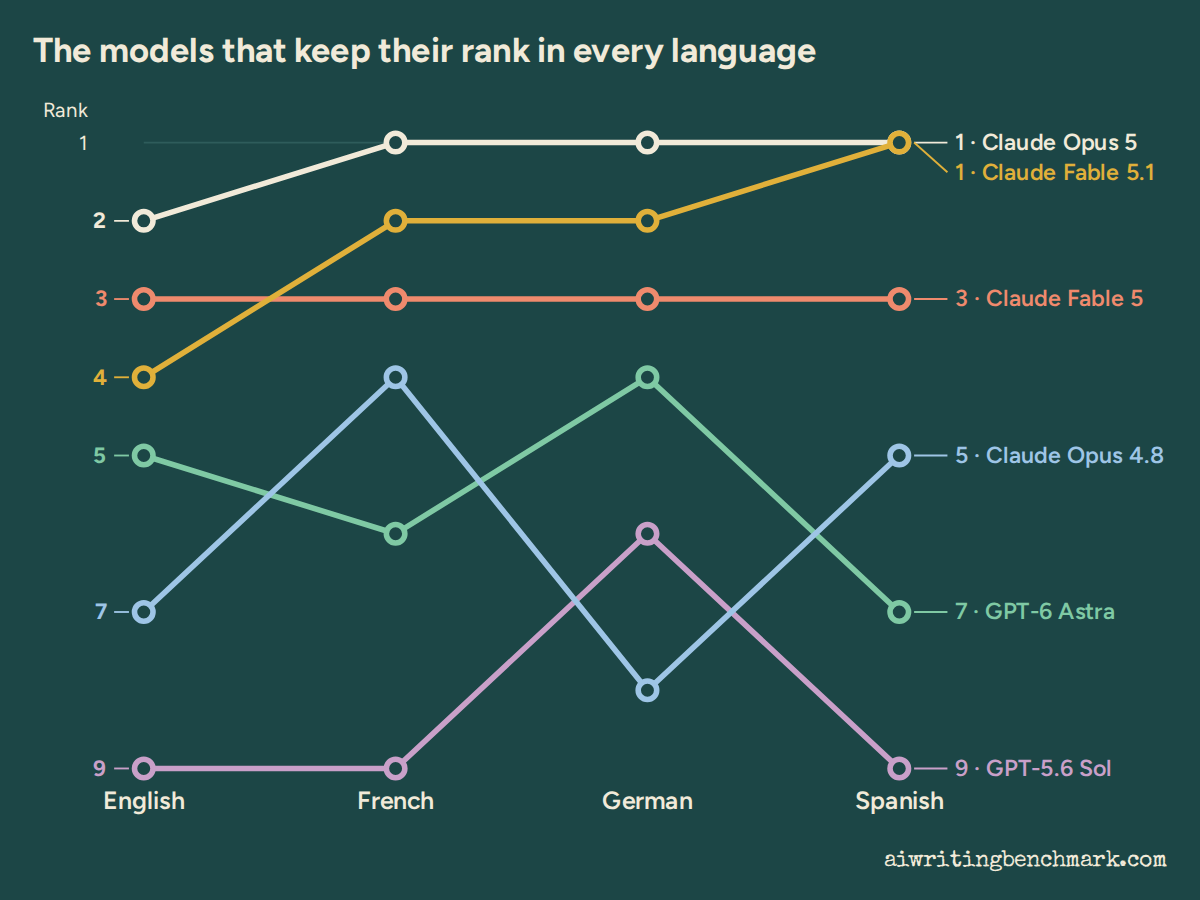 Same model, four languages: the top barely moves, the middle swings by forty places
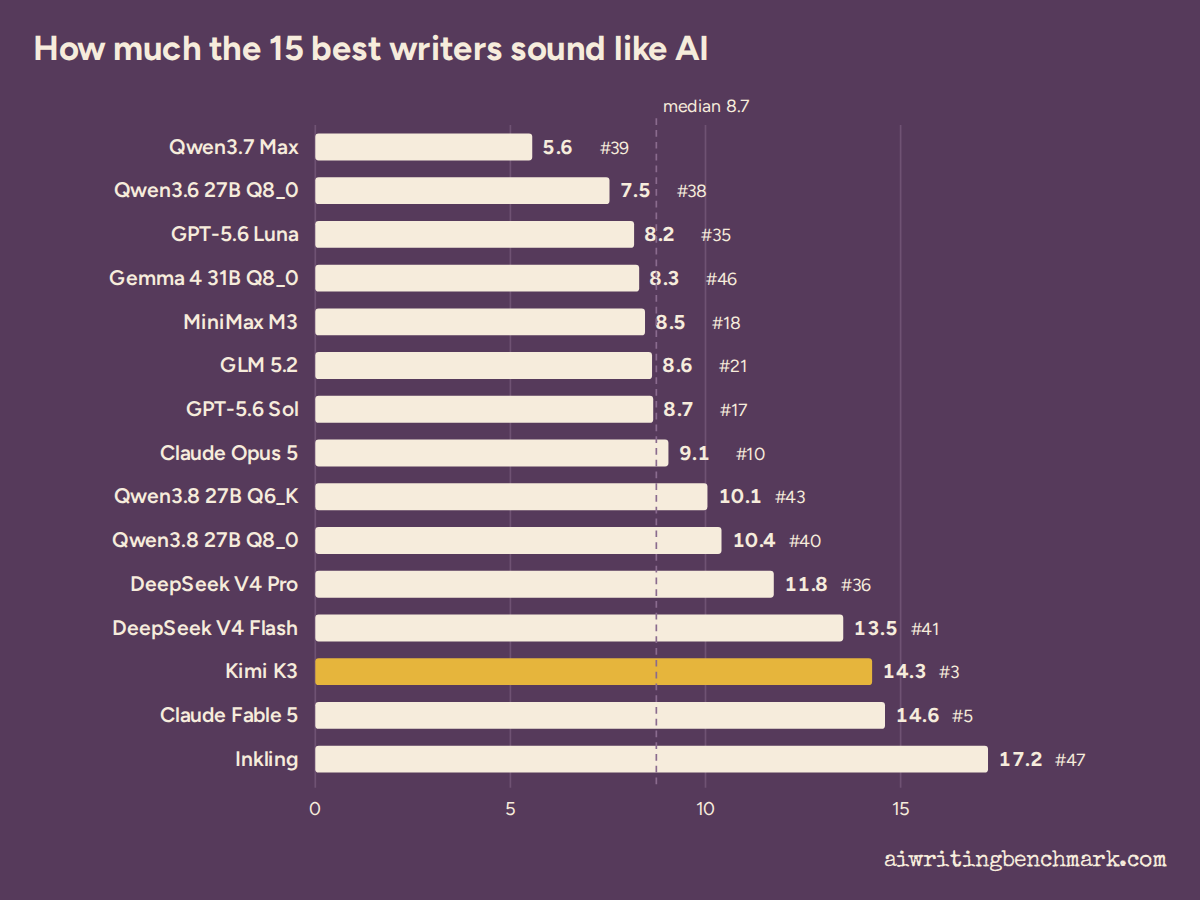 Which AI sounds least like AI? The best writers are the heaviest em-dash users
Claude vs ChatGPT, Claude vs Gemini, Gemma vs Qwen: the most-searched match-ups now have their own page, with the verdict of the blind duels. Every ranked model also gets an index of the marks of machine prose: stock phrases, em dashes, lists of three.
Ling 3.0 Flash. Now No. 72 of 108, with a score of 36.2. Best of its 2 ranked variants: Ling 3.0 Flash by InclusionAI (Q4_K_M, no thinking).
50,000
Reached 58 days after the first duel, 20 days after the 25,000 mark.

DeepSeek V4.1 Flash. Now No. 21 of 108, with a score of 78.0. That is 22.8 points above its predecessor, DeepSeek V4 Flash (No. 45, 55.2).
GPT-6 Astra. Now No. 4 of 108, with a score of 91.9.
Claude Fable 5.1. Now No. 6 of 108, with a score of 89.4. Level with its predecessor, Claude Fable 5 (No. 5, 89.7).

Gemini 3.8 Flash. Now No. 25 of 108, with a score of 76.9. That is 7.2 points above its predecessor, Gemini 3.6 Flash (No. 31, 69.7).

Muse Spark 1.3. Now No. 19 of 108, with a score of 79.4. That is 1.7 points above its predecessor, Muse Spark 1.2 (No. 22, 77.7).
Inkling. Now No. 49 of 108, with a score of 52.2.

Granite 4.2 8B. Now No. 92 of 108, with a score of 18.5. Best of its 2 ranked variants: Granite 4.2 8B by IBM (Q8_0, thinking full).

GLM 5.3 Flash. Now No. 15 of 108, with a score of 81.4.
Granite 4.2 30B. Now No. 84 of 108, with a score of 25.7. Best of its 3 ranked variants: Granite 4.2 30B by IBM (Q8_0, thinking full).

Hy4 Preview. Now No. 30 of 108, with a score of 70.3. That is 7.0 points below its predecessor, Hy3 (No. 24, 77.3). Direct duels won against it: 7 of 24 (29%).

Qwen3.8 Flash. Now No. 48 of 108, with a score of 52.9.
25,000
Reached 38 days after the first duel.
75
With Muse Spark 1.2, 34 days after the first duel.
Aion 3.0. Now No. 32 of 108, with a score of 69.6.
Gemini 3.7 Flash. Now No. 33 of 108, with a score of 69.5.
GLM 5.3. Now No. 9 of 108, with a score of 88.7. That is 11.1 points above its predecessor, GLM 5.2 (No. 23, 77.6). Direct duels won against it: 17 of 24 (71%).
Grok 4.6. Now No. 34 of 108, with a score of 69.0.
Hy3. Now No. 24 of 108, with a score of 77.3.
Mistral Medium 3.5. Now No. 86 of 108, with a score of 22.4.
Muse Spark 1.2. Now No. 22 of 108, with a score of 77.7.
Qwen3.8 Max. Now No. 28 of 108, with a score of 72.6. That is 14.9 points above its predecessor, Qwen3.7 Max (No. 42, 57.7).

Seed 2.1 Turbo. Now No. 74 of 108, with a score of 34.2.
Qwen3.8 27B. Now No. 40 of 108, with a score of 58.7. Best of its 6 ranked variants: Qwen3.8 27B by Alibaba (Q4_K_M, thinking xhigh). Level with its predecessor, Qwen3.6 27B (No. 41, 58.6).
50
With Gemma 4 12B, 28 days after the first duel.
Muse Glimmer 30B. Now No. 29 of 108, with a score of 72.4. Best of its 2 ranked variants: Muse Glimmer 30B by Meta (K-Quant Dynamic, thinking high).
Gemma 4 E2B. Now No. 95 of 108, with a score of 16.6. Best of its 6 ranked variants: Gemma 4 E2B by Google (Q8_0, thinking on).
Gemma 4 E4B. Now No. 96 of 108, with a score of 15.5. Best of its 6 ranked variants: Gemma 4 E4B by Google (Q6_K, no thinking).
Nemotron 3 Super 120B A12B. Now No. 80 of 108, with a score of 28.3.

Laguna S 2.1 UD. Now No. 68 of 108, with a score of 40.1.
Nemotron 3 Nano Omni 30B A3B. Now No. 93 of 108, with a score of 18.4. Best of its 2 ranked variants: Nemotron 3 Nano Omni 30B A3B by NVIDIA (Q8_0, thinking on).
Claude Sonnet 5. Now No. 13 of 108, with a score of 85.0.
Gemini 3.6 Flash. Now No. 31 of 108, with a score of 69.7.
Claude Opus 5. Now No. 10 of 108, with a score of 88.1. Level with its predecessor, Claude Opus 4.8 (No. 11, 87.7).
GPT-5.6 Luna. Now No. 38 of 108, with a score of 60.0.
Kimi K3. Now No. 3 of 108, with a score of 92.2.
Claude Fable 5. Now No. 5 of 108, with a score of 89.7.
25
With Claude Opus 4.8, 6 days after the first duel.
Claude Opus 4.8. Now No. 11 of 108, with a score of 87.7.
GPT-5.6 Terra. Now No. 36 of 108, with a score of 65.9.
GPT-5.6 Sol. Now No. 16 of 108, with a score of 80.5.
Gemma 4 12B. Now No. 61 of 108, with a score of 42.2. Best of its 6 ranked variants: Gemma 4 12B by Google (Q6_K, thinking on).
MiniMax M3. Now No. 18 of 108, with a score of 79.5.
Gemma 4 26B A4B. Now No. 52 of 108, with a score of 50.9. Best of its 6 ranked variants: Gemma 4 26B A4B by Google (Q6_K, thinking on).
Qwen3.6 35B A3B. Now No. 55 of 108, with a score of 47.5. Best of its 4 ranked variants: Qwen3.6 35B A3B by Alibaba (Q8_0, thinking on).
DeepSeek V4 Pro. Now No. 39 of 108, with a score of 59.3. Best of its 2 ranked variants: DeepSeek V4 Pro by DeepSeek (thinking on).
Gemma 4 31B. Now No. 46 of 108, with a score of 53.9. Best of its 6 ranked variants: Gemma 4 31B by Google (Q6_K, thinking on).
GLM 5.2. Now No. 23 of 108, with a score of 77.6.
MiMo V2.5 Pro. Now No. 58 of 108, with a score of 45.3. Best of its 2 ranked variants: MiMo V2.5 Pro by Xiaomi (thinking on).
Mistral Medium 3.5 128B. Now No. 85 of 108, with a score of 24.4.
Qwen3.6 27B. Now No. 41 of 108, with a score of 58.6. Best of its 3 ranked variants: Qwen3.6 27B by Alibaba (Q8_0, thinking on).
Qwen3.7 Max. Now No. 42 of 108, with a score of 57.7. Best of its 2 ranked variants: Qwen3.7 Max by Alibaba (thinking on).
Every model ranked on English writing, with filters by kind of writing, publisher, size, reasoning mode and quantization, and the duel matrices.
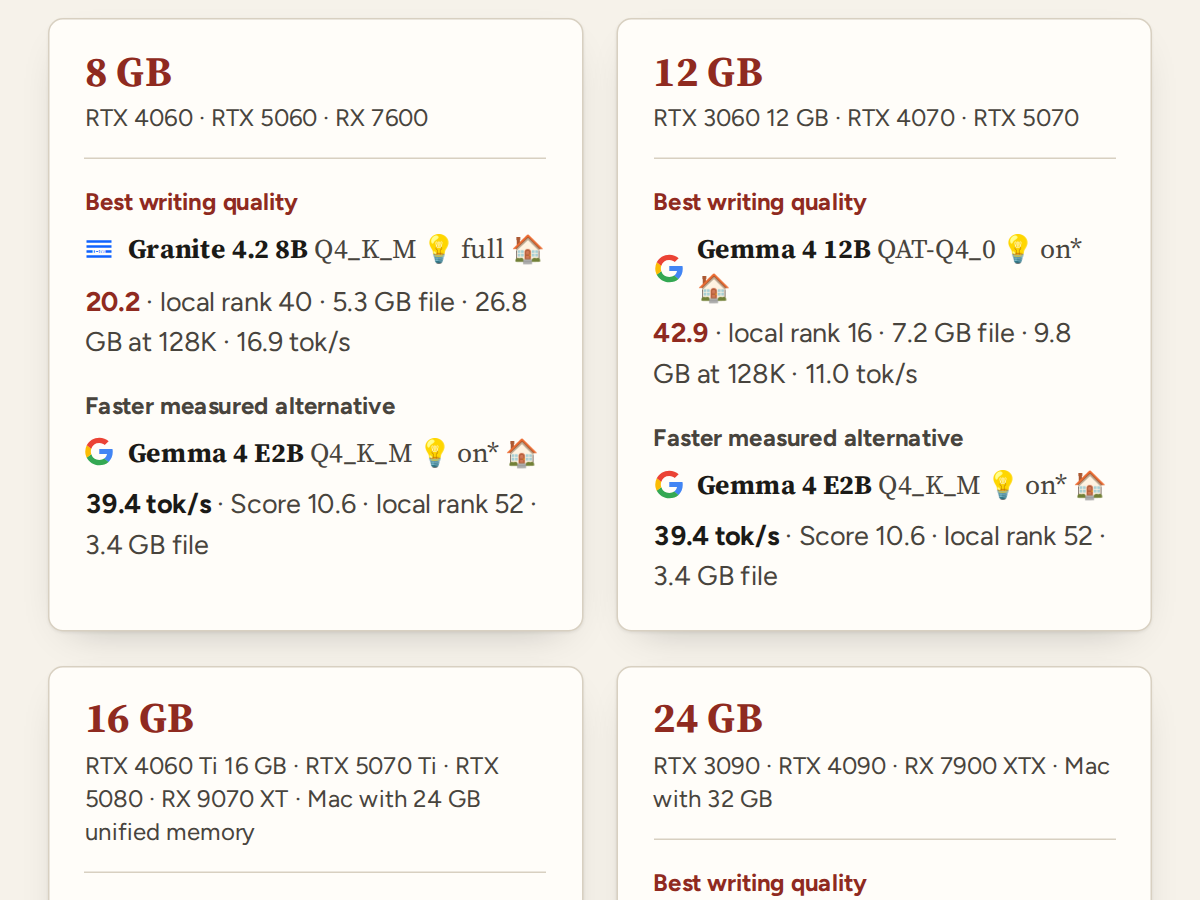
A live ranking of open-weight models for English writing, what each file needs in memory, and what fits in 16, 24, 32 or 128 GB.
Data-led articles on the judges, quantization, reasoning mode and the four languages.