

Which local AI writes best?
If you want one recommendation rather than a methodology, this is it:
Nemotron 3.5 Super VL by NVIDIA (thinking high) is the best local writer in the current selection, with a score of 73.3.
What counts as “local” here
Four conditions, applied strictly:
- Open weights. The model files must be publicly downloadable and runnable outside the vendor’s infrastructure.
- Genuinely runnable offline. Not a gated API with an open-sounding name.
- Under 256 billion total parameters. Strictly below the threshold.
- Already evaluated on this site. No estimates, no placeholder entries in the ranking itself.
The parameter limit applies to total parameters, including for mixture-of-experts models. It is a common mistake to forget this: an MoE model that activates a small fraction of its parameters per token still has to have all of its weights in memory. Total parameters determine eligibility and memory requirements; active parameters affect speed. When both counts are known, the model name keeps both (for example, 35B A3B) so the active count can inform speed expectations without being mistaken for a memory figure.
One thing the criteria do not require: that we generated the model’s responses on a machine in this office. What makes a model eligible is that the weights are available and the model can be run locally, wherever its benchmark texts were generated. Where a variant’s throughput was measured on our own hardware, the speed figure is labelled as an AIWB measurement. Figures taken from elsewhere are labelled as external or estimated. We would rather show a labelled estimate than a confident invention.
Open source is not the same as open weights
“Open source” is the phrase people search for, so it is worth untangling. Open source is a licensing claim broader than merely publishing weights; how that framework applies to all model artefacts is still contested. Most models in this ranking publish their weights under licences that range from permissive to distinctly restrictive, with commercial-use limits, acceptable-use clauses or redistribution conditions.
We rank on writing quality. The licence is a separate question, and an important one if you are shipping a product rather than drafting an email. Check it before you build on a model; it has no bearing on how well the model writes.
Only evaluated models
Models appear here only once they have been evaluated on the English corpus. Local generation has been suspended since 22 September 2026, so no new local model is being added for now; the variants already generated keep receiving verdicts, and their scores still move.
Quantization, without the marketing
Quantization stores a model’s weights using fewer bits per value. A model trained in 16-bit precision can be repackaged at 8 bits, or 4, shrinking the download and, more importantly, the memory footprint. At home, inference usually serves one user in short batches and is limited by how fast memory can be read rather than by raw compute, so a smaller file often runs faster too: there is less data to move per token.
It also changes the model. Sometimes barely; sometimes visibly.
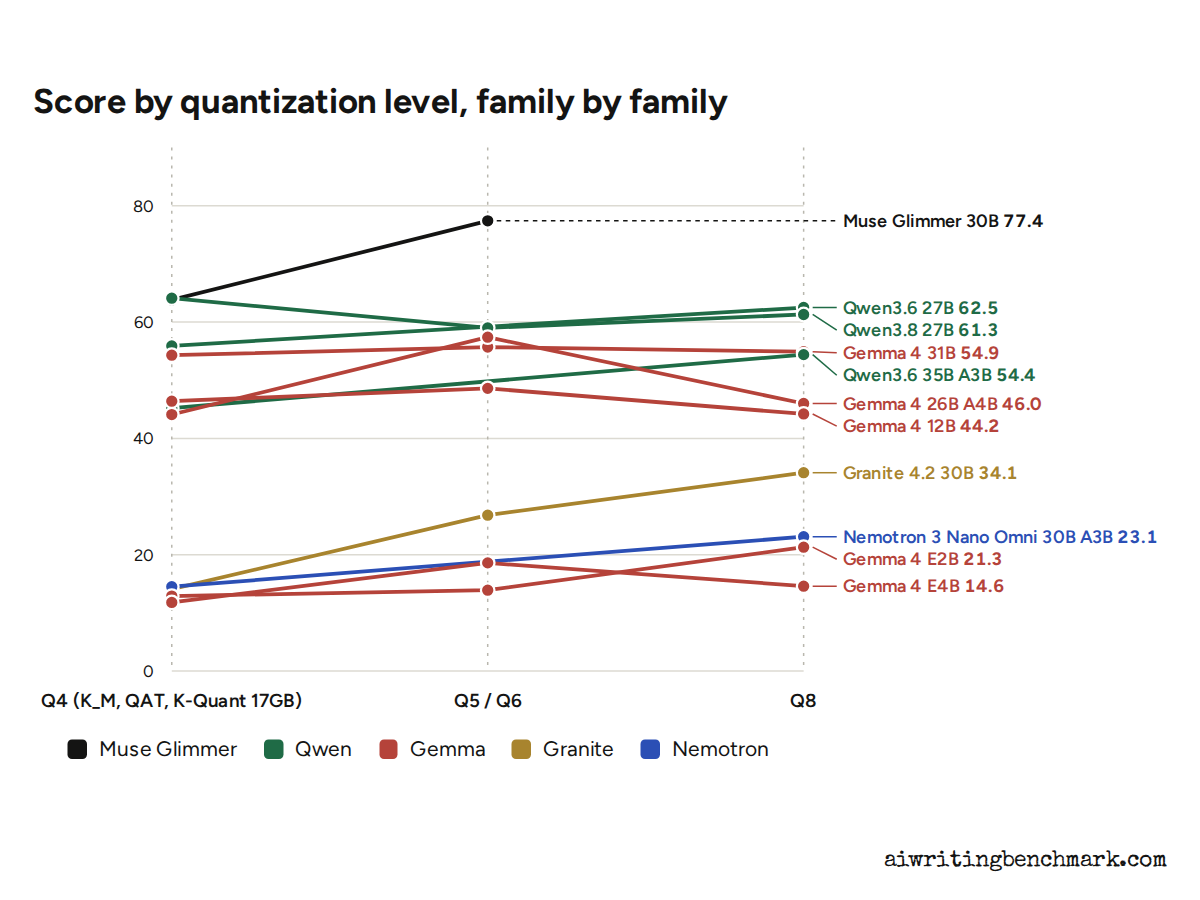
What we can say with confidence is that the size of the effect is not a constant. It varies with the model, the quantization method, the task, the language, the context length and the level of quantization. This is why you will not find a “Q4 keeps 98% of quality” claim on this page. That number does not exist as a general fact, and repeating it is how people end up disappointed by a specific model on a specific task.
The tags you’ll see in the filter, all shown by default:
- Q8: an eight-bit variant. We treat it as the practical high-quality reference point in this ranking: it is the version we reach for when memory allows. That is a working convention, not a claim that Q8 is mathematically equivalent to BF16 or FP16. Whether the remaining gap is measurable in English prose is an empirical question, and we prefer to answer it with paired tests rather than assertion.
- Q4 QAT: quantization-aware training. The model was prepared or trained with four-bit execution in mind, which makes it a distinct checkpoint rather than a post-hoc compression of an existing one.
- Q6: a six-bit GGUF quantization (Q6_K), between Q4 and Q8 in size. Depending on the family it can be the best build or the weakest, so read its row rather than assume.
- Q4: a four-bit GGUF quantization applied after training (Q4_K_M), with mixed precision across different parts of the model. This is not QAT, and the two should not be confused.
- ≈ Q4 (K-Quant) and ≈ Q5 (K-Quant Dynamic): Muse Glimmer’s two official builds, described in the next section.
Filters apply as you change them, and the state is carried in the URL, so a filtered view can be linked or bookmarked.
Muse Glimmer’s two K-Quant builds
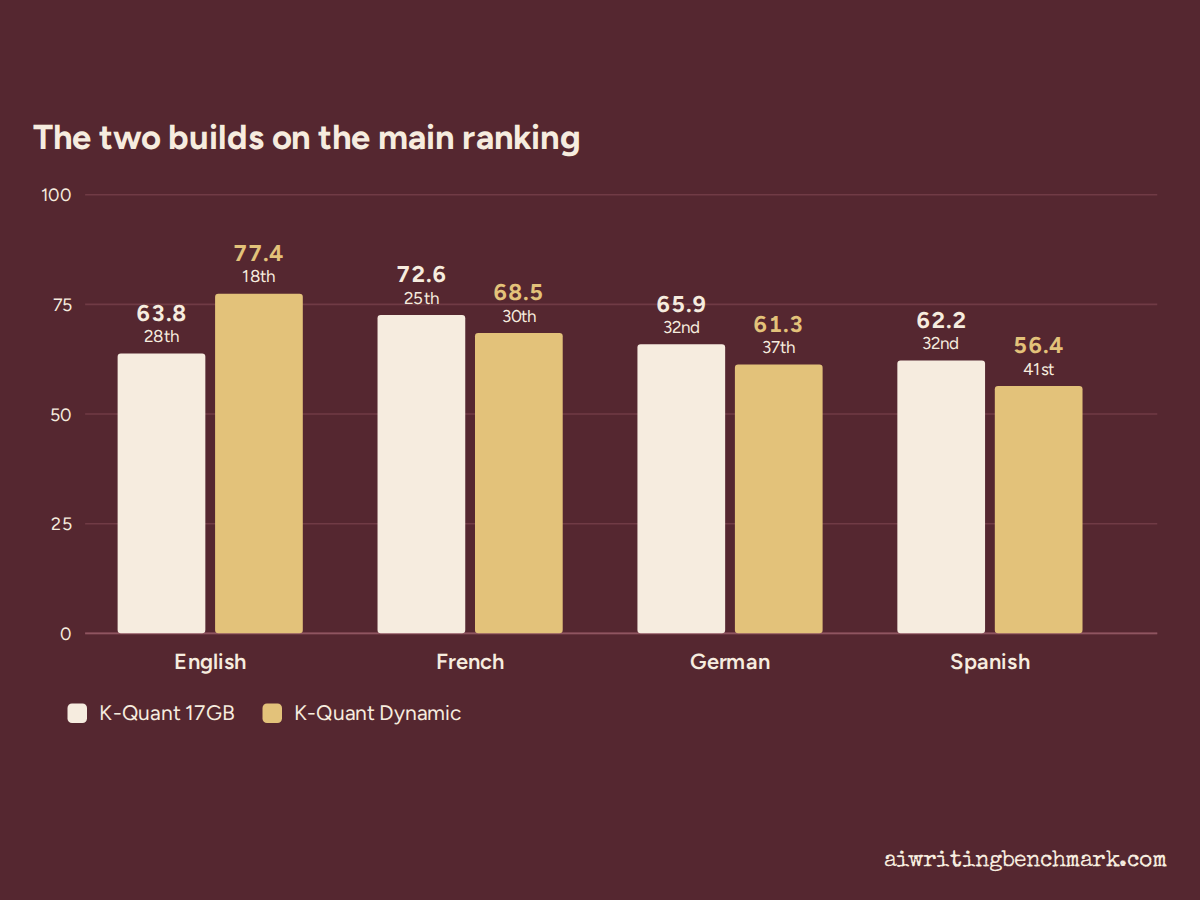
Meta publishes Muse Glimmer 30B in two unusual GGUF builds of roughly four and five bits per weight on average. K-Quant Dynamic keeps selected tensors at higher precision and targets 32 GB of VRAM; K-Quant 17GB compresses more aggressively and targets 24 GB. They are not Q4_K_M or Q6_K files, so we keep their exact names and score them as separate variants. Each has its own filter entry: K-Quant 17GB under ≈ Q4 (K-Quant), K-Quant Dynamic under ≈ Q5 (K-Quant Dynamic). The approximate sign says that the bit width is comparable, not the encoding.
Meta reports average degradation of 0.2% and 1.0% respectively across fifteen common benchmarks. Those are publisher measurements, not AIWB writing scores and not guarantees for English, French, German or Spanish prose. Our ranking scores the two files separately on native writing prompts, and the Muse Glimmer analysis gives their direct duels.
Hardware recommendations
The question we are asked most often is not “which model writes best” but “which model writes best on my machine”. This ladder answers it for the usual memory sizes, from an 8 GB graphics card to a workstation with 128 GB of unified memory. Each tier names the best-writing variant that fits, and the fastest variant we have measured that also fits. Tiers where nothing changes are merged.
8 GB
RTX 4060 · RTX 5060 · RX 7600
Best writing quality
 Granite 4.2 8B 💡 🏠
Faster measured alternative
 Gemma 4 E2B 💡 🏠
12 GB
RTX 3060 12 GB · RTX 4070 · RTX 5070
Best writing quality
Gemma 4 12B 💡 🏠
Faster measured alternative
Gemma 4 E2B 💡 🏠
16 GB
RTX 4060 Ti 16 GB · RTX 5070 Ti · RTX 5080 · RX 9070 XT · Mac with 24 GB unified memory
Best writing quality
Gemma 4 12B 💡 🏠
Faster measured alternative
Gemma 4 E2B 💡 🏠
24 GB
RTX 3090 · RTX 4090 · RX 7900 XTX · Mac with 32 GB
Best writing quality
 Muse Glimmer 30B 💡 🏠
Faster measured alternative
Gemma 4 E2B 💡 🏠
32–128 GB
32 GB: RTX 5090 · Mac with 48 GB48 GB: RTX 6000 Ada · two 24 GB cards · Mac with 64 GB · Strix Halo 64 GB64 GB: Mac with 96 GB96 GB: RTX PRO 6000 · Mac with 128 GB · DGX Spark · Strix Halo 128 GB (96 GB allocated)128 GB: Mac Studio with 192 GB or more
Best writing quality
Muse Glimmer 30B 💡 🏠
Faster measured alternative
Gemma 4 26B A4B 💡 🏠
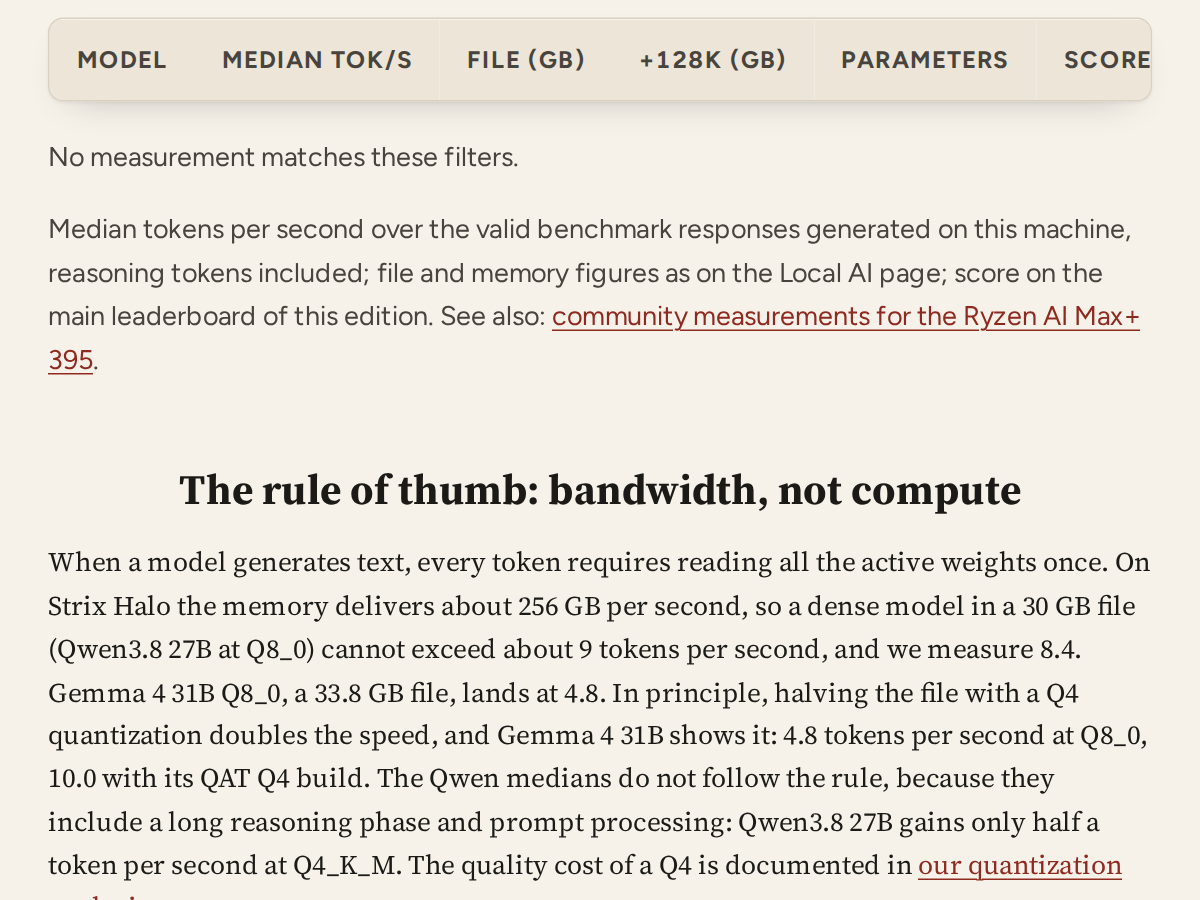
Loading guidance, not guarantees: context, KV cache, batch and runtime change the footprint. AIWB speeds were measured on the Strix Halo machine described on the Strix Halo speed page and do not predict another platform.
How “fits” is decided
A variant enters a tier when its estimated memory need is at or below the tier’s size. The estimate is the GGUF file plus 8% for the runtime’s buffers plus 2 GB for a short context, rounded up to the next standard card size. That is conservative for short prompts and optimistic for long ones: the “at 128K” figure on each card shows what the same variant needs with a 128,000-token context, KV cache included, and for some models it doubles the budget. If you work with long documents, read that number rather than the file size. The figures follow LM Studio’s default settings, in decimal gigabytes like LM Studio: the GGUF file we tested (with its vision projector where there is one) plus the F16 cache of the full-attention layers (sliding-window and recurrent layers barely grow, which is why Gemma 4 and Qwen 3.x need far less than a naive count suggests), with Flash Attention on. 128K means 131,072 tokens, the setting LM Studio offers. The ranking table also gives the figure at 256K, and can switch to a Q8 cache, almost half as heavy, and to the size of the MLX files for Macs.
Dedicated graphics card or unified memory
A graphics card offers the memory bandwidth that makes generation fast, but its size is fixed: 8, 12, 16, 24 or 32 GB on consumer cards. Unified-memory machines (Apple Silicon Macs, AMD Strix Halo, Nvidia DGX Spark) share one pool between processor and graphics. They hold models no consumer card can, but the pool is slower and not all of it is available to the model. Count roughly three quarters of unified memory as usable: that is why a Mac with 24 GB sits in the 16 GB tier, a 64 GB Strix Halo in the 48 GB tier and a 128 GB one in the 96 GB tier. The examples under each tier already apply that rule.
What more memory buys
Beyond 32 GB, no larger local model currently writes better English than the best 30-billion-parameter builds, so the top pick stops changing and the upper tiers merge. Extra memory still buys three things: the Q8 build of a family instead of its Q4 (the quantization analysis shows where that matters), a long context without spilling into system memory, and room to keep two models loaded at once. What it does not buy is speed. Generation is bound by memory bandwidth, and a 24 GB card is usually faster than a 128 GB unified pool on the same model.
About the speed figures
Tokens per second were measured on our own Strix Halo machine, reasoning tokens included; the Strix Halo speed page gives the details. They compare variants with each other; they do not predict your machine. A dedicated card typically generates two to four times faster than that machine for a model that fits its memory; a laptop processor without an accelerator, much slower. And when part of a model is offloaded to the processor, speed drops sharply even though the model technically “fits”.
Why bother running it locally at all
The cloud models at the top of our general leaderboard are strong. Local models are chosen for reasons that have nothing to do with beating them.
When the runtime and its integrations stay local, your text need not leave the machine, which is the main argument for anyone drafting confidential, legal, medical or unpublished material. It works with no connection, on a plane or a bad hotel connection. It doesn’t change underneath you: a checkpoint you downloaded behaves the same next month, where a cloud endpoint can be updated, deprecated or retired without warning. There’s no per-request cost and no rate limit. And you can inspect, fine-tune and integrate it on your own terms.
Set against that: you are trading some quality for that control, and you’re providing the hardware. Whether the trade is worth it is exactly the question this ranking exists to inform.
Quality against speed
These are separate axes, and we keep them separate on purpose. The ranking column measures how well a variant writes English. The speed figures measure how fast it produces tokens on specific hardware. Nothing in this page combines them into a single “best” score, because the right balance depends on what you’re doing.
Drafting a long article, where you’ll read and edit the output carefully, rewards quality. Interactive back-and-forth (rephrasing, brainstorming, dialogue) rewards responsiveness, and a slightly weaker model that answers in two seconds may serve you better than a stronger one that takes thirty. Both variants are listed in every hardware tier for that reason.
FAQ
What is the best local AI for writing in English?
The live summary above names the current top-ranked variant with its score and the memory it needs at 128K. Bear in mind that the top variant is only the best answer if it fits your memory with room for your context; the recommendations by memory size above are more useful for most readers.
What does “local LLM” mean?
An LLM is a large language model, the type of AI that generates text. A local LLM is one you download and run on your own computer, offline, rather than calling a service over the internet.
Why is there a 256B parameter limit?
The threshold keeps this page centred on models that remain plausible on personal or compact workstation hardware. It applies to total parameters, including for mixture-of-experts models, because all the weights must be in memory even when only a fraction is active per token. Larger systems are outside this page’s scope rather than impossible in absolute terms.
Does quantization ruin quality?
Not inherently, and not by a fixed amount. The effect depends on the model, the method, the task and the language. We show quantizations as separate ranked rows so you can see the difference where we’ve measured it, instead of trusting a general percentage.
What’s the difference between Q4 QAT and Q4_K_M?
Q4 QAT is a distinct checkpoint prepared or trained for four-bit execution. Q4_K_M is a four-bit GGUF quantization applied to an existing model after training, using mixed precision across its layers. They are not interchangeable and we never merge them into one row.
How much VRAM do I need?
More than the model file. Budget for the weights plus the runtime plus the KV cache, which grows with your context length. The memory ladder above gives recommendations for common graphics-card and unified-memory sizes with realistic headroom built in.
Is unified memory as good as VRAM?
For capacity, often better: unified-memory machines can hold models no consumer graphics card can. For bandwidth, generally not, and that difference shows up as slower generation. Don’t treat the two as equivalent.
Are open-weight models open source?
Not automatically. Publishing weights does not by itself establish an open-source licence, and model licences vary considerably in what they permit commercially. The licence is independent of writing quality; check it separately.
Why do these scores include comparisons against cloud models?
Because it keeps every variant on one scale and preserves its full match history. The rank is local; the score comes from the general English leaderboard.
How often does this page update?
Whenever new results are published. Rankings, filters and hardware recommendations are generated from the published data. Local generation has been suspended since 22 September 2026, so no new variant is being added for now, but the existing variants keep receiving verdicts and their scores still move.