




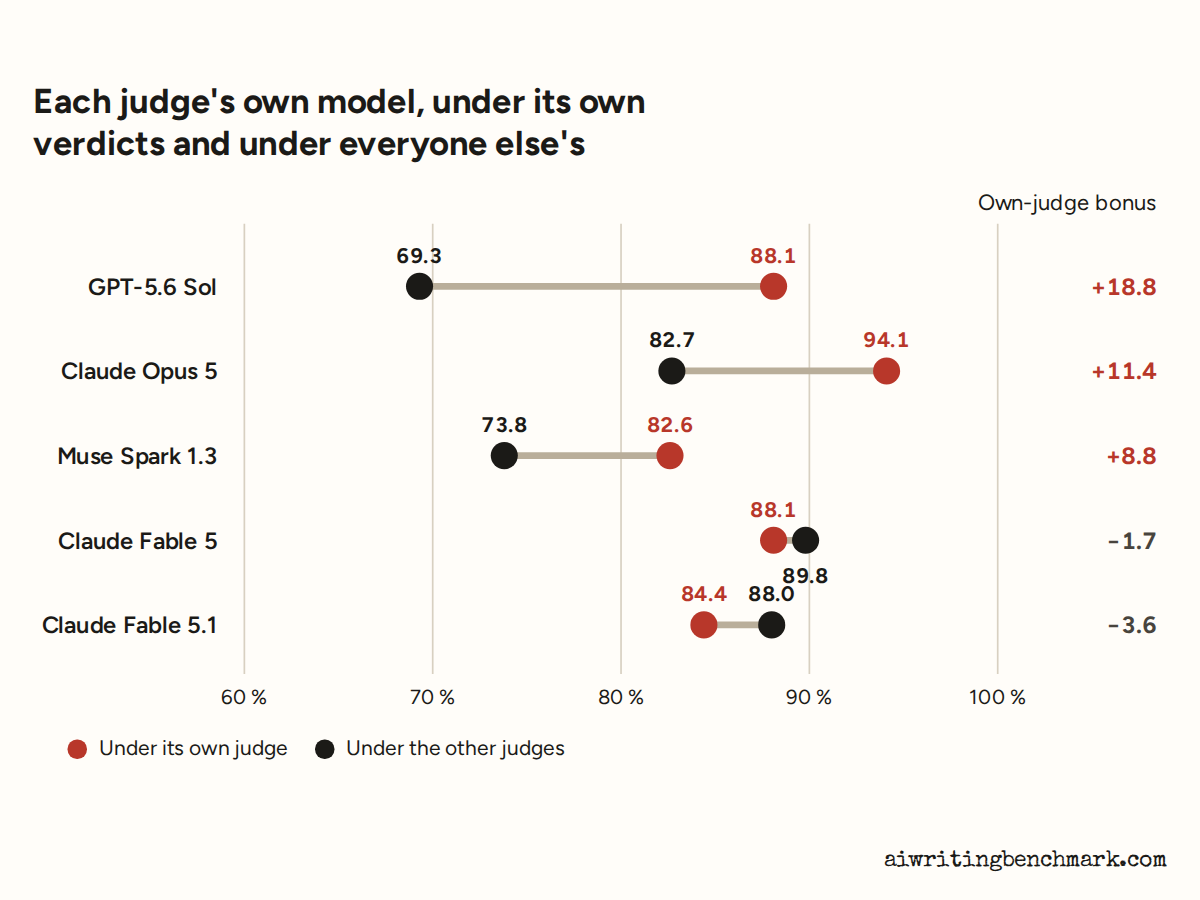
Do AI judges favour their own model? Two of five do, by up to 19 points
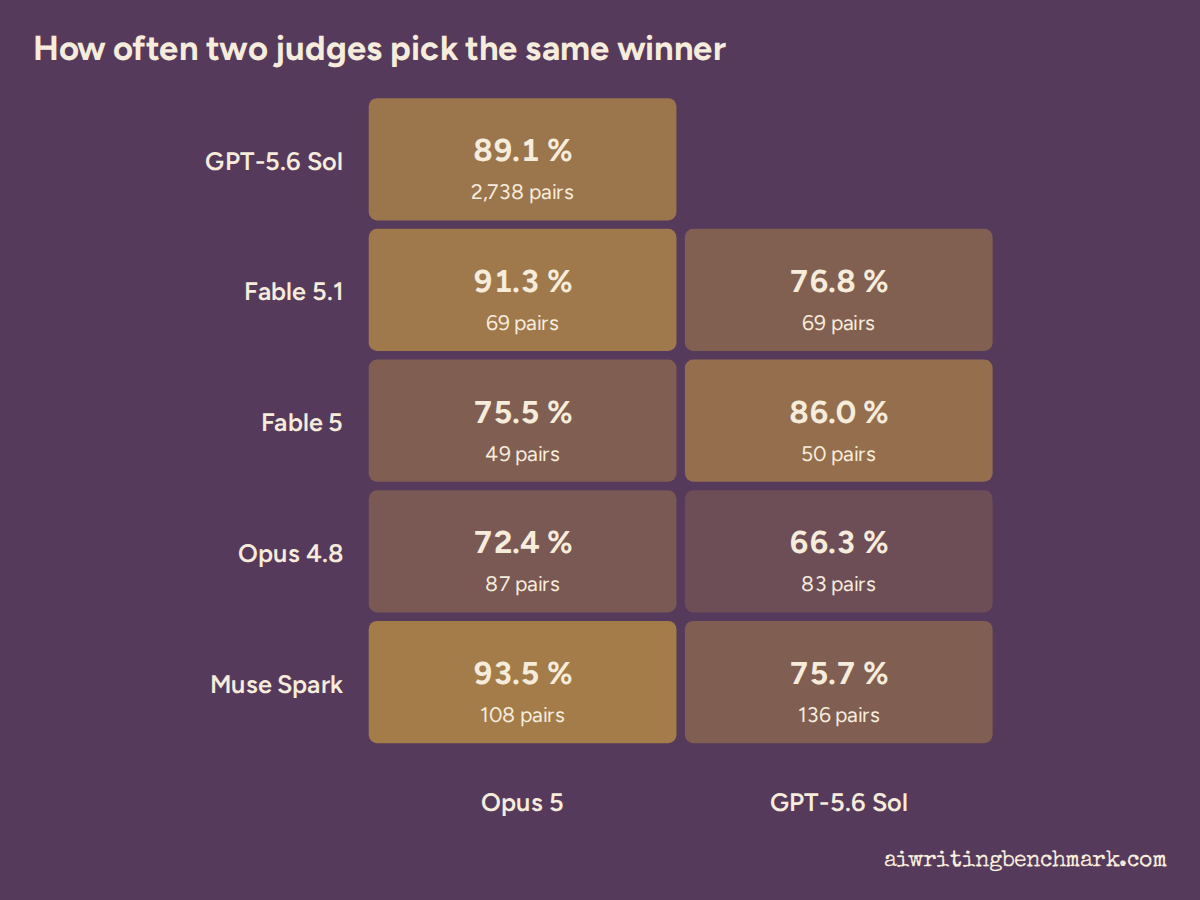
When GPT-5.6 Sol judges a duel involving GPT-5.6 Sol, its own texts collect 88% of the points; under the other judges they collect 69%. Claude Opus 5 shows the same lean, smaller. The two Claude Fable judges do the opposite and mark their own model down.