Last updated:

Model generation
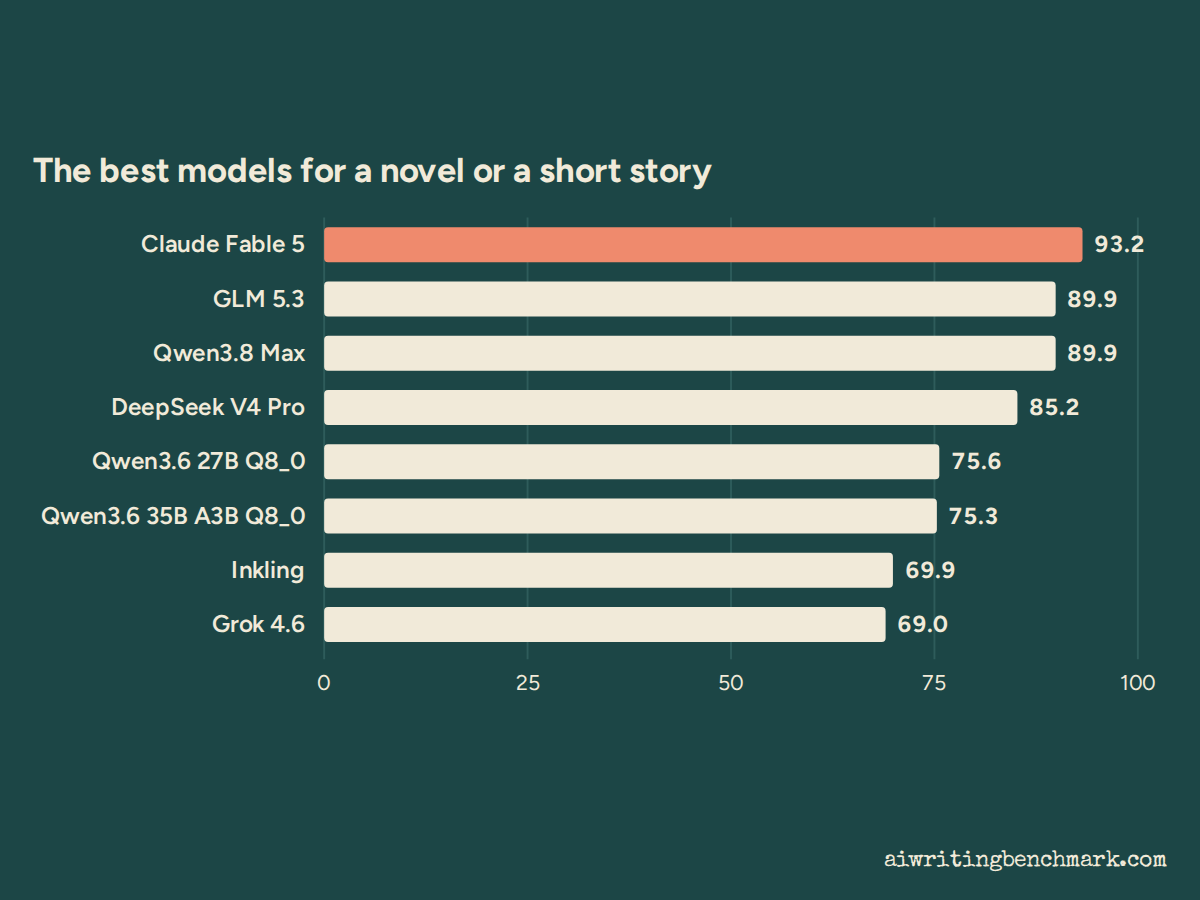
Writing model ranking based on pairwise results
RankModelAI judge scoreHuman score
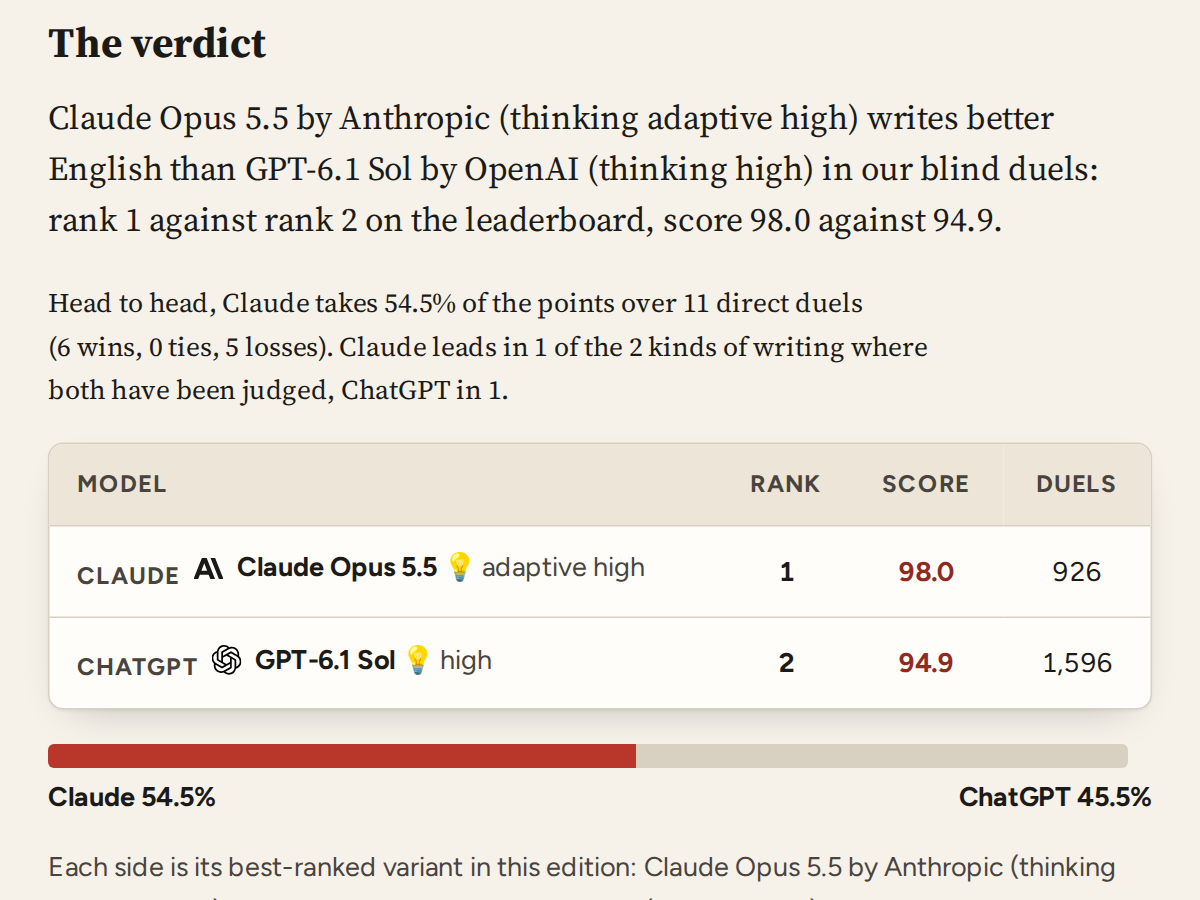
1GPT-6.1 Sol 💡 high95.3—
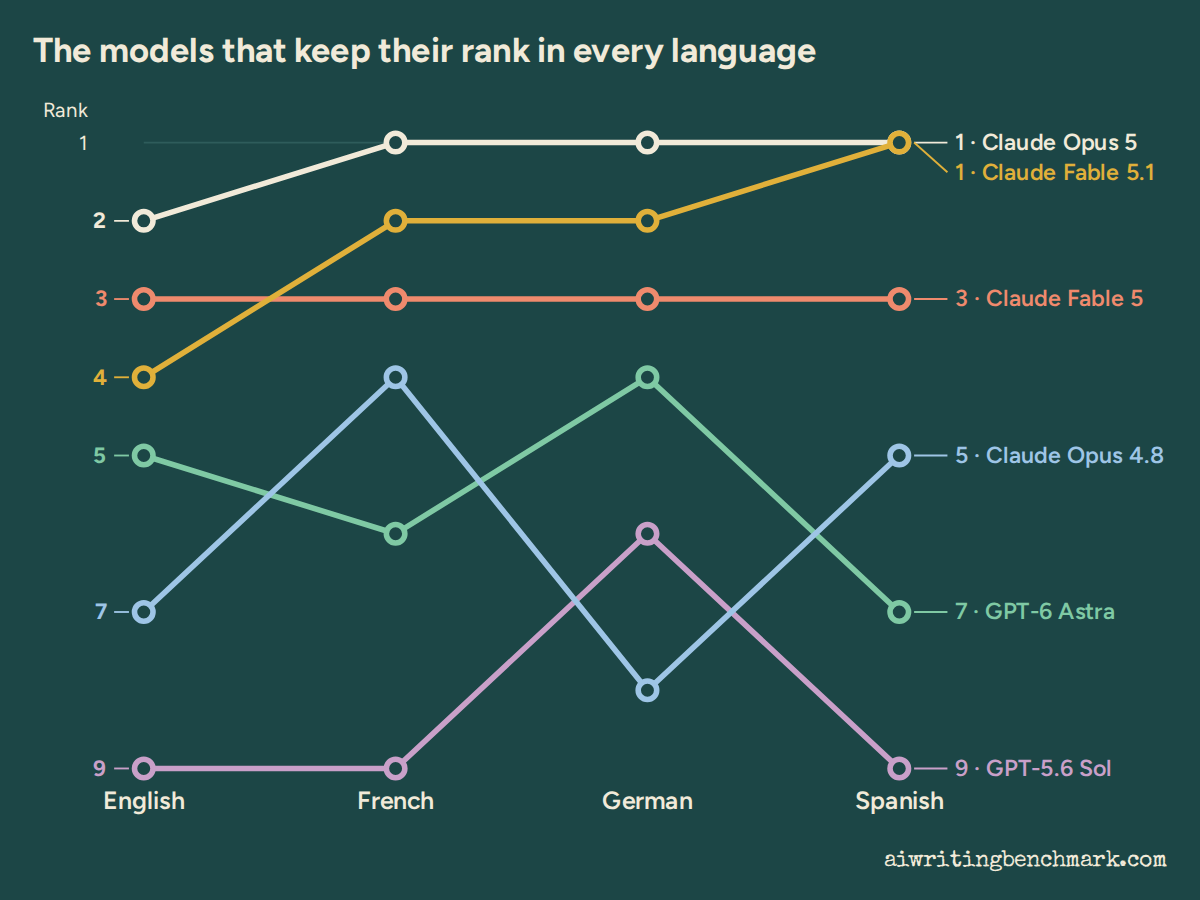
2Claude Opus 5.5 💡 adaptive high93.1—
3Kimi K3.1 Pro 💡 high91.9—
4GPT-6 Astra 💡 high91.4—
5Kimi K3 💡 enabled91.1—
6Claude Fable 5 💡 adaptive high89.0—
6Claude Sonnet 5.5 💡 adaptive high89.0—
8Claude Fable 5.1 💡 adaptive high88.4—
9GPT-6 Sol 💡 high87.5—
10Claude Opus 5 💡 adaptive high87.3—
10GLM 5.3 💡 max87.3—
13Grok 4.7 💡 high85.9—
14GPT-6.1 Terra 💡 high84.9—
15Claude Sonnet 5 💡 adaptive high84.0—
16Aion 3.5 💡 high82.4—
17GLM 5.3 Flash 💡 high79.2—
17GPT-5.6 Sol 💡 high79.2—
19GPT-6 Luna 💡 high79.0—
20Muse Spark 1.3 💡 high78.4—
21DeepSeek V4.1 Flash 💡 high77.7—
22MiniMax M3 💡 enabled77.4—
23Muse Spark 1.2 💡 high76.4—
24Step 5 Preview fp8 💡 high76.0—
25Mercury 3 💡 high75.9—
26Gemini 3.8 Flash 💡 high75.6—
26MiMo V2.6 Pro fp8 💡 high75.6—
28GLM 5.2 💡 enabled75.0—
29Hy3 💡 high74.4—
30Nemotron 3.5 Super VL 💡 high73.3—
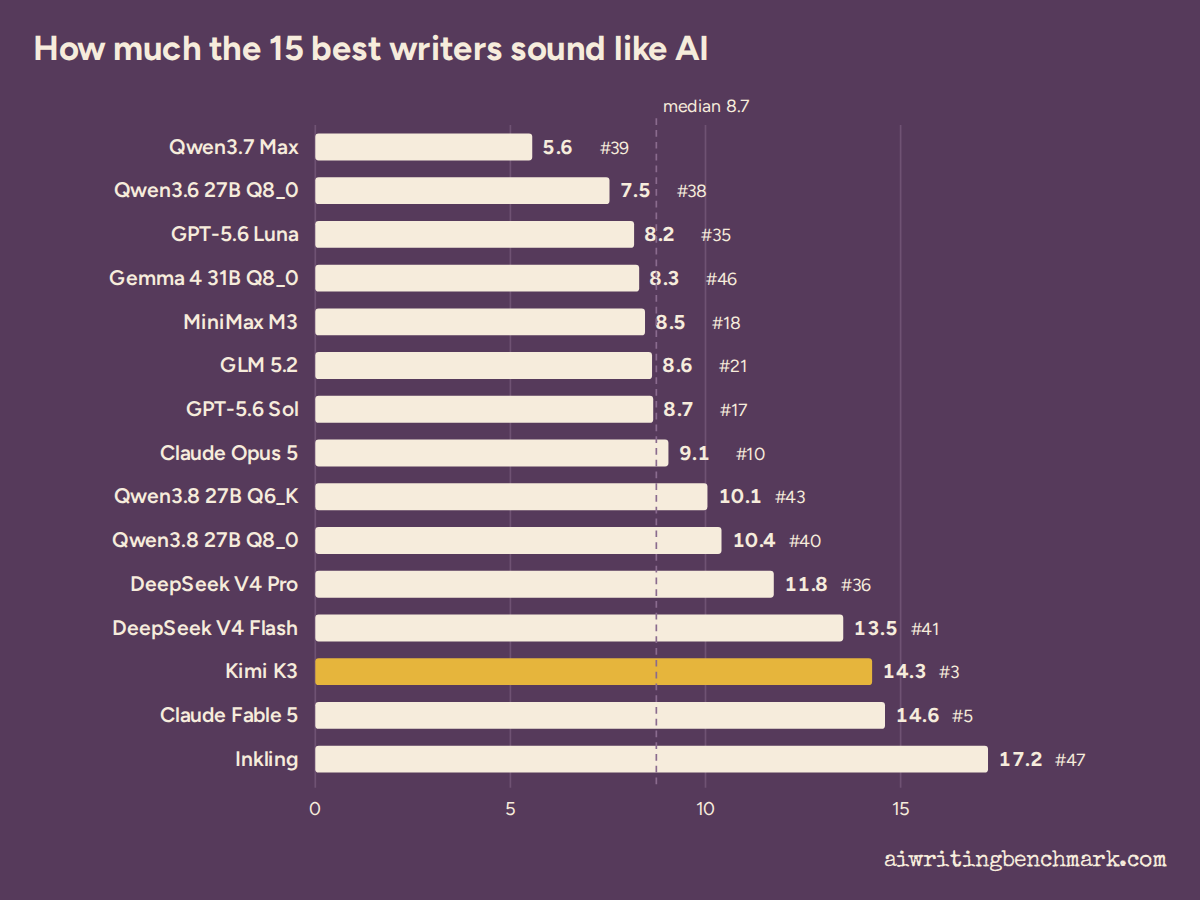
31Qwen3.8 Max 💡 xhigh71.5—
33Beam 1.0 💡 high70.1—
34Claude Haiku 5.5 💡 adaptive high69.3—
35Hy4 Preview 💡 high69.1—
37Aion 3.0 💡 mandatory68.0—
37Gemini 3.7 Flash 💡 medium68.0—
37Ling 3.1 Flash 💡 high68.0—
40Grok 4.6 💡 high67.4—
41Gemini 4 Argon 💡 high66.0—
42GPT-5.6 Terra 💡 high65.9—
44GPT-5.6 Luna 💡 high58.3—
45DeepSeek V4 Pro 💡 enabled58.0—
46Mistral Large 4 💡 high57.8—
48Qwen3.6 27B Q8_0 💡 on* 🏠56.9—
50Qwen3.7 Max 💡 enabled56.0—
51Qwen3.8 27B Q8_0 💡 xhigh** 🏠55.8—
52DeepSeek V4 Flash 💡 enabled53.5—
53Gemma 4 31B Q8_0 💡 on* 🏠52.557.6
55Qwen3.8 Flash 💡 high51.5—
56Inkling 💡 high50.4—
60Qwen3.7 Plus 💡 enabled48.8—
61MiMo V2.6 Flash 💡 high47.9—
63Qwen3.6 35B A3B Q8_0 💡 on* 🏠45.345.0
64MiMo V2.5 Pro 💡 enabled43.2—
65Nemotron 3 Ultra 💡 high42.4—
66Gemma 4 31B Q8_0 ↯ 🏠41.3—
70MiMo V2.5 💡 enabled40.3—
72Gemma 4 26B A4B Q8_0 💡 on* 🏠39.542.4
73Gemma 4 12B Q8_0 💡 on* 🏠39.355.0
79Gemma 4 12B Q8_0 ↯ 🏠33.1—
80MiniMax M3.1 Flash 💡 high32.1—
81Seed 2.1 Turbo ↯31.7—
82Gemma 4 26B A4B Q8_0 ↯ 🏠31.1—
83Nemotron 3.5 Lightning 💡 high29.9—
86Agnes 3.0 Flash 💡 high27.8—
88Qwen3.6 27B Q8_0 ↯ 🏠25.2—
89Granite 4.2 30B Q8_0 💡 full 🏠24.9—
93Mistral Medium 3.5 💡 high21.8—
94Qwen3.6 35B A3B Q8_0 ↯ 🏠20.1—
96Qwen3.8 27B Q8_0 ↯ 🏠18.6—
99Granite 4.2 8B Q8_0 💡 full 🏠17.5—
99Nemotron 3 Nano Omni 30B A3B Q8_0 💡 on* 🏠17.5—
102Gemma 4 E2B Q8_0 💡 on* 🏠15.7—
107Gemma 4 E4B Q8_0 💡 on* 🏠12.8—
108Gemma 4 E4B Q8_0 ↯ 🏠11.3—
113Gemma 4 E2B Q8_0 ↯ 🏠10.0—

115 models compared128,991 published AI verdicts

Method: regularized Bradley–Terry model. The AI-judge score determines rank; the human score is independent and remains secondary until more community votes are available. A score of 50 means an estimated one-in-two chance of beating the average model in this language and category.

Direct duel results

Each cell shows the share of available points earned by the row model against the column model: a win is worth 100%, a tie 50%, and a loss 0%. This result matrix uses only the compatible evaluation protocols included in the main ranking.

Directional matrix of points earned in direct duels. Values above 50% favour the row model; values below 50% favour the column model.

0 %100 %

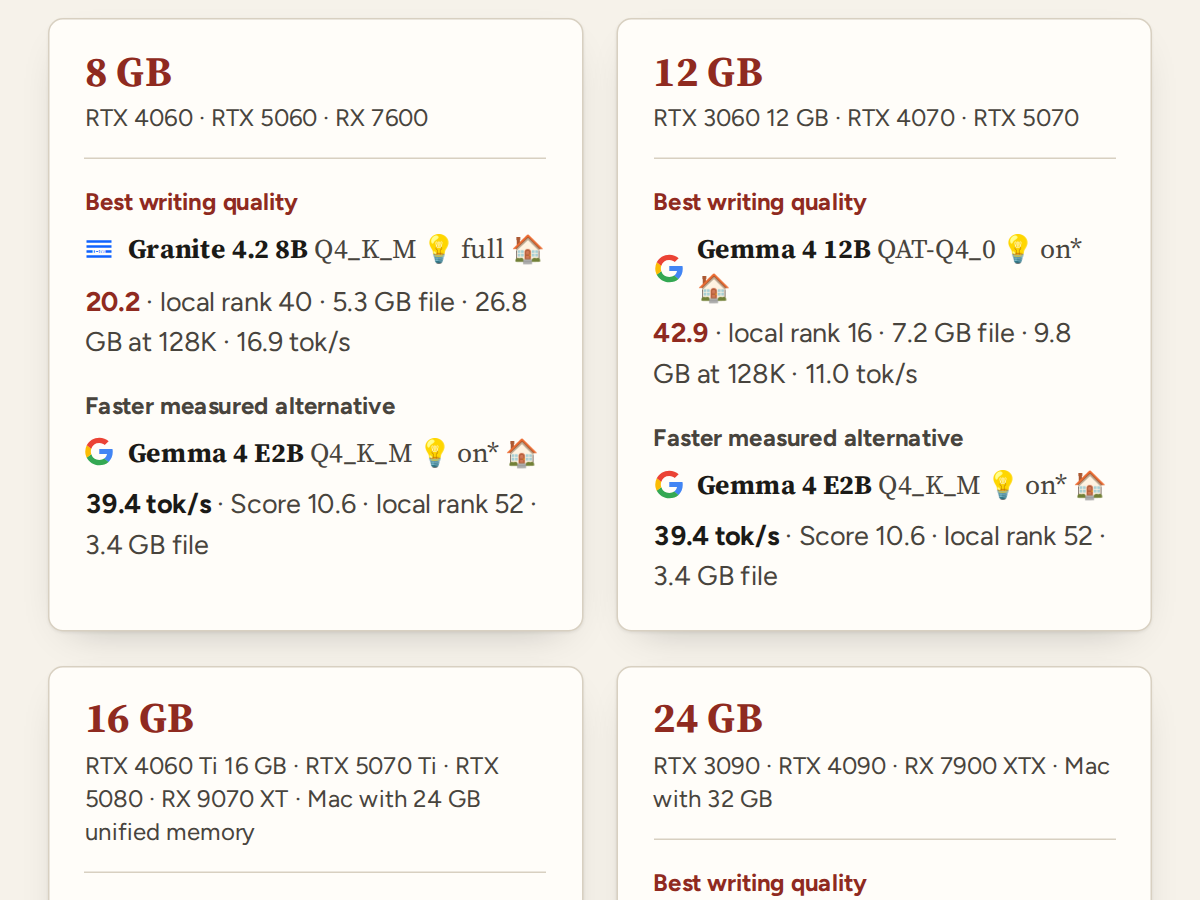
💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Points earned in direct duels by model pair
Model

Published duel coverage

Each cell shows how many published AI-judged duels across all published evaluation protocols compare the two models for this language and category. The models on both axes are candidates; this matrix does not show which judge produced each verdict.

Symmetric matrix of published duel counts. The diagonal is zero because a model is not compared with itself.

0

💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Published duel counts by model pair
Model

Help elect the best LLM for writing in English

Which model writes the better text? Judge this anonymous pair and contribute to the human ranking. Model names stay hidden during the duel and are revealed only after your choice.

Arena