Claude or ChatGPT for writing in English?
The two most-asked-about assistants, judged on the same English prompts in blind duels: which one writes better, by how much, and for which kinds of text. Updated with every export of the ranking.
The verdict
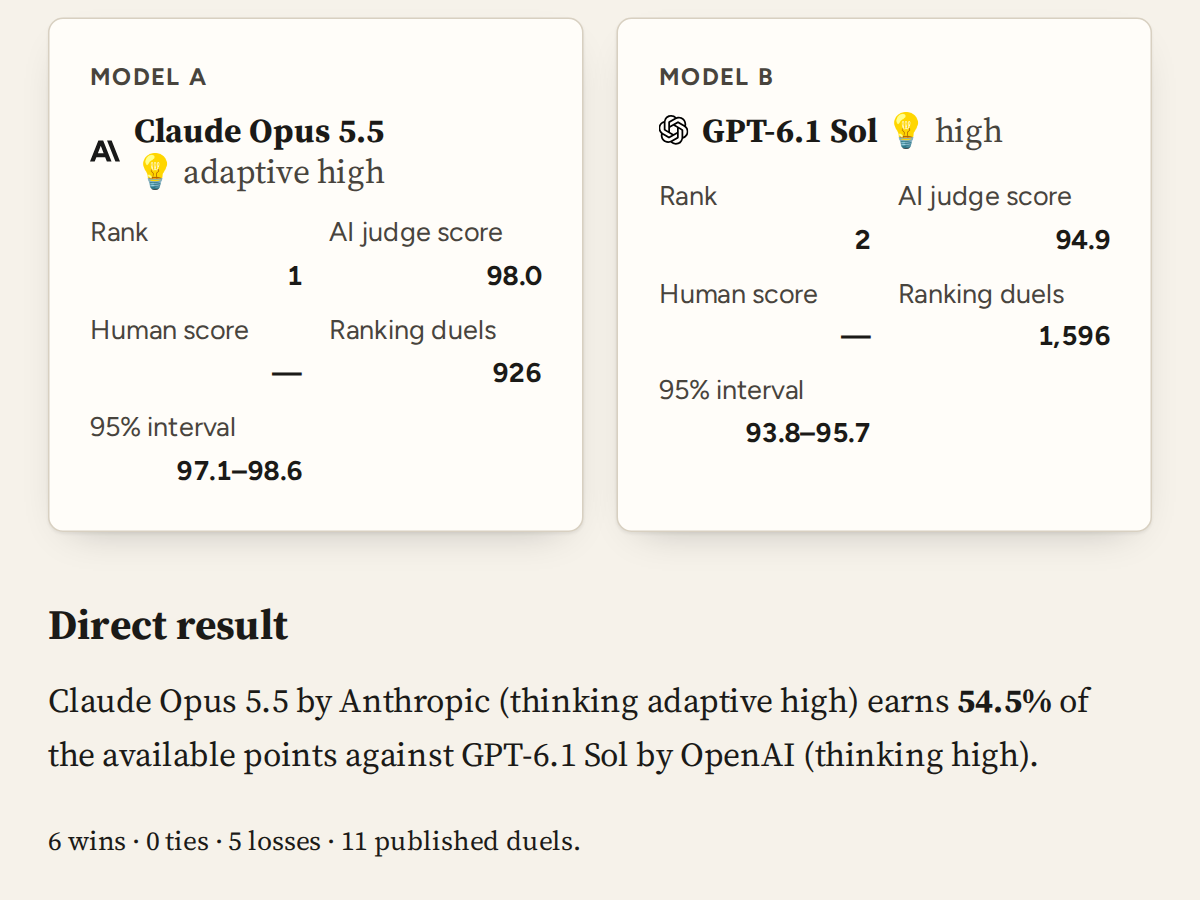
In our blind duels the two are level: Claude Opus 5.5 by Anthropic (thinking adaptive high) ranks 2 with 94.8, GPT-6.1 Sol by OpenAI (thinking high) ranks 1 with 95.7.
Head to head, Claude takes 55.6% of the points over 18 direct duels (10 wins, 0 ties, 8 losses). Claude leads in 1 of the 10 kinds of writing where both have been judged, ChatGPT in 9.
| Model | Rank | Score | Duels |
|---|---|---|---|
Claude  Claude Opus 5.5 💡 | 2 | 94.8 | 1,522 |
ChatGPT  GPT-6.1 Sol 💡 | 1 | 95.7 | 2,595 |
Each side is its best-ranked variant in this edition: Claude Opus 5.5 by Anthropic (thinking adaptive high) for Claude, GPT-6.1 Sol by OpenAI (thinking high) for ChatGPT. When a better variant of either arrives, this page follows it.
Kind of writing by kind of writing
Score and rank recomputed on the duels of each category alone; the leader is in colour. Click a kind of writing for its full ranking.
| Kind of writing | Claude | ChatGPT | Direct duels |
|---|---|---|---|
| Articles, blogs and editorial | 95.6 #2 | 97.4 #1 | 1–0–0 |
| Dialogue and screenplay | 91.0 #11 | 98.3 #1 | 0–0–1 |
| Explanation and popularization | 68.2 #29 | 73.0 #22 | — |
| Fiction and narrative | 94.2 #10 | 95.7 #6 | 0–0–1 |
| Marketing and sales | 43.4 #62 | 94.3 #6 | 0–0–1 |
| Personal communication | 98.6 #1 | 97.5 #2 | 6–0–4 |
| Professional and administrative | 61.1 #47 | 85.2 #5 | 0–0–1 |
| Social media and short formats | 96.7 #2 | 96.8 #1 | 1–0–0 |
| Speech and public speaking | 97.6 #2 | 98.2 #1 | 1–0–0 |
| Structured documents and reports | 93.0 #3 | 97.3 #1 | 1–0–0 |
Direct duels read wins–ties–losses for the first model. A dash means the model has not yet been judged in that category.
What each side stands for
“Claude” here is whichever Anthropic model currently ranks highest on the English leaderboard, and “ChatGPT” whichever OpenAI model does. Both companies ship several models at once, and the one you get in the app depends on your plan and on the day. The table above names the exact variants and the reasoning setting they ran with; the other variants of each family sit a few places apart on the full leaderboard.
What the numbers measure
Every score on this page comes from blind duels: two anonymous texts written for the same English prompt, an AI judge picking the better one without seeing the model names, thousands of times over. The direct record counts only the duels where these two exact variants met. The kind-of-writing table recomputes the ranking on the duels of one category alone, so an email is not judged by a short story.
How to choose
If the verdict is close, the kind of writing decides. Personal letters and emails, marketing copy and speeches tend to separate the two more than reports and explanations do. Look at the categories you write most, then read the example pair at the bottom: it is one real duel, with the published verdict, and a better guide to voice than any score.
Writing example
Prompt
Write a very short screenplay scene (50–150 words) in standard screenplay format, including a scene heading and character cues. The setting is a late-night diner where a tired waitress named Marla tries to convince the only remaining customer, an out-of-towner named Chris who has missed the last bus, that the couch in the back is safer than walking three miles in the dark. Keep the dialogue natural and slightly wry, and let a small detail hint that Marla has done this before.
Published verdict: ChatGPT (judged by GPT-6 Sol).
Claude · Claude Opus 5.5 💡
INT. BIRDIE'S DINER - NIGHT
Rain ticks against the windows. MARLA (50s) wipes the counter around CHRIS (30s), who nurses cold coffee beside a duffel bag.
CHRIS
It's three miles. I've walked farther.
MARLA
In daylight. Without the Hendricks' dogs.
CHRIS
The dogs are a factor?
MARLA
The dogs are the whole factor.
Marla reaches under the register and pulls out a folded blanket and a toothbrush still in its wrapper. A strip of masking tape on the blanket reads: GUEST #14.
CHRIS
Fourteen?
MARLA
Fifteen tonight. I'll need more tape.
Chris eyes the dark door, then the blanket.
CHRIS
Does the couch have springs?
MARLA
Two. You'll meet them.
ChatGPT · GPT-6.1 Sol 💡
INT. ROADSIDE DINER - NIGHT
MARLA rubs her eyes behind the counter. CHRIS, the only customer, pulls on his coat.
CHRIS
Motel’s three miles. I can walk.
MARLA
You can. There’s no shoulder after
the bridge, though.
CHRIS
Last bus really means last bus here?
MARLA
We’re pretty literal.
She lifts the counter flap.
MARLA
There’s a couch in back. Safer than
finding out how fast the trucks go.
Chris looks toward the dark windows.
CHRIS
You sure I’m not putting you out?
MARLA
I’m putting you on a couch.
Different thing.
She opens a drawer beside the register: several wrapped toothbrushes.
MARLA
Bathroom’s on the left.