Last updated:

Model generation
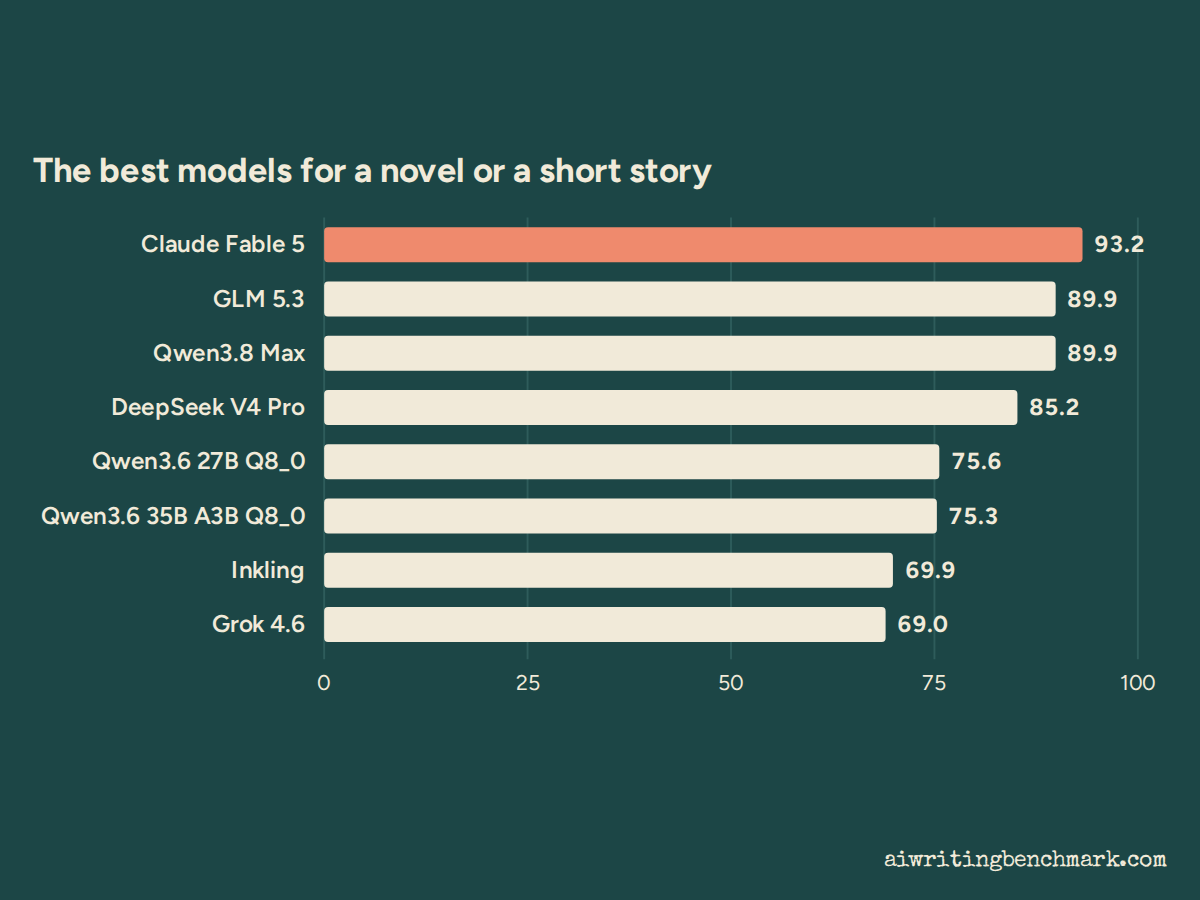
Writing model ranking based on pairwise results
RankModelAI judge scoreHuman score
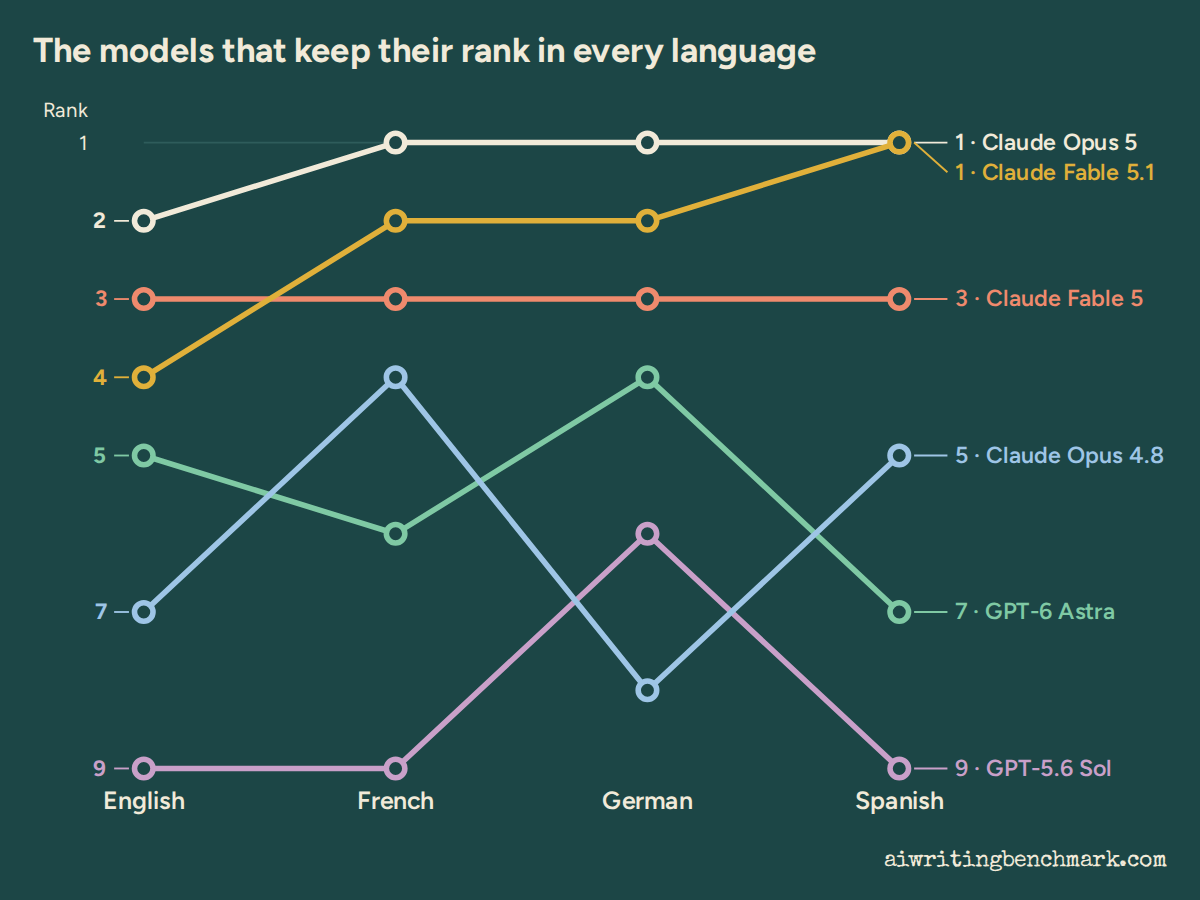
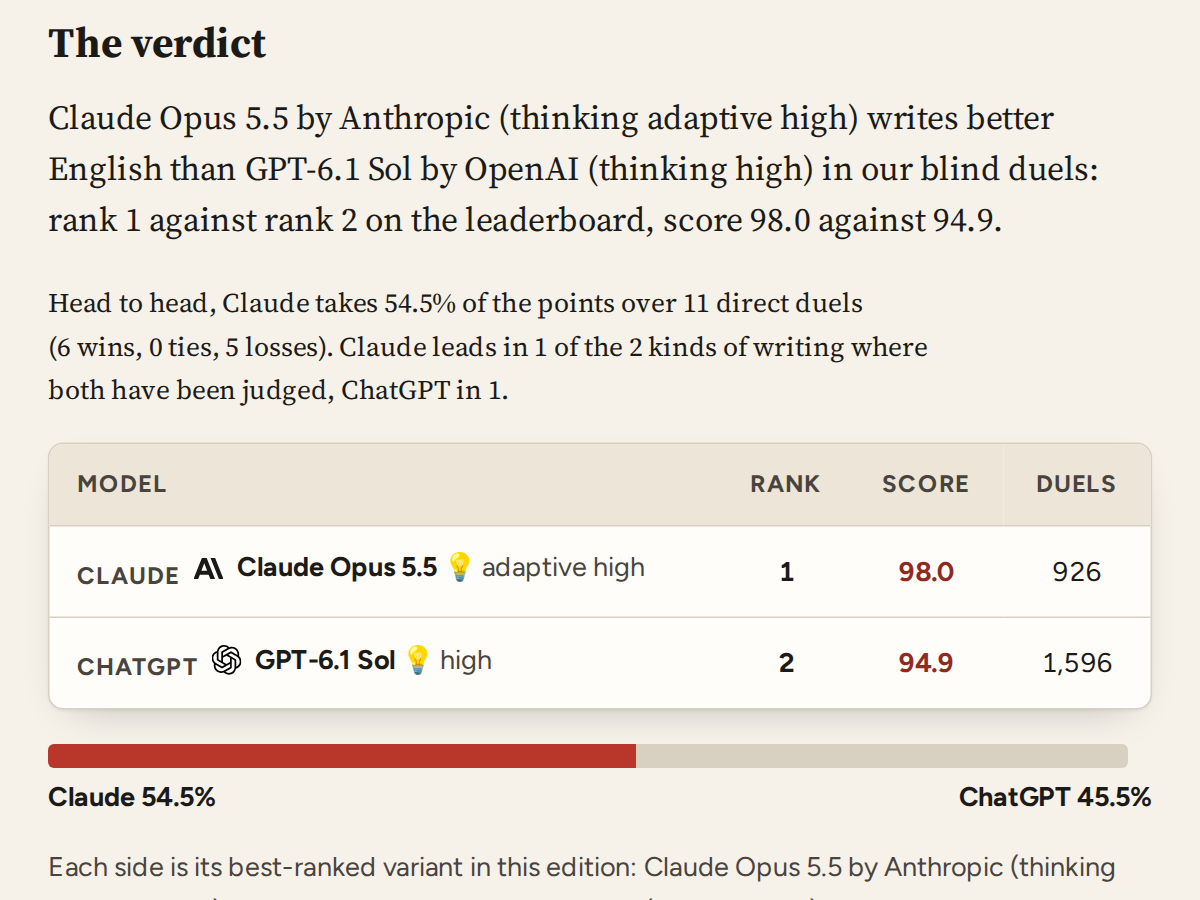
1GPT-6.1 Sol 💡 high95.7—
2Claude Opus 5.5 💡 adaptive high94.8—
3Kimi K3 💡 enabled92.2—
4GPT-6 Astra 💡 high91.9—
5Claude Fable 5 💡 adaptive high89.7—
6Claude Fable 5.1 💡 adaptive high89.4—
7Claude Sonnet 5.5 💡 adaptive high89.1—
7GPT-6 Sol 💡 high89.1—
9GLM 5.3 💡 max88.7—
10Claude Opus 5 💡 adaptive high88.1—
12Grok 4.7 💡 high87.6—
13Claude Sonnet 5 💡 adaptive high85.0—
14Aion 3.5 💡 high84.0—
15GLM 5.3 Flash 💡 high81.4—
16GPT-5.6 Sol 💡 high80.5—
17MiMo V2.6 Pro fp8 💡 high79.7—
18MiniMax M3 💡 enabled79.5—
19GPT-6 Luna 💡 high79.4—
19Muse Spark 1.3 💡 high79.4—
21DeepSeek V4.1 Flash 💡 high78.0—
22Muse Spark 1.2 💡 high77.7—
23GLM 5.2 💡 enabled77.6—
24Hy3 💡 high77.3—
25Gemini 3.8 Flash 💡 high76.9—
26Claude Haiku 5.5 💡 adaptive high74.1—
27Ling 3.1 Flash 💡 high73.4—
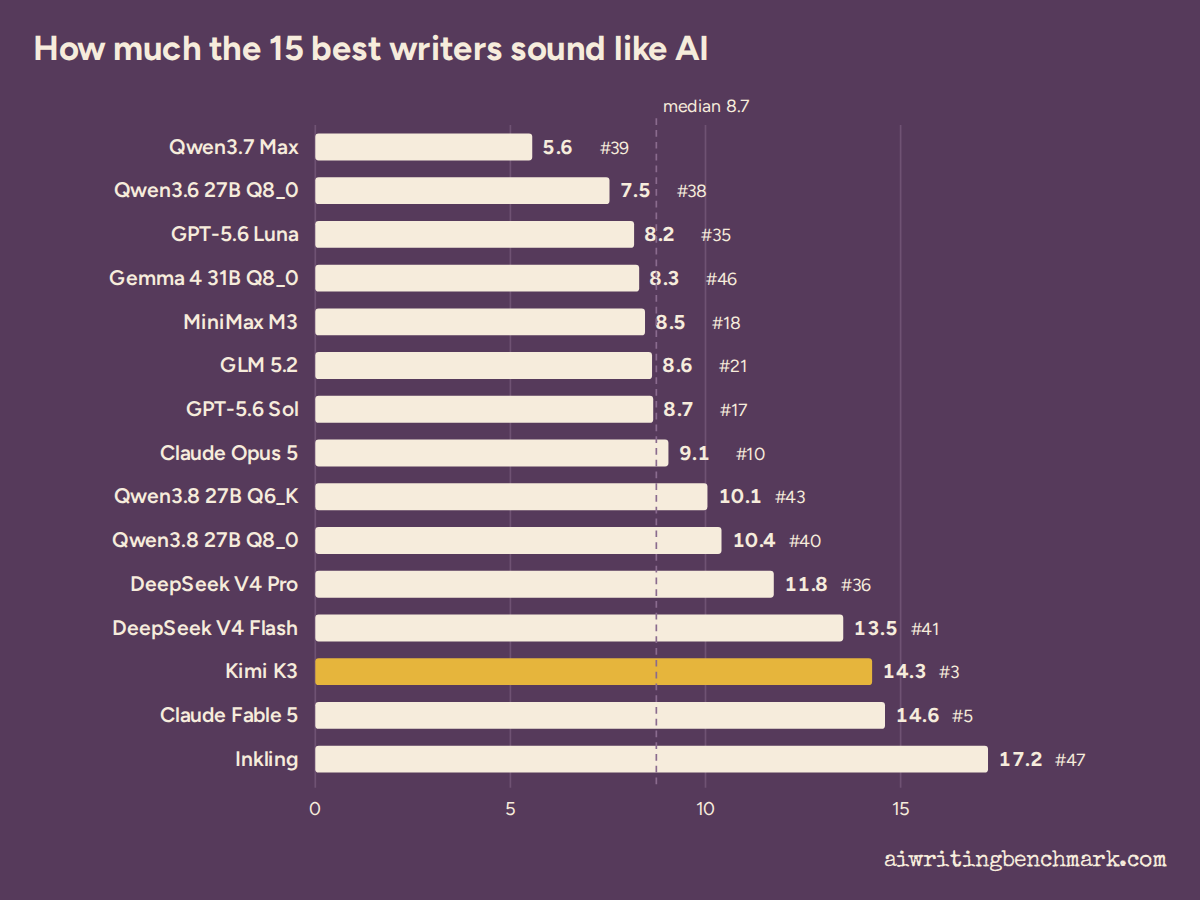
28Qwen3.8 Max 💡 xhigh72.6—
30Hy4 Preview 💡 high70.3—
32Aion 3.0 💡 mandatory69.6—
33Gemini 3.7 Flash 💡 medium69.5—
34Grok 4.6 💡 high69.0—
35Mistral Large 4 💡 high66.5—
36GPT-5.6 Terra 💡 high65.9—
38GPT-5.6 Luna 💡 high60.0—
39DeepSeek V4 Pro 💡 enabled59.3—
41Qwen3.6 27B Q8_0 💡 on* 🏠58.6—
42Qwen3.7 Max 💡 enabled57.7—
43Qwen3.8 27B Q8_0 💡 xhigh** 🏠57.5—
45DeepSeek V4 Flash 💡 enabled55.2—
47Gemma 4 31B Q8_0 💡 on* 🏠53.558.5
48Qwen3.8 Flash 💡 high52.9—
49Inkling 💡 high52.2—
53Qwen3.7 Plus 💡 enabled50.2—
54MiMo V2.6 Flash 💡 high50.1—
55Qwen3.6 35B A3B Q8_0 💡 on* 🏠47.545.0
56MiniMax M3.1 Flash 💡 high47.4—
58MiMo V2.5 Pro 💡 enabled45.3—
59Gemma 4 31B Q8_0 ↯ 🏠43.3—
62MiMo V2.5 💡 enabled42.1—
65Gemma 4 12B Q8_0 💡 on* 🏠41.355.0
65Gemma 4 26B A4B Q8_0 💡 on* 🏠41.341.5
69Nemotron 3 Ultra 💡 high38.5—
73Gemma 4 12B Q8_0 ↯ 🏠34.9—
74Seed 2.1 Turbo ↯34.2—
75Gemma 4 26B A4B Q8_0 ↯ 🏠32.0—
76Nemotron 3.5 Lightning 💡 high30.8—
77Agnes 3.0 Flash 💡 high29.9—
81Qwen3.6 27B Q8_0 ↯ 🏠26.5—
84Granite 4.2 30B Q8_0 💡 full 🏠25.7—
86Mistral Medium 3.5 💡 high22.4—
87Qwen3.6 35B A3B Q8_0 ↯ 🏠21.2—
91Qwen3.8 27B Q8_0 ↯ 🏠19.3—
92Granite 4.2 8B Q8_0 💡 full 🏠18.5—
93Nemotron 3 Nano Omni 30B A3B Q8_0 💡 on* 🏠18.4—
95Gemma 4 E2B Q8_0 💡 on* 🏠16.6—
100Gemma 4 E4B Q8_0 💡 on* 🏠13.4—
101Gemma 4 E4B Q8_0 ↯ 🏠11.8—
105Gemma 4 E2B Q8_0 ↯ 🏠10.4—

108 models compared115,791 published AI verdicts

Method: regularized Bradley–Terry model. The AI-judge score determines rank; the human score is independent and remains secondary until more community votes are available. A score of 50 means an estimated one-in-two chance of beating the average model in this language and category.

Direct duel results

Each cell shows the share of available points earned by the row model against the column model: a win is worth 100%, a tie 50%, and a loss 0%. This result matrix uses only the compatible evaluation protocols included in the main ranking.

Directional matrix of points earned in direct duels. Values above 50% favour the row model; values below 50% favour the column model.

0 %100 %

💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Points earned in direct duels by model pair
Model

Published duel coverage

Each cell shows how many published AI-judged duels across all published evaluation protocols compare the two models for this language and category. The models on both axes are candidates; this matrix does not show which judge produced each verdict.

Symmetric matrix of published duel counts. The diagonal is zero because a model is not compared with itself.

0

💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Published duel counts by model pair
Model

Help elect the best LLM for writing in English

Which model writes the better text? Judge this anonymous pair and contribute to the human ranking. Model names stay hidden during the duel and are revealed only after your choice.

Arena